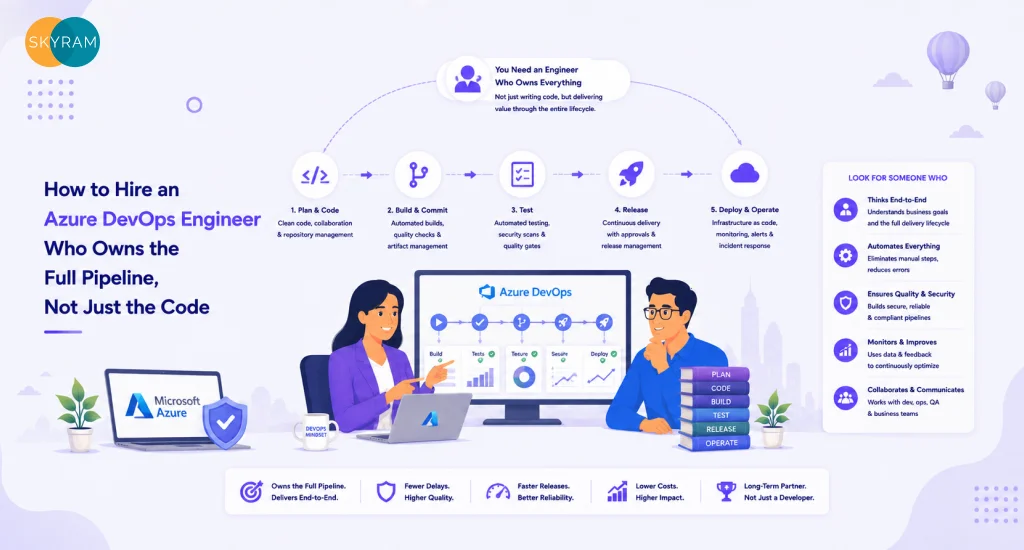
How to Hire an Azure DevOps Engineer Who Owns the Full Pipeline, Not Just the Code

How to Hire an Azure DevOps Engineer

Hiring an Azure DevOps engineer who owns the full pipeline means finding someone who manages CI/CD pipeline architecture, infrastructure as code with ARM templates or Bicep, environment configuration and secrets management, monitoring with Azure Monitor, and incident response, not just someone who can write YAML for a build stage. Most Azure DevOps candidates are strong on the code side of the pipeline and thin on the operational ownership side.

You have probably seen this play out. The pipeline runs clean in development. Deployments to staging work. The engineer who built it delivers a handoff document and considers the job done. Then production has a Sunday outage, Azure Monitor fires an alert that nobody configured a receiver for, and your on-call engineer finds themselves reverse-engineering an environment they did not build and cannot describe from memory. The problem was not that you hired the wrong person for the build. The problem was that you hired for implementation and expected ownership.

This guide gives you a structured evaluation framework for surfacing full-stack pipeline ownership before you make an offer. The interview questions, technical exercises, and role clarity decisions covered here are the practical tools that separate an adequate hire from an engineer who genuinely takes the whole pipeline as their responsibility.

What Full Pipeline Ownership Actually Means in an Azure Environment

Before you can evaluate for full pipeline ownership, you need a crisp definition of what it includes. Most hiring managers have an implicit picture of this, but candidates who lack operational depth are skilled at filling the gaps with confident-sounding answers about tools they have used but never owned in production.

CI/CD Pipeline Architecture, Not Just Build Configuration

There is a meaningful difference between writing pipeline stages and architecting a pipeline. Architecture means making explicit decisions about stage sequencing, approval gates between environments, artifact versioning strategy, rollback triggers, and deployment frequency policy. An engineer who owns CI/CD architecture can explain why a deployment gate exists between staging and production, what conditions trigger a rollback, and how the pipeline behaves when an approval expires without action.

Build configuration is a subset of that. Candidates who have only done configuration can describe what the YAML does. Candidates who have done architecture can explain what the YAML was designed to prevent. The distinction surfaces in how they answer questions about failure modes, not just about features. A strong CI/CD pipeline architecture starts with environment promotion logic and ends with a documented runbook, not a merged pull request.

Infrastructure as Code: ARM Templates, Bicep, Terraform on Azure

Full pipeline ownership in an Azure environment requires that infrastructure itself lives in version control. Engineers who provision resources through the Azure portal are not operating at production scale. Ask for repository links. Ask what the branching strategy looks like for infrastructure changes. Ask how they handle a state conflict in Terraform or a parameter file mismatch in Bicep.

The specific tool matters less than the practice. ARM templates, Bicep, and Terraform on Azure each have tradeoffs, and senior engineers have opinions about those tradeoffs based on actual project experience. An engineer who deflects this question with “we used whatever the client had” has done implementation work, not ownership work.

Monitoring, Alerting, and Incident Response Ownership

Monitoring is the clearest proxy for operational ownership. Engineers who own their pipelines build the alerting themselves. They configure Azure Monitor metric alerts, set up action groups, write alert rules for deployment failures, and define thresholds for infrastructure health metrics. Engineers who hand off to an SRE team after the pipeline runs do not.

Ask specifically: who configured the Azure Monitor alerts on your last production pipeline? What action groups are attached? What is the alert routing path at 2 AM? If the candidate cannot answer this for their own pipeline, they were not the owner. They were a contributor. Understanding the full scope of cloud engineering responsibilities including observability design is what separates a builder from an owner.

Secrets Management: Azure Key Vault Integration as a Baseline Expectation

Hardcoded credentials in pipeline YAML files are a category of mistake that engineers with real production ownership do not make more than once. Azure Key Vault integration in pipelines is not an advanced topic. It is a baseline expectation for any engineer claiming ownership of a production Azure environment. The evaluation question is not whether they have used Key Vault. The question is whether they can describe the service principal configuration, the access policy or RBAC role assignment, and the rotation strategy for secrets that pipelines consume.

Key Takeaway: Full pipeline ownership in Azure covers four domains: multi-stage CI/CD architecture with defined promotion logic, infrastructure as code in version control, monitoring and alerting ownership from configuration through incident routing, and secrets management via Azure Key Vault. Candidates who can articulate their specific contributions to all four have genuine ownership experience. Candidates who go quiet on monitoring and IaC have implementation experience.

The Certification Reality: What AZ-400 Signals and What It Doesn’t

The AZ-400 (Microsoft Certified: DevOps Engineer Expert) is a real credential with real signal value. It is also commonly misread as a proxy for operational depth it does not actually certify.

What the Azure DevOps Engineer Expert Certification Actually Tests

The AZ-400 tests design and implementation knowledge across a defined set of domains: designing and implementing pipelines, implementing security and compliance in pipelines, managing source control and code quality, and facilitating team communication and collaboration. The exam is scenario-based and covers Azure Pipelines, GitHub Actions, Azure Artifacts, Azure Boards, and related services with genuine depth.

Passing the AZ-400 means the candidate understands how to design and implement Azure DevOps tooling. That is a meaningful qualification. It is not, however, a test of operational ownership, production incident handling, infrastructure state management, or on-call accountability.

The Operational Ownership Gap That Certification Doesn’t Cover

The AZ-400 does not assess whether a candidate has configured production alerting. It does not test their ability to triage a failed deployment at 3 AM. It does not cover how they would approach a Terraform state drift between staging and production. It does not ask about runbook authorship, on-call rotation design, or post-incident review practice.

These are not obscure edge cases. They are the day-to-day operational responsibilities that define whether an Azure DevOps engineer is a pipeline builder or a pipeline owner. Certifications validate knowledge. Ownership is demonstrated through operational history.

How to Verify Pipeline Architecture Depth Beyond the AZ-400

After you confirm the AZ-400, move to architecture depth questions that the certification cannot prepare someone to fake. Ask for a sanitized architecture diagram from a production pipeline they designed. Ask them to walk you through a specific multi-environment deployment they architected and the decisions they made about environment promotion gates. Ask what they would change if they could redesign it from scratch and why.

The quality of their answer to that last question tells you more than their exam score. Engineers who have genuinely owned a pipeline have opinions about what they would have done differently. Engineers who implemented someone else’s design do not.

AZ-400 Certified Profile vs. Full Pipeline Ownership Profile

Dimension AZ-400 Certified Profile Full Pipeline Ownership Profile
CI/CD Pipeline Knowledge Understands design and implementation of Azure Pipelines and GitHub Actions Can architect multi-stage pipelines with environment promotion gates, rollback triggers, and approval expiry logic
Infrastructure as Code Familiar with IaC concepts; may have implemented existing templates Bicep or Terraform in version control; can explain branching strategy and state management
Monitoring and Alerting Aware of Azure Monitor and Application Insights Personally configured alert rules, action groups, and incident routing for production workloads
Secrets Management Knows Key Vault exists and integrates with pipelines Can describe service principal configuration, RBAC role assignments, and secret rotation strategy
Incident Response Has studied incident response concepts Has been on-call, responded to production incidents, and written post-incident reviews
Evaluation Signal Strong for tooling knowledge and implementation readiness Strong for operational maturity and production ownership
Hiring Use Case Mid-level DevOps engineer who needs operational mentorship Senior DevOps engineer who can own the full pipeline without supervision

Key Takeaway: AZ-400 is a useful filter, not a sufficient one. Use it to confirm tooling knowledge, then layer in operational evaluation questions to assess whether the candidate has actually owned pipelines in production or has primarily implemented them.

The Technical Evaluation That Surfaces Full Pipeline Ownership

Resumes and interviews surface what candidates know. Technical exercises surface what they actually do. The three exercises below are designed to expose the gap between implementation familiarity and operational ownership. Each one has a scoring dimension that certifications and resume screens cannot replicate.

Architecture Scenario: Design a Multi-Stage Pipeline with Environment Promotion Gates

Give the candidate a realistic scenario: a SaaS application deploying to development, staging, and production on Azure. Ask them to design a multi-stage pipeline that enforces environment promotion logic, handles approval workflows, and defines rollback conditions.

What you are evaluating: the quality of their environment gate design. Strong candidates define specific approval conditions, describe how expired approvals are handled, specify what artifact versioning strategy ties the build to the deployment, and explain how rollback is triggered and what state it restores. Candidates who describe a basic three-stage pipeline without addressing failure modes or rollback have implementation experience. Candidates who ask clarifying questions about release frequency, deployment frequency targets, and change failure rate tolerance have ownership experience. This kind of architecture thinking is what makes Azure DevOps and cloud automation services reliable at scale.

Incident Scenario: Production Deployment Broke. Walk Me Through Your Response

Give a concrete scenario: a production deployment completed successfully in Azure Pipelines but the application is returning 502 errors. Azure Monitor fired an alert 8 minutes after deployment. Walk me through your response.

What you are evaluating: their mental model for incident response at the pipeline layer. Strong candidates immediately check the deployment itself, not just the application. They look at the container registry pull, the AKS rollout status or App Service deployment log, the Azure Monitor alert details, and Application Insights live metrics before escalating. They can describe how they would decide between a rollback and a forward fix. They have a clear communication path in mind. Candidates who say “I would check the logs” without specificity have not owned a production incident. Familiarity with DevOps operations and incident patterns in live Azure environments is what distinguishes responders from observers.

IaC Exercise: How Would You Manage Environment Drift Across Dev, Staging, and Production?

Ask the candidate how they would detect and prevent configuration drift between their development, staging, and production Azure environments when infrastructure is managed with Terraform or Bicep.

What you are evaluating: whether they have dealt with drift in a real environment or only in theory. Strong candidates describe specific drift detection mechanisms: Terraform plan output in CI as a drift check, Bicep what-if deployments, Azure Policy as a guardrail layer, or custom comparison scripts that run on a schedule. They describe how they handle the delta between what the plan proposes and what the current state actually is. They have opinions about where state is stored and why. Candidates who say they “use version control” without addressing detection and remediation have not faced real drift in production.

Key Takeaway: Technical evaluations for full pipeline ownership should include architecture design, incident response, and IaC state management scenarios. Each one has a clear signal: architecture depth reveals decision-making maturity, incident response reveals operational history, and IaC drift management reveals whether they have owned environments through operational complexity, not just through the initial build.

The On-Call and Incident Response Expectations to Set Upfront

One of the most common sources of misaligned expectations after an Azure DevOps hire is on-call scope. Most candidates assume some level of on-call responsibility. Most hiring managers assume a level of on-call ownership that was never explicitly discussed. This conversation needs to happen before an offer, not after a production incident.

What Response Time and Resolution Ownership Look Like at the Pipeline Layer

Full pipeline ownership includes pipeline-layer on-call responsibility. When a deployment fails at 11 PM and the application team is blocked, someone owns the decision to investigate, rollback, or escalate. That person should be the Azure DevOps engineer who owns the pipeline, not whoever happens to be available.

Be explicit about response time expectations during the hiring process. Define what constitutes a pipeline-layer incident versus an application incident. Clarify whether the Azure DevOps engineer has resolution authority or advisory authority when production is affected. Candidates who have been through production incidents know these questions exist and will ask them themselves if you do not raise them first. Their willingness to engage with these expectations directly is a signal of genuine operational experience.

Runbook Ownership as a Hiring Requirement, Not a Post-Hire Expectation

Runbooks are operational documentation that describe how to respond to specific incidents, failures, or maintenance events at the pipeline and infrastructure level. Engineers who own their pipelines write runbooks. Engineers who only implement pipelines do not.

Make runbook ownership an explicit requirement in the job description, not a hope you have after the person starts. During evaluation, ask to see a runbook they authored. It does not need to be from a current employer. A sanitized or anonymized example from a personal project is sufficient. The quality and specificity of the runbook tells you whether the person thinks in operational terms or only in implementation terms.

A candidate who says “we didn’t do formal runbooks” and cannot describe an informal equivalent has not owned production operational responsibilities. A candidate who describes their runbook structure, revision cadence, and incident trigger mapping has. Kubernetes cluster operations and container orchestration ownership require the same kind of documented, executable operational practice.

Key Takeaway: On-call expectations and runbook ownership should be explicit hiring criteria, not implicit assumptions. Candidates with genuine operational experience will engage with these conversations willingly. Candidates without it will give vague answers about “collaborating with the team.”

Staff Augmentation as a Fast Path to Senior Azure DevOps Capability

For engineering teams that need senior Azure DevOps ownership without the four-to-six month timeline of a full-time hire, staff augmentation through a DevOps-specialized partner is a practical alternative.

Staff augmentation places a senior Azure DevOps engineer on your team with defined scope, defined deliverables, and defined operational responsibilities. The engagement can cover the full pipeline ownership definition described in this guide: CI/CD architecture, IaC, monitoring configuration, Key Vault integration, and on-call protocols. The cost structure is typically project-based or monthly, which means you carry senior capability without the full-time salary, benefits, and recruiting cost.

The tradeoff worth acknowledging: staff augmentation does not replace the institutional knowledge that builds over time with a full-time hire. If your Azure DevOps function is a long-term strategic capability, you will eventually need a full-time owner. Staff augmentation is the right model when your hiring timeline is longer than your delivery need, when you need a specific specialization for a defined scope, or when your organization is evaluating Azure DevOps ownership before building a permanent function.

Skyram Technologies works with US engineering teams specifically on this augmentation model, providing Azure DevOps engineers who own the full pipeline from CI/CD architecture through incident response and operational documentation. This is particularly effective for teams that need AKS-integrated pipelines, Bicep or Terraform IaC governance, or Azure Monitor observability built from scratch rather than inherited.

Key Takeaway: Staff augmentation is a legitimate operational model for senior Azure DevOps ownership, not just a stopgap. Evaluate it against your actual hiring timeline and delivery requirements, not just as a fallback when hiring fails.

When to Split the Role: Azure DevOps Engineer vs. Azure Platform Engineer

At a certain scale of Azure infrastructure, a single Azure DevOps engineer cannot reasonably own both the software delivery pipeline and the underlying platform. The question of when to split the role is one that most engineering organizations answer reactively, after one person is clearly overwhelmed, rather than proactively, based on workload indicators.

An Azure DevOps engineer’s core ownership is the software delivery lifecycle: CI/CD pipelines, artifact management, deployment automation, environment promotion logic, and the operational health of the delivery process itself. An Azure Platform Engineer’s core ownership is the infrastructure that the delivery process runs on: Azure Kubernetes Service cluster operations, virtual network topology, Azure Policy governance, cost management, and platform-level reliability.

The split becomes necessary when the platform itself demands more operational attention than one person can provide alongside active pipeline development and maintenance. Common indicators include AKS cluster upgrades becoming a full-week undertaking, networking and RBAC decisions requiring dedicated architectural attention, or cost governance becoming a separate reporting function.

For most teams at the 10-to-50 engineer scale, a single senior Azure DevOps engineer with strong IaC and platform skills can own both functions. At 50-plus engineers deploying multiple products to Azure, the separation typically generates more value than the coordination overhead it introduces. The evaluation and hiring frameworks in this guide apply to both roles, with the expectation that the platform engineer skews harder toward infrastructure architecture and the DevOps engineer skews harder toward delivery pipeline ownership.

Exploring Skyram’s Azure cloud solutions and DevOps services gives engineering leaders a clearer picture of where augmented expertise can bridge this split before headcount justification for both roles is approved.

Key Takeaway: The Azure DevOps engineer and Azure Platform Engineer roles share significant overlap at small scale and diverge at medium-to-large scale. The split decision should be workload-driven, not title-driven. Define which ownership domains your team needs covered before writing either job description.

Frequently Asked Questions

  1. What is the difference between an Azure DevOps engineer and an Azure Platform engineer?

An Azure DevOps engineer primarily owns the software delivery lifecycle on Azure: CI/CD pipelines built in Azure Pipelines or GitHub Actions, release management, artifact versioning, deployment automation, and the operational health of the delivery process. An Azure Platform engineer owns the infrastructure that those pipelines run on, including Azure Kubernetes Service cluster management, virtual network design, Azure Policy governance, RBAC configuration, and platform-level reliability. At small team scale, one senior engineer can cover both domains. At larger scale, the roles typically split because each domain requires dedicated operational attention. The clearest way to distinguish the two in a hiring context is to ask: does this person own the pipeline or the platform it runs on? Full-stack ownership candidates who credibly answer both questions command a higher evaluation bar.

  1. What should I ask an Azure DevOps engineer in a technical interview to evaluate real pipeline ownership?

Three questions that reliably separate implementers from owners: First, ask them to describe a multi-environment pipeline they architected and the specific decisions they made about environment promotion gates and rollback conditions. Second, present a production incident scenario where a deployment completed but the application is returning 500 errors, and ask for their step-by-step response starting from the Azure Pipelines run log. Third, ask how they detected and remediated configuration drift between their staging and production Azure environments. Candidates with genuine ownership experience answer all three with specificity about tools, configurations, and outcomes. Candidates with implementation experience give process descriptions without operational detail.

  1. Is AZ-400 certification enough to verify that an Azure DevOps engineer can own a production pipeline?

No. The AZ-400 (Microsoft Certified: DevOps Engineer Expert) validates knowledge of Azure DevOps tooling and pipeline design concepts. It does not certify operational experience, production incident response, IaC state management, or on-call accountability. A certified candidate may have strong implementation skills and limited ownership experience. The certification is a useful filter for confirming tool familiarity, but it needs to be supplemented with scenario-based interview questions, a technical architecture exercise, and direct questions about on-call history, monitoring configuration, and runbook authorship. Use the AZ-400 to shortlist, not to qualify.

  1. What on-call expectations should I set when hiring an Azure DevOps engineer for full pipeline ownership?

Set these expectations explicitly before an offer, not after the first production incident. Define what constitutes a pipeline-layer incident versus an application incident, clarify whether the DevOps engineer has resolution authority or advisory authority during production events, and establish expected response times by severity level. Full pipeline ownership means the engineer is the primary responder when a deployment fails and the application team is blocked, not when the problem has already been escalated to a separate SRE function. Candidates who have genuine production ownership experience will ask these questions themselves during the interview process. Those who do not raise them have likely not been primary responders in a production incident.

  1. How much does Azure DevOps engineer staff augmentation cost compared to a full-time hire, and how quickly can it be in place?

Azure DevOps engineer staff augmentation through a specialized DevOps partner typically runs between $8,000 and $18,000 per month for a senior engineer, depending on scope, specialization depth, and engagement model. Full-time senior Azure DevOps hires in the US market typically command $140,000 to $180,000 in base salary, plus benefits, recruiting costs, and a hiring timeline that averages 12 to 20 weeks from first outreach to start date. Staff augmentation can place a senior engineer on your team within two to four weeks and provides flexibility to scale scope without a permanent headcount commitment. The model works best when your delivery need is immediate and your hiring timeline is long, when you need a specific Azure specialization for a defined scope, or when you are evaluating the function before building a permanent team. Book a conversation with Skyram Technologies to scope a staff augmentation engagement against your specific Azure DevOps requirements.

Ready to Close the Pipeline Ownership Gap on Your Azure Team?

The pipeline ownership problem in Azure DevOps hiring is systematic, not accidental. Most job descriptions screen for implementation competency. Most interview processes do not test for operational accountability. The result is engineers who build clean pipelines and hand off operational responsibility to whichever team responds to the next incident.

The evaluation framework in this guide gives you a practical alternative: specific technical exercises, concrete interview questions, and explicit pre-hire conversations about on-call scope and runbook ownership. Pair that with a clear view of when to split the Azure DevOps and Azure Platform Engineering functions, and you have a hiring process that surfaces real ownership before you make an offer.

If your Azure DevOps hiring timeline is longer than your delivery need, or if you need senior pipeline ownership in place while you build a permanent team, Skyram Technologies works with US engineering leaders on Azure DevOps staff augmentation and Azure cloud engineering engagements scoped around full pipeline ownership, not just build configuration.

Talk to Skyram about Azure DevOps engineering resources

How to Choose an AWS Cloud Services Partner That Won’t Disappear After Go-Live

How to Choose an AWS Cloud Services Partner

The migration was clean. The architecture review passed. The go-live cutover ran on schedule and under budget. Three months later, an IT Director is fielding a P1 incident at 11 PM on a Friday, and their AWS partner’s account manager responds the next business day with a note clarifying that post-launch support was not included in the engagement scope.

The architecture did not fail. The contract did.

This is the most common and most preventable failure mode in AWS partner engagements. The partner delivered exactly what was scoped. The scope was delivery, not operations. The internal team inherited a complex new environment with no runbooks, no incident response protocol, and no escalation path to someone who actually built it.

Choosing an AWS cloud services partner that sustains engagement after go-live means evaluating their post-launch support model, SLA commitments for ongoing operations, incident response protocols, and knowledge transfer practices before the engagement starts. Most AWS partner failures are not technical. They are contractual. When the build is done, the partner disappears, and the internal team inherits an environment they do not fully understand.

This guide covers the specific questions to ask, contract provisions to demand, and evaluation criteria to apply before you sign.

The Post-Launch Support Gap That Most AWS Partner Contracts Don’t Cover

Build vs. operate: how most AWS partner scopes end at delivery

Standard AWS partner engagements are scoped around a deliverable: a migration, an architecture build, a security review, a cost optimization sprint. The engagement ends when the deliverable is accepted. Ongoing operations are a separate conversation, and most partners expect you to initiate it.

The problem is that most IT leaders assume operational continuity is implied by a successful delivery. It is not. Unless ongoing managed services are written into the contract with defined scope and SLAs, delivery is where the relationship legally ends.

What an internal team actually needs to inherit a new AWS environment

Inheriting a new AWS cloud environment without proper knowledge transfer puts your internal team in an impossible position. They did not design the architecture. They were not in the room for every technical decision. They do not know which services are load-bearing and which are experimental, or what the failover sequence is when a specific component goes down.

At minimum, a responsible handover includes architecture documentation in a format your team can actually navigate, runbooks for the ten most likely operational scenarios, a secrets and access management guide, cost anomaly alert configurations with defined thresholds, and at least one live walkthrough session where the engineers who built it explain what they built and why.

Most project-based engagements deliver none of these by default. They require explicit contractual specification.

The incident response vacuum that appears in week one of post-launch operations

The first production incident after go-live is the moment that exposes whether your AWS partner engagement was structured correctly. If your team has runbooks, alert routing, and an escalation path to someone with environment context, the incident gets handled. If none of those things exist, the incident becomes a crisis because your team is debugging an environment they are still learning while a production system is down.

This vacuum is predictable and preventable. The only way to close it is to require incident response support as a written contract deliverable before go-live, not as a verbal assurance that your partner will pick up the phone if something goes wrong.

What to Demand in an AWS Partner Engagement From Day One

Ongoing managed services vs. project-based delivery: what each includes post-launch

Knowing which engagement model you actually need before you evaluate partners is the foundational decision. A project-based engagement delivers a defined output on a fixed timeline. A managed services engagement delivers ongoing operational ownership with continuous monitoring, incident response, and environment management as part of the scope.

The critical difference is not cost. It is accountability. In a managed services engagement, someone is accountable for uptime. In a project-based engagement, the partner is accountable for delivery quality, and accountability for uptime transfers entirely to your team on day one of go-live.

Neither model is wrong. But choosing the wrong one for your organization’s internal capacity is how you end up in the 11 PM incident scenario described above.

SLA requirements for infrastructure incidents, performance degradation, and cost anomalies

If you engage a partner for ongoing operations, demand specific SLA language for three categories: infrastructure incidents by severity tier (P1 through P4), performance degradation alerts with response time commitments, and cost anomaly notifications with a defined threshold and response protocol.

Vague language like “24/7 support” and “rapid response” is not an SLA. An SLA specifies the maximum time between incident detection and acknowledgment, between acknowledgment and active remediation, and between remediation start and resolution for each severity tier. Require this in writing before contracting.

Knowledge transfer deliverables: runbooks, architecture documentation, escalation protocols

Make documentation a milestone-gated contract deliverable, not a post-engagement courtesy. Specify what documents must exist, what format they must be in, and when they must be delivered relative to go-live. Require partner sign-off that the documentation is accurate and complete as a condition of final payment.

A cloud engineering engagement that produces no usable documentation is an engagement that created dependency, not capability. Your team should be able to operate the environment confidently 90 days after the partner’s active involvement ends.

Comparison Table: Project-Delivery AWS Partner vs. Managed AWS Partner

Dimension Project-Delivery Partner Managed AWS Partner
Scope Defined deliverable with acceptance criteria Ongoing operational ownership with defined SLAs
Post-launch coverage None unless separately contracted Included: monitoring, incident response, patching
Internal team dependency High: team inherits full operational load at go-live Low: partner retains operational accountability
Documentation Varies; often minimal without explicit contractual requirement Typically structured as part of ongoing engagement
Cost structure Fixed project fee Monthly retainer or consumption-based
Escalation path post-go-live None by default Defined contractually with response time commitments
Best fit Organizations with strong internal cloud ops capacity Organizations without dedicated cloud operations resources

The Contract Provisions That Prevent Post-Launch Abandonment

Operational SLA tied to response time and resolution time

Write SLA commitments into the master services agreement, not the statement of work. Statements of work define project scope and can expire. Master agreements govern the ongoing relationship. Operational SLAs belong in the document that survives the project.

Documentation deliverable schedule with milestone-based acceptance

Attach documentation deliverables to payment milestones. If final payment requires delivery of a complete runbook package, architecture diagrams, and a live walkthrough session, your partner has a financial incentive to produce them on time and at the quality level specified.

Transition support clause: minimum engagement period post-go-live

Require a defined post-go-live support window in the contract, typically 30 to 90 days during which the partner maintains active operational responsibility alongside your team. This is the window during which your team learns the environment under live conditions with expert support available. It is not an optional add-on. It is the difference between a successful handover and an inherited problem.

How to Evaluate an AWS Partner’s Post-Launch Track Record

Ask for references specifically about post-launch operations, not the build

When you call an AWS partner’s references, ask one question first: what happened six months after go-live? Most partners will give you references who can speak to delivery quality. Fewer will give you references who can speak to what operational support looked like after the engagement technically ended. Ask specifically for a reference from a client who ran into a production issue after go-live and needed partner support. How the partner responded in that moment is more predictive of your experience than how clean the migration was.

How do they handle cost anomaly alerts after the engagement formally ends?

AWS cost anomalies can appear weeks or months after go-live as traffic scales, reserved instance commitments expire, or configurations drift from their original state. Ask your prospective partner directly: if my AWS bill spikes 40 percent three months after our engagement ends, what is your process? A partner who has a defined answer, even a paid incident review, is materially better positioned than one who does not have an answer at all. The answer tells you whether post-launch operations are part of their operating model or entirely outside it.

What does their standard runbook deliverable look like?

Ask to see an anonymized runbook from a previous engagement. Not a description of what a runbook contains. An actual document. A strong runbook covers at least ten common operational scenarios with step-by-step resolution procedures, tool-specific commands, escalation contacts, and rollback instructions. A weak runbook is a two-page document with bullet points describing what each service does.

The quality of the runbook is the single most reliable proxy for whether a partner is building your team’s capability or their own indispensability.

AWS Managed Services vs. Internal Operations: The Hybrid Model Most IT Leaders End Up Using

Pure internal cloud operations require a dedicated cloud ops team with AWS certifications, on-call rotation coverage, and deep environment knowledge. For most IT organizations outside of large enterprise, this is an unrealistic staffing model.

Pure external managed services mean your internal team loses environment familiarity over time and becomes dependent on the partner for every operational decision.

The model most IT leaders actually land on is a hybrid: the managed services partner handles monitoring, alerting, and incident response, while the internal team handles day-to-day configuration changes, cost reviews, and application-level decisions. The partner is the operational backbone; the internal team is the business context layer.

Getting this split right requires defining it explicitly in the engagement structure, not discovering it organically through six months of ambiguous ownership. A well-structured cloud services engagement documents the operational ownership model from day one so neither side inherits surprises.

Cost Optimization as an Ongoing Function, Not a One-Time Engagement

AWS cost optimization is not something you complete. It is something you operate. Reserved instance terms expire. Savings Plans need renewal and adjustment. Traffic patterns shift. New services get provisioned and forgotten. Auto-scaling configurations drift from their original tuning.

A partner who scopes cost optimization as a one-time audit and leaves is not solving your cost problem. They are delaying it by a few months.

Demand cost optimization as a defined ongoing function in any managed services engagement. Specify that cost reviews happen on a defined cadence, that anomaly alerts are configured and routed to a named contact, and that reserved capacity planning is revisited at least quarterly. The AWS bill is not a static artifact of your architecture. It is a live indicator of how well your environment is being managed, and it should be treated that way from the first day of the engagement.

Skyram Technologies structures its AWS and DevOps engagements around this principle: operational accountability does not end at go-live. Monitoring, cost governance, incident response, and documentation transfer are built into the engagement model from day one, not added as optional extras after the build is done.

Frequently Asked Questions

  1. What should I look for in an AWS cloud services partner to ensure they provide post-launch support?

When evaluating an AWS cloud services partner for post-launch support, an IT Director or CTO should look for three specific things: a written managed services option with defined SLAs for incident response by severity tier, documentation deliverables listed as milestone-gated contract items rather than implied courtesies, and a transition support clause requiring the partner to maintain active operational involvement for a defined period after go-live. Partners who cannot specify their post-launch support model in contract language before signing are partners whose support model does not exist.

  1. What is the difference between a project-based AWS partner and a managed AWS services partner?

A project-based AWS partner delivers a defined output, such as a migration, architecture build, or security review, and their contractual obligations end when the deliverable is accepted. A managed AWS services partner maintains ongoing operational ownership of the cloud environment, including monitoring, incident response, patching, and cost anomaly management, under defined SLAs. The key difference is not the quality of the technical work but the scope of accountability after go-live. Project-based engagements transfer full operational responsibility to the internal team on day one of go-live. Managed services engagements retain partner accountability for ongoing operations.

  1. What SLAs should an AWS partner provide for cloud infrastructure support?

An AWS partner providing infrastructure support should specify SLAs across three categories. First, incident response SLAs by severity tier: the maximum time from incident detection to acknowledgment, and from acknowledgment to active remediation, for P1 through P4 severity levels. Second, performance degradation alert response times. Third, cost anomaly notification thresholds and response protocols. Language like “24/7 support” or “rapid response” without numeric commitments is not an SLA and should not be accepted as one.

  1. What documentation should an AWS partner deliver at the end of an engagement?

At minimum, an AWS partner should deliver complete architecture diagrams for all environments, runbooks covering the ten to fifteen most common operational scenarios with step-by-step resolution procedures, a secrets and access management guide, cost anomaly alert configurations with defined thresholds, an incident escalation contact matrix, and a live walkthrough session with the engineers who built the environment. Documentation that cannot be acted on without the partner’s interpretation is documentation that serves the partner’s interests, not the client’s.

  1. How do I evaluate an AWS partner’s post-launch experience before signing?

Request references specifically from clients who experienced a production incident or cost anomaly after the engagement formally ended, and ask how the partner responded. Ask to see an anonymized runbook from a previous engagement to evaluate documentation quality directly. Ask the partner to describe their process when a client’s AWS bill increases significantly three to six months post-go-live. A partner with defined answers to these questions has a post-launch support model. A partner who responds vaguely does not.

  1. What is a transition support clause and why does it matter in an AWS partner contract?

A transition support clause is a contract provision that requires the AWS partner to maintain active operational involvement for a defined period after go-live, typically 30 to 90 days. During this period, the partner retains responsibility for incident response and environment support while the internal team learns the new environment under live conditions. Without a transition support clause, the partner’s obligations end the moment the go-live milestone is accepted, leaving the internal team to manage a new and unfamiliar environment without available expert support from the people who built it.

Talk to Skyram About AWS Cloud Services and Managed Operations

If you are evaluating AWS partners for a migration, architecture project, or ongoing managed operations, the conversation should start with post-launch support, not end there. Skyram Technologies structures AWS engagements with defined operational SLAs, documentation deliverables, and managed services models built to sustain your environment long after go-live.

Book a conversation with our AWS team and bring your current partner evaluation criteria. We will tell you what is missing.

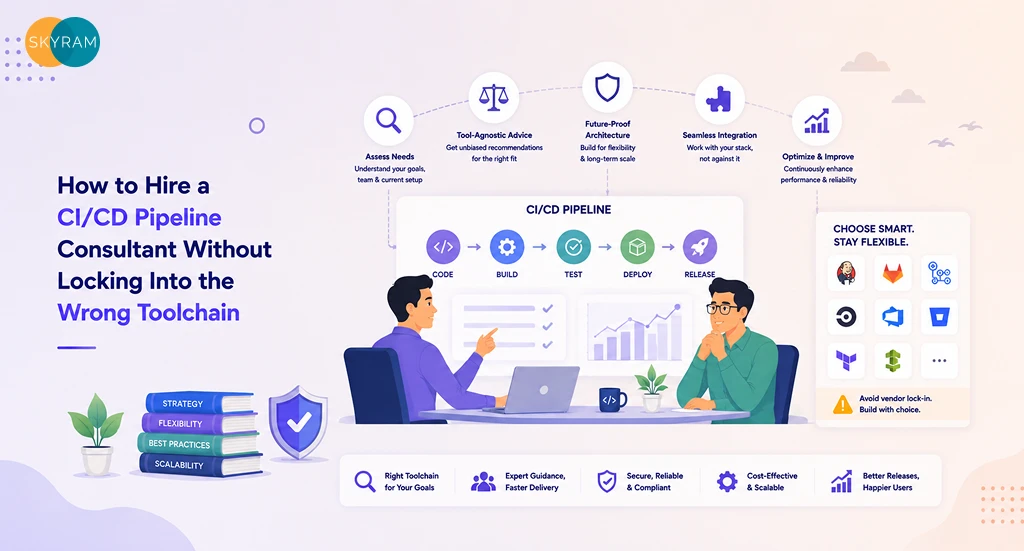
How to Hire a CI/CD Pipeline Consultant Without Locking Into the Wrong Toolchain

VP of Engineering reviewing CI CD pipeline architecture diagram with toolchain selection criteria on whiteboard

Most engineering teams discover the toolchain problem six months too late. The CI/CD consultant they brought in was certified, moved fast, and delivered a functioning pipeline on time. What the engagement contract never clarified was that every architecture decision, every YAML configuration, every IaC module was written around the one platform the consultant had spent the last three years building expertise in. The recommendation was never really a recommendation. It was a default.

By the time the team realizes the pipeline is tightly coupled to a specific platform’s proprietary features, agents, or managed runners, the migration cost looks worse than staying put. Release cycles slow. Internal engineers spend their time maintaining a toolchain nobody fully owns. And every sprint that passes makes the eventual migration heavier.

This guide is the evaluation framework that prevents that outcome. It covers what a CI/CD pipeline consultant actually owns during an engagement, where toolchain lock-in quietly enters the picture, how to screen for platform-agnosticism before you sign anything, and when a managed delivery partner makes more sense than a single-consultant engagement.

What a CI/CD Pipeline Consultant Actually Owns

Most job postings conflate pipeline implementation with pipeline architecture. They are not the same scope, and the distinction matters before you hire.

Pipeline Architecture Design vs. Implementation Execution

A pipeline architect designs the system: what gets tested when, how environments are structured, how secrets management works, where rollback triggers sit, and how the pipeline scales as the codebase grows. An implementation consultant takes an approved design and builds it in a specific tool. Many consultants do both, but engineers who lead with implementation tend to default to the tool they know fastest, because architecture decisions happen early and informally in the engagement, often before formal discovery is complete.

When you hire, ask explicitly which role they are filling. If the answer is both, ask how they document architecture decisions before implementation begins. A good consultant produces a design document that is platform-agnostic at the conceptual level and only selects specific tooling after the architecture is agreed upon.

Tool Selection Rationale: What a Good Consultant Documents and Why

The platform recommendation is the highest-leverage decision in the engagement. A consultant who arrives with a preferred tool and reverse-engineers a justification leaves your team owning a rationale nobody can defend two years later. A consultant who documents a comparative evaluation, your existing stack, your team’s operational familiarity, your cloud provider’s native CI/CD capabilities, and the long-term maintenance cost of each option, gives your team a decision your engineers can defend, revisit, and update as the landscape shifts.

Require this documentation as a deliverable, not as an afterthought. If a consultant pushes back on formalizing tool selection rationale, that is the signal you need to see earlier rather than later.

The Handoff Problem: What Happens When the Engagement Ends

The most common post-engagement failure mode is not a broken pipeline. It is a pipeline that works fine until the first major change, at which point no one on the internal team knows how to modify it safely. A consultant who builds in proprietary agents, custom plugins, or undocumented workarounds creates dependency without disclosure.

Before signing, your statement of work should specify what handoff looks like: runbooks, architecture documentation, internal knowledge transfer sessions, and a list of every third-party plugin or custom integration included in the build. Teams that skip this step often find themselves re-engaging the same consultant for every significant pipeline change, which is the consulting equivalent of vendor lock-in.

Key Takeaway: A CI/CD pipeline consultant owns architecture design, tool selection rationale, and the knowledge transfer that makes your team self-sufficient after the engagement ends. Make all three explicit in the contract.

The Toolchain Lock-In Risk Nobody Talks About in the Hiring Process

Toolchain lock-in in the CI/CD layer is not a vendor problem. It is a hiring problem. The vendor did not impose anything. Your consultant made choices that were never evaluated against your architecture.

How Platform Preference Masquerades as Recommendation

A consultant who primarily works with Jenkins will find legitimate reasons to recommend Jenkins. A GitHub Actions specialist will frame your GitHub repository usage as the reason GitHub Actions is the obvious choice. Neither is lying. Both are pattern-matching against their most familiar tool, and both are presenting a subjective preference as an objective fit assessment.

The tell is in the evaluation process. A genuinely platform-agnostic evaluation takes time. It requires the consultant to understand your current infrastructure, your cloud provider’s native CI/CD capabilities, your team’s operational bandwidth, and your compliance and security requirements before any platform is shortlisted. If a platform recommendation comes in the first week, before discovery is complete, it is not an evaluation. It is a preference.

Jenkins vs. GitLab CI vs. GitHub Actions vs. CircleCI: What Each Locks You Into

Each major CI/CD platform carries specific coupling risks that are worth understanding before your consultant recommends one.

Jenkins ties your team to plugin management, agent infrastructure, and a maintenance overhead that scales with pipeline complexity. The flexibility is real, but so is the operational burden. Teams without dedicated DevOps capacity often find Jenkins pipelines degrading over time as plugins fall out of maintenance cycles.

GitLab CI locks you into the GitLab ecosystem. If your codebase lives in GitLab, this coupling is a feature. If you are considering a future migration to GitHub or another version control system, your pipeline configuration does not travel with you cleanly.

GitHub Actions ties pipeline configuration to GitHub’s runner infrastructure and marketplace actions. The developer experience is excellent, but dependency on community-maintained actions creates security surface area that requires ongoing audit. Third-party actions with write permissions to your repository are a supply chain risk that many teams underweight at the hiring stage.

CircleCI offers strong parallelism and speed, but its orbs, executors, and resource class definitions are CircleCI-specific. A heavily optimized CircleCI pipeline does not port to another platform without significant rewrite.

Understanding these lock-in vectors does not mean avoiding any of these platforms. It means your consultant should be choosing between them based on your architecture, not their resume. That distinction is everything. If you are also evaluating cloud-native deployment patterns alongside your pipeline selection, Skyram’s CI/CD pipeline services page outlines the platforms and architectures the team uses across client engagements.

Infrastructure as Code Dependency and What It Means for Future Migrations

The CI/CD pipeline does not exist in isolation. It runs against infrastructure defined in Terraform, CloudFormation, Pulumi, or another IaC layer. A consultant who writes pipeline automation tightly coupled to a specific IaC tool, or who uses platform-specific resource classes that assume a particular cloud provider’s structure, creates a second layer of migration debt that compounds with the pipeline lock-in.

Ask your consultant how the pipeline references infrastructure. If the answer involves hardcoded resource ARNs, platform-specific environment variables, or cloud-provider-specific secret management that is not abstracted, your future migration will touch both layers simultaneously. That is a significantly larger engineering effort than either layer alone.

Key Takeaway: Toolchain lock-in enters through platform preference, ecosystem coupling, and IaC dependency. A qualified consultant treats all three as evaluation criteria before any recommendation is made.

The Evaluation Framework: What to Ask Before You Sign

The screening process for a CI/CD consultant should function like a technical architecture review, not a credentials check.

Platform-Agnostic vs. Platform-Specialized: How to Tell the Difference

Platform-agnostic consultants can describe the trade-offs of Jenkins, GitLab CI, GitHub Actions, and CircleCI in operational terms that are specific to your infrastructure. Platform-specialized consultants describe why the platform they know is a good fit for most scenarios. The framing is different and the difference is audible in the first technical conversation.

Ask the candidate to walk through how they would evaluate three platforms for your specific use case, before any recommendation. A specialist will converge quickly on their preferred tool with caveats. A generalist will ask clarifying questions about your infrastructure before committing to any shortlist.

How They Approach Tool Selection When Starting from Scratch

Starting from scratch is the highest-risk moment for toolchain lock-in, because there is no existing implementation pushing back against the consultant’s preferences. Ask specifically: what is their evaluation process when no platform has been selected yet?

A rigorous answer includes questions about your cloud provider and its native CI/CD support, your version control system, your team’s current tooling familiarity, your compliance requirements, whether you are working with containers and Kubernetes, and what operational workload your team can sustain after the engagement ends. A shallow answer describes a single tool as the industry standard and moves toward implementation planning.

Their Documentation and Knowledge Transfer Standards

Ask for examples of documentation from previous engagements, with sensitive details redacted. What does their runbook look like? How do they structure architecture decision records? What does a handoff session agenda look like? Teams that plan on maintaining the pipeline internally need documentation that their engineers can actually use. If the consultant cannot produce examples, they either do not produce documentation or they produce documentation that serves their own use rather than yours.

Platform-Agnostic Consultant vs. Platform-Specialized Consultant

Evaluation Criteria Platform-Agnostic Consultant Platform-Specialized Consultant
Tool recommendation timing After discovery and comparative evaluation Often in first week or proposal
Evaluation documentation Comparative analysis across 3 or more platforms Justification for preferred platform
Architecture decision records Documented before implementation Often informal or post-hoc
IaC coupling awareness Explicit discussion of IaC dependencies Often scoped to pipeline layer only
Handoff documentation Runbooks, ADRs, knowledge transfer sessions Variable; often informal
Post-engagement team self-sufficiency High Moderate to low
Lock-in risk Low Medium to high
Best-fit scenario Greenfield builds, migrations, multi-cloud environments Existing platform standardization, narrow scope engagements

Key Takeaway: The distinction between platform-agnostic and platform-specialized consultants shows up in process, documentation, and timing. The evaluation conversation, not the resume, is where you see the difference.

The Technical Screen for a CI/CD Consultant

Certifications confirm that a consultant passed a vendor’s assessment. They do not confirm that the consultant can design a pipeline architecture that fits your specific engineering environment. The technical screen needs to go deeper.

Architecture Review Over Certification

Present the candidate with a scenario that reflects your actual environment: your code volume, your deployment frequency target, your cloud provider, your container orchestration layer if relevant, and your compliance requirements. Ask them to describe a pipeline architecture for that scenario without committing to a specific platform until the design is agreed upon.

A strong answer produces a conceptual architecture first: stages, gates, environment promotion logic, artifact storage strategy, secret management approach. Platform selection comes after the architecture is defined. If the candidate jumps immediately to YAML configuration details for a specific tool, the architecture layer is not where they work.

If your infrastructure runs on Kubernetes, the Kubernetes solutions page covers how container orchestration interacts with pipeline design, including GitOps workflows, Helm chart-based deployments, and CI/CD integration patterns for containerized workloads.

How They Handle Rollback and Failure Scenarios

Rollback strategy is one of the most revealing questions in a CI/CD technical screen. Ask the candidate how they design for a deployment failure: what the rollback mechanism is, how it is tested, how fast it executes, and what state the system is left in after an automated rollback.

A thoughtful answer addresses both automated and manual rollback paths, the difference between a failed deployment and a failed release in their mental model, how they handle database migrations that cannot be automatically rolled back, and how monitoring integration signals a rollback versus a retry. A shallow answer describes a feature of the specific tool they prefer.

Security Scanning and Compliance Integration in Pipeline Design

The pipeline is not just a delivery mechanism. It is a security enforcement layer. Ask how the candidate integrates SAST, DAST, dependency scanning, container image scanning, and secrets detection into the pipeline without creating bottlenecks that slow release velocity.

Specifically ask how they handle compliance gates for regulated environments, whether they have experience designing pipelines for SOC 2, HIPAA, or PCI-DSS contexts, and how they approach security scanning in a parallel stage architecture to avoid adding latency to the critical path.

Teams that need this level of pipeline maturity alongside broader DevOps services often find that a consultant’s scope stops short of the full delivery environment, creating gaps in the operational picture.

Key Takeaway: The technical screen should test architecture thinking, rollback design, and security integration capability, not certification depth. Those three areas separate consultants who can design for your environment from consultants who can configure their preferred tool.

Engagement Models: Project-Based vs. Embedded vs. Managed

The engagement structure you choose shapes what the consultant can realistically deliver and what your team is left managing when the engagement ends.

A project-based engagement has a defined scope and a fixed end date. The consultant builds something specific, hands it off, and the engagement closes. This works well when your internal team has the capacity to own and operate the pipeline post-delivery and when the build scope is well-defined before the engagement starts. The risk is that discovery often reveals scope your team did not anticipate, and project-based engagements are not built to absorb ongoing change gracefully.

An embedded engagement places the consultant inside your engineering team for a set period. They attend standups, participate in architecture reviews, and make decisions alongside your internal engineers. This model is better suited to greenfield builds where architecture decisions are still in flux or to complex migrations where the path is not fully defined at the start. The handoff is smoother because internal engineers are involved throughout. The cost is higher because the engagement is longer, and your team’s attention is consistently required to make the collaboration productive.

A managed engagement shifts ongoing pipeline operations to an external team rather than transferring ownership to your internal engineers at a fixed point. This is not a consulting model. It is a delivery model, and it is appropriate when your internal team does not have the capacity or the interest in owning the pipeline operationally. The trade-off is that operational knowledge stays with the external team, which is its own form of dependency, though a more transparent one than the kind that emerges from an undocumented consultant engagement.

Hybrid models exist too: a project-based build followed by a retainer for ongoing support. These can work well when the build scope is tight and the operational surface is predictable, but they require explicit agreements about what the retainer covers and what falls outside it.

Key Takeaway: The right engagement model depends on your internal team’s capacity and the pipeline’s operational complexity. Define post-delivery ownership before the engagement starts, not after.

When to Bring In a Managed CI/CD Partner Instead of a Consultant

A single consultant engagement makes sense when the build scope is defined, your team can own the result, and the architecture decision has already been made or will be made collaboratively with the consultant. When any of those conditions are not true, a managed partner relationship often delivers better outcomes.

Teams with a high release frequency and no dedicated platform engineering headcount frequently find that a consultant builds a pipeline their team cannot maintain at the pace the deployment cadence requires. Every incident that falls outside normal operating parameters requires pulling the consultant back in. Every new service that needs pipeline integration reopens a scope conversation. The consultant-to-client relationship was designed for a discrete engagement, not for ongoing operational support of a critical delivery layer.

A managed CI/CD partner takes ownership of the pipeline operationally: platform selection, architecture, implementation, security scanning integration, rollback design, monitoring, and ongoing optimization as the codebase evolves. The relationship is a delivery partnership rather than a discrete project. The distinction matters because platform selection and toolchain decisions are made in the context of a long-term operational commitment, not a time-bounded engagement.

For engineering teams running multi-cloud workloads, the cloud engineering services layer sits directly below the CI/CD layer, and changes in cloud architecture frequently require corresponding pipeline updates. When cloud engineering and CI/CD are managed by the same team, architecture changes propagate through the pipeline without coordination overhead.

For teams evaluating whether a managed delivery model is the right fit, the AWS Cloud Services page covers how the delivery team approaches AWS-native CI/CD architecture alongside broader cloud infrastructure management.

Key Takeaway: A managed CI/CD partner makes sense when your team lacks the capacity to own the pipeline operationally, when release frequency is high, or when pipeline architecture is expected to evolve with a changing cloud environment.

Frequently Asked Questions

Q1: What is a CI/CD pipeline consultant and what do they do?

A CI/CD pipeline consultant designs and implements the automation infrastructure that moves code from a developer’s commit to a production environment. Responsibilities typically include selecting CI/CD tooling based on the team’s existing infrastructure, designing pipeline stages for build, test, and deployment, integrating security scanning and compliance checks, defining rollback strategies, and producing documentation that allows the internal engineering team to maintain the pipeline after the engagement ends. The scope varies by engagement: some consultants focus on architecture design, others on implementation, and some cover both.

Q2: How do I avoid CI/CD toolchain lock-in when hiring a consultant?

Toolchain lock-in is avoided by requiring a comparative evaluation before any platform is selected. A consultant who documents the trade-offs of at least two or three platforms, including Jenkins, GitLab CI, GitHub Actions, and CircleCI, against the organization’s specific infrastructure, team capacity, and compliance requirements, is applying an objective evaluation process. A consultant who arrives with a preferred platform and reverse-engineers a justification is applying a preference. Contracts should also require architecture decision records, runbooks, and knowledge transfer documentation as formal deliverables, and should specify which third-party plugins or custom integrations are included in the build.

Q3: What is the difference between Jenkins, GitLab CI, GitHub Actions, and CircleCI?

Jenkins is a self-hosted, open-source automation server with extensive plugin support, high customizability, and significant operational maintenance overhead. GitLab CI is the native CI/CD layer within the GitLab DevOps platform, tightly integrated with GitLab’s version control and project management tools. GitHub Actions is GitHub’s native automation platform, using YAML-defined workflows and a marketplace of community-maintained actions. CircleCI is a cloud-native CI/CD service known for pipeline speed and parallelism, using orbs for reusable configuration. Each platform carries distinct coupling risks: Jenkins to its plugin ecosystem, GitLab CI to the GitLab platform, GitHub Actions to GitHub’s runner infrastructure, and CircleCI to its proprietary resource class and orb definitions.

Q4: What questions should I ask a CI/CD consultant before hiring?

Key questions include: How do you evaluate CI/CD platforms against a client’s existing stack before making a recommendation? Can you walk through how you would design a rollback strategy for a failed deployment in our environment? What documentation do you produce as part of a standard engagement? How do you integrate security scanning without adding latency to the critical path? Can you show examples of architecture decision records from previous engagements, with sensitive details redacted? What does a knowledge transfer session typically cover? How do you handle IaC dependencies when designing pipeline automation? These questions surface architecture thinking, process discipline, and knowledge transfer standards, which are the three areas that separate a strong consultant from one who builds well but leaves teams dependent.

Q5: When should a company hire a CI/CD consultant versus a managed DevOps partner?

A single-consultant engagement is appropriate when the pipeline build scope is well-defined, the internal engineering team has the capacity to own the result operationally, and the architecture decision has been or will be made collaboratively. A managed DevOps partner is a better fit when the internal team lacks the bandwidth to own and maintain the pipeline at the required release cadence, when cloud architecture is expected to evolve and pipeline updates need to follow, or when ongoing security scanning, monitoring integration, and pipeline optimization require continuous attention beyond a single engagement’s scope. The distinction comes down to who owns the pipeline operationally after the initial build: if the answer is the external team, a managed delivery model is more appropriate than a discrete consulting engagement.

Ready to Build a Pipeline Architecture Your Team Actually Owns?

The wrong CI/CD engagement leaves your team with a working pipeline and a toolchain decision they cannot defend. Skyram’s pipeline architecture engagements start with a comparative platform evaluation against your existing infrastructure before any toolchain is selected, and every engagement closes with runbooks, architecture documentation, and knowledge transfer your engineers can actually use.

Talk to Skyram about CI/CD pipeline architecture

Cloud Engineering Partner vs. In-House Cloud Team: How US Companies Are Making the Call in 2026

Cloud engineering partner vs in house cloud team decision framework for US companies in 2026

Cloud engineering is one of the hardest technical disciplines to staff in the US market right now. The Bureau of Labor Statistics projects cloud computing and related infrastructure roles will grow at roughly twice the rate of the broader tech sector through 2030, yet the talent pool has not kept pace. The result is a market where a senior AWS architect with production-grade experience commands compensation packages north of $200,000 per year, interview cycles stretch to 90 days, and offer acceptance rates have dropped as candidates field competing offers simultaneously.

For CTOs and IT Directors, the calculus has become more complex. The traditional answer of “just hire a cloud team” runs into real constraints: time, budget, bench utilization, and the compounding risk that a single hire does not actually cover the multi-cloud surface area most modern infrastructure requires. The alternative, engaging a cloud engineering partner, introduces its own variables around accountability, governance, and knowledge continuity.

This post is not a vendor pitch. It is a decision framework built for technical leaders who need to make a binary call with significant cost and delivery implications. Both models work in the right context. Both fail in the wrong one. The variables that determine which is right for your organization are specific, and working through them systematically is the only way to reach a defensible answer.

What an In-House Cloud Team Actually Costs to Build

The first mistake most organizations make is scoping the cost of an in-house cloud team to salary alone. The real number includes recruiting, benefits, tooling, training, and the time value of slower-than-expected ramp. Before you sign off on headcount, here is what the full picture looks like.

Salary Benchmarks for Cloud Engineers Across AWS, Azure, GCP Specializations

As of 2026, market compensation for cloud engineers in the US varies significantly by platform specialization and experience level. AWS-certified Solutions Architects at the senior level average $155,000 to $190,000 in base salary. Azure-certified engineers with DevOps depth run slightly lower at $140,000 to $175,000. GCP specialists remain the most constrained segment by supply, which pushes compensation toward the $160,000 to $195,000 range for experienced practitioners.

Add benefits at the standard 25 to 30 percent multiplier on base, employer payroll taxes, tooling licenses, training budgets, and recruiting fees that typically land between 20 and 30 percent of first-year salary for specialized roles, and the fully loaded cost of a single senior cloud hire reaches $220,000 to $280,000 in year one. A three-person team covering AWS, Azure, and containerization through Kubernetes orchestration exceeds $700,000 annually before any infrastructure spend.

Time-to-Productivity for New Cloud Hires

The salary number is visible on a spreadsheet. The time-to-productivity gap is invisible until you feel it in delivery timelines.

Research from enterprise engineering benchmarking firms consistently shows that new cloud engineering hires reach full operational effectiveness at 6 to 12 months, depending on how well-documented the existing environment is and how complex the target architecture is. A hire joining an organization with well-maintained IaC, documented runbooks, and clean CI/CD pipelines will ramp faster. A hire walking into a legacy environment with minimal documentation and technical debt accumulated across platform migrations will not be carrying load for six months at minimum.

During that window, your hiring manager’s attention is split, onboarding resources are consumed, and any production incidents that surface require the senior team members who were already overloaded to absorb. The productivity gap is real, and it is funded entirely by the organization.

The Bench Problem: Utilization Rates for In-House Cloud Talent Between Major Initiatives

Cloud engineering workloads are not linear. Migration projects, re-architecture initiatives, and security hardening efforts create demand spikes that a small in-house team cannot sustain without contractor augmentation. Between major initiatives, the same engineers sit at significantly lower utilization rates.

Internal studies from operations teams at mid-market SaaS companies consistently show in-house cloud engineers operating at 55 to 70 percent utilization in steady-state periods. You are paying for 100 percent and consuming roughly 60 percent. For organizations that run one or two cloud-heavy initiatives per year, this bench time represents a meaningful cost that rarely appears on the infrastructure budget review.

Key Takeaway: The true cost of an in-house cloud team is 30 to 40 percent higher than base salary accounting alone suggests, and the productivity timeline pushes meaningful delivery out by at least two quarters after the first hire joins.

What a Cloud Engineering Partner Actually Delivers

A cloud engineering partner is not a staff augmentation vendor. The distinction matters. Staff augmentation drops individual contributors into your workflow and leaves coordination, architecture decisions, and quality control to you. A cloud engineering partner operates as an accountable delivery unit with defined services, documented methodologies, and responsibility for outcomes.

Understanding what a well-structured partner actually provides helps you evaluate whether the model fits your requirements, and helps you filter out vendors that are reselling staff augmentation under a more attractive label.

Multi-Cloud Depth vs. Single-Platform In-House Specialization

The core value proposition of a cloud engineering partner is breadth. A single senior hire, no matter how talented, carries deep expertise in one or at most two cloud platforms. Most organizations running enterprise AWS cloud solutions alongside Azure workloads for Microsoft-stack applications cannot staff that coverage requirement with three or four engineers without significant investment.

A cloud engineering partner brings certified depth across AWS, Azure, and GCP as part of the base engagement. When your workloads shift from AWS compute to GCP’s data platform or when a compliance requirement drives a secondary Azure deployment, the partner’s team absorbs that without requiring a new hire cycle. The coverage is immediate. The certification density is maintained through the partner’s internal training programs rather than your training budget.

24/7 Operational Coverage and On-Call Models

In-house cloud teams at most mid-market organizations operate standard business hours with on-call rotation supplemented by third-party incident monitoring. The practical result is that a P1 incident at 2 AM either wakes up a burned-out senior engineer or waits until morning. Neither outcome is acceptable for production systems running revenue-critical workloads.

A cloud engineering partner with a structured DevOps delivery model builds 24/7 coverage into the engagement contract. The on-call model is distributed across a bench of engineers who rotate responsibility, which means no individual is carrying unsustainable on-call burden and incident response does not degrade over time as engineers burn out. For organizations with availability SLAs or regulated uptime requirements, this structural difference in operational coverage is often the deciding factor.

Knowledge Transfer and Documentation Standards That Prevent Dependency

The most common and legitimate concern about cloud engineering partnerships is knowledge lock-in. If the partner leaves or the engagement ends, what does the internal team actually have to operate with?

This concern is valid, but it is a governance problem, not an inherent problem with the partner model. A well-structured engagement includes runbook delivery at defined milestones, IaC repositories that the client owns and can fork independently, architecture decision records that document why each infrastructure choice was made, and handoff sessions that transfer operational context to internal stakeholders. The organizations that experience dependency problems are the ones that did not build knowledge transfer requirements into the contract from day one.

The comparison table below covers how these variables map across both models at the scenario level.

COMPARISON TABLE: IN-HOUSE CLOUD TEAM VS. CLOUD ENGINEERING PARTNER

Decision Variable In-House Cloud Team Cloud Engineering Partner Better Fit
Time to operational effectiveness 6-12 months post-hire Immediate at engagement start Partner for urgent timelines
Multi-cloud platform coverage Typically 1-2 platforms per engineer AWS, Azure, GCP covered as standard Partner for multi-cloud environments
Annual fully loaded cost (team of 3) $700K-$900K+ $300K-$600K depending on scope Partner for cost-sensitive organizations
24/7 operational coverage Requires on-call rotation burden Built into engagement structure Partner for production SLA requirements
Institutional context retention High over time Requires documented transfer In-house for long-horizon products
Regulatory compliance control Full internal control Requires governance framework In-house for highly regulated industries
Bench utilization in steady state 55-70% (cost inefficiency) 100% utilized within engagement Partner for initiative-based workloads
CI/CD and automation depth Depends on individual skill sets Included as standard capability Partner for automation-first programs
Scaling velocity Constrained by hiring pipeline Scales within days of scope change Partner for rapid-growth organizations
Knowledge continuity High if team stays intact Requires contractual transfer clauses In-house for stable, long-term programs

Key Takeaway: Neither model dominates all ten variables. The right choice depends on which three or four variables are most consequential for your specific operating environment and delivery timeline.

The Scenarios Where In-House Wins

The partner model is not universally superior. There are organizational contexts where building internal cloud capability is the right call, and confusing those situations with cost-cutting exercises leads to poor outcomes.

Highly Regulated Industries Requiring Internal Control

Organizations operating under HIPAA with PHI in the infrastructure, financial services firms running PCI-DSS workloads, or defense contractors subject to FedRAMP authorization requirements often face compliance frameworks that specifically constrain how infrastructure is accessed and by whom. In these environments, having engineers who sit on your payroll, operate under your policies, and are accountable to your compliance organization is not a preference. It is a requirement.

External partners can be structured to meet many of these requirements, but the overhead of maintaining contractor compliance documentation, access controls, and audit trails often makes the in-house model simpler to manage under regulatory scrutiny. If your compliance team is telling you that external access to production infrastructure requires a six-month procurement and legal review, the math shifts significantly in favor of internal headcount.

Organizations With Mature Platform Engineering Functions

If your organization already runs a mature platform engineering team with established IaC practices, well-maintained CI/CD pipeline infrastructure, and documented runbooks, the value gap between an in-house cloud hire and a partner narrows considerably. The ramp time is shorter because the environment is better documented. The scope is better defined because the platform team has already made the major architecture decisions.

In these contexts, adding a senior cloud engineer to an existing team with strong infrastructure foundations often delivers more value than a partner engagement that brings overhead in coordination and governance that the mature team does not need.

Long-Horizon Product Infrastructure With Deep Internal Context Requirements

Some infrastructure evolves so closely with a product roadmap that the engineers maintaining it need deep context about product decisions made three years ago to make good infrastructure decisions today. Multi-tenant SaaS products with complex data isolation requirements, custom-built ML inference pipelines that were architected around proprietary data schemas, or platforms that have accumulated years of performance optimization that lives in institutional memory rather than documentation are candidates for this scenario.

When the infrastructure is deeply entangled with product context that is difficult to transfer, an internal team that accumulates that context over years will make better decisions than a partner who is always operating with partial information about why certain choices were made.

Key Takeaway: In-house wins when compliance mandates internal control, when the platform engineering function is already mature, or when the infrastructure is deeply entangled with proprietary product context that is expensive to transfer.

The Scenarios Where a Partner Wins

Companies Scaling Faster Than Their Hiring Pipeline

A Series B company that just closed a round and needs to triple its cloud infrastructure capacity in 90 days cannot execute that through a hiring cycle. The recruiting timeline alone runs 60 to 90 days for senior cloud roles. Onboarding adds another quarter. The delivery risk of running that program through new hires is not manageable.

A cloud engineering partner absorbs the scaling requirement immediately. Engineers are already certified, already familiar with the architecture patterns the engagement requires, and can start contributing in week one. For organizations in rapid-growth phases where infrastructure velocity directly affects product velocity, the partner model is not just more convenient. It is the only operationally viable option.

Multi-Cloud Environments Requiring Breadth No Single Hire Can Provide

If your architecture runs AWS for compute and storage, Azure for Active Directory integration and Microsoft 365 connectivity, and GCP for BigQuery analytics workloads, you are running a multi-cloud environment that no three-person in-house team is likely to cover with depth across all three platforms simultaneously. The platform breadth a competent cloud engineering services partner carries as a base capability would require hiring five to eight specialists to replicate internally, at a cost that most organizations outside the enterprise segment cannot justify.

Cost-Sensitive Organizations That Cannot Carry Bench Time

For organizations running one or two significant cloud initiatives per year rather than a continuous program of infrastructure work, the bench time problem with an in-house team is a material financial issue. Paying three engineers at $220,000 to $280,000 fully loaded costs during the six months between a migration project and the next major initiative is not efficient.

A partner engagement can be scoped to active initiative periods, extended during delivery phases, and contracted at a scope that matches actual demand. The result is a significantly lower annual cost for organizations that do not have continuous high-intensity cloud workloads to justify a standing internal team.

Key Takeaway: The partner model wins decisively for organizations scaling faster than their hiring pipeline, running multi-cloud environments that require breadth across platforms, or operating with initiative-based cloud workloads that do not justify a standing internal team.

The Hybrid Model: How Most Mature Engineering Organizations Actually Run Cloud

The cleanest version of this decision is a binary one: partner or in-house. But the reality of how mature engineering organizations structure cloud operations looks different. The most common and effective model is a deliberate hybrid.

In the hybrid configuration, a small internal cloud function carries the long-term institutional context. These are typically two to four engineers who own architecture decisions, maintain the infrastructure documentation baseline, and serve as the internal interface for compliance and security teams. They hold the product context that is expensive to transfer externally.

The cloud engineering partner fills the breadth and scale requirements. New migration initiatives, multi-cloud coverage requirements, 24/7 operational support, and specialized capabilities like Kubernetes cluster management or security hardening engagements go through the partner rather than requiring the internal team to hire and ramp for capabilities they will use intensively for six months and then not need again.

This model works because it assigns responsibility based on structural fit. The internal team is best suited for long-horizon context retention. The partner is best suited for depth, breadth, and scale on demand. The key governance requirement is defining the boundary between the two clearly at the start of each engagement, so neither function is stepping into work the other is better positioned to own.

Skyram Technologies has built its cloud delivery model around this hybrid reality. US organizations working with a dedicated partner engagement retain full infrastructure ownership through IaC repositories and documented runbooks while drawing on certified AWS, Azure, and GCP depth that would require multiple senior hires to replicate internally.

Key Takeaway: The hybrid model outperforms either pure approach for most mature organizations. Internal engineers hold institutional context. The partner delivers breadth, scale, and 24/7 operational coverage that a small internal function cannot sustain alone.

What to Demand From a Cloud Engineering Partner to Avoid Vendor Lock-In

If you proceed with a cloud engineering partner, the contract and governance structure you establish at the start of the engagement determines whether you build infrastructure capability or infrastructure dependency. These are the non-negotiable requirements that every responsible engagement should include.

Infrastructure ownership in writing. Every IaC artifact, Terraform module, CloudFormation stack, Helm chart, and deployment script produced during the engagement must be owned by your organization and stored in repositories you control. The partner should have no exclusive claim over any infrastructure code. The contract should explicitly state that all work product is client property, including documentation.

Architecture decision records at each milestone. The most dangerous form of lock-in is not code. It is undocumented reasoning. When a decision was made to use a specific database service, a particular networking topology, or a non-standard Kubernetes configuration, that reasoning needs to be captured in a format your internal team can read and act on after the engagement ends. Require ADRs at each project milestone as a contractual deliverable.

Documented runbooks for all production systems. Operational runbooks covering incident response procedures, scaling operations, backup and recovery processes, and platform access controls should be maintained as living documents throughout the engagement and reviewed quarterly. Gaps in runbooks are the clearest signal that knowledge transfer is not happening systematically.

Defined handoff protocols. Before any engagement ends or scopes down significantly, require a structured handoff period where your internal team runs the systems independently with the partner in an advisory role rather than an operational one. This handoff period should be long enough (typically four to eight weeks) for your team to encounter and resolve the types of issues they will face independently. A partner that resists handoff protocols is a partner whose business model depends on your operational dependency.

No single-engineer coverage. The partner’s engagement team should include at minimum two engineers with working knowledge of your environment. Single-engineer coverage creates the same key-person risk you were trying to escape from an in-house model, just with an external contractor instead of an employee.

Key Takeaway: Vendor lock-in from a cloud engineering partner is a governance failure, not an inherent model risk. The organizations that avoid it write the ownership, documentation, and handoff requirements into the contract before signing, not after they notice a problem.

Frequently Asked Questions

  1. What is the main difference between a cloud engineering partner and a managed service provider?

A cloud engineering partner actively builds, architects, and optimizes cloud infrastructure alongside an organization’s internal team, taking accountability for delivery outcomes and engineering decisions. A managed service provider primarily monitors and maintains existing infrastructure according to predefined SLAs without owning architecture or engineering decisions. Cloud engineering partners are engaged for transformation and build work. Managed service providers are engaged for ongoing operational support of stable environments.

  1. How long does it take a cloud engineering partner to become productive on a new engagement?

A cloud engineering partner with structured onboarding processes typically reaches full productivity within two to four weeks of engagement start, compared to six to twelve months for a new in-house hire. The acceleration comes from pre-existing tool familiarity, established methodology, and a team that has executed similar engagements repeatedly. The onboarding investment shifts from individual ramp time to environment documentation and access provisioning, which is significantly faster.

  1. Is it more cost-effective to hire an in-house cloud team or use a cloud engineering partner in 2026?

For organizations with continuous, high-volume cloud workloads and stable long-term infrastructure requirements, a well-staffed in-house team becomes cost-competitive over a three-to-five year horizon. For organizations with initiative-based cloud workloads, multi-cloud coverage requirements, or rapid scaling needs, a cloud engineering partner delivers lower total cost of ownership because the engagement scales with demand rather than carrying bench time between projects. The breakeven point depends on utilization rates, scope continuity, and required platform breadth.

  1. How do you prevent knowledge lock-in when working with a cloud engineering partner?

Knowledge lock-in prevention requires contractual structure, not trust. Organizations should require client ownership of all IaC repositories and deployment artifacts, architecture decision records at each project milestone, operational runbooks maintained as living documents throughout the engagement, and a formal handoff period before any scope reduction. The contract should also prohibit the partner from using proprietary tooling that cannot be independently operated by the client team after the engagement ends.

  1. What cloud certifications should a cloud engineering partner’s team hold?

A credible cloud engineering partner should maintain current certifications across the platforms they claim to support. For AWS, look for AWS Solutions Architect Professional and AWS DevOps Engineer Professional credentials. For Azure, Microsoft Certified Azure Solutions Architect Expert and Azure DevOps Engineer Expert are the relevant benchmarks. For GCP, the Professional Cloud Architect and Professional DevOps Engineer certifications indicate genuine platform depth. Certification counts alone are insufficient. Ask for specific engineers’ credentials and verify that the engineers on your engagement, not just the partner’s broader team, hold the relevant certifications.

  1. When should a company consider the hybrid model instead of choosing one approach exclusively?

The hybrid model is appropriate when an organization has both long-horizon infrastructure requirements that benefit from internal institutional context and short-to-medium-term initiative needs that require depth or scale the internal team cannot provide alone. A common trigger is when an internal team of two to four engineers manages a stable core infrastructure but faces a major migration, multi-cloud expansion, or compliance-driven re-architecture that would require them to either hire six months in advance or delay the initiative by a full planning cycle. The hybrid model handles the initiative-based demand through the partner while the internal team retains ownership of the long-term infrastructure baseline.

Talk to Skyram About Cloud Engineering Partnership Models

The decision between a cloud engineering partner and an in-house cloud team is not a one-time strategic call. It is a decision you revisit as your infrastructure complexity, growth rate, and compliance requirements evolve. Getting it wrong in either direction costs more than the initial budget impact suggests.

Skyram Technologies works with US organizations across SaaS, e-commerce, manufacturing, and enterprise technology to design cloud delivery models that match actual operational requirements. Whether the right answer is a full partner engagement, hybrid model support, or advisory services alongside an existing internal team, the conversation starts with understanding your current environment and delivery constraints.

Book a consultation with Skyram’s cloud engineering team to discuss what partnership model makes sense for your organization in 2026.

How to Hire a GCP Engineer for a Data-Heavy SaaS Product

CTO reviewing GCP engineer evaluation criteria for a data heavy SaaS product architecture

The candidate pool for cloud engineers is large. The candidate pool for GCP engineers who can architect a Pub/Sub-to-Dataflow streaming pipeline, tune BigQuery partition pruning, manage slot reservation costs at query scale, and wire a Vertex AI endpoint into a production SaaS application is substantially smaller than most CTOs expect when they open a requisition.

AWS commands roughly 31% of the global cloud market. Azure sits near 25%. GCP holds around 12%. That market share gap is not just a commercial metric. It directly shapes where engineering talent concentrates. Most engineers who entered cloud over the past decade learned AWS first, Azure second, and GCP only when a specific project demanded it. The result is a hiring environment where “cloud engineer” and “GCP engineer with BigQuery and data pipeline depth” describe very different candidate populations, and conflating the two leads to expensive, misaligned hires.

Hiring a GCP engineer for a data-heavy SaaS product requires verifying hands-on experience with BigQuery, Cloud Dataflow, Pub/Sub, and Vertex AI, not just general Google Cloud certification. SaaS products that process large data volumes at scale need GCP engineers who understand streaming pipeline architecture, cost management at query scale, and how to integrate Google’s AI and ML services into production application layers.

This guide is written for CTOs and Data Engineering Leads at SaaS companies processing significant data volumes who need a tighter hiring framework before the offer conversation begins.

Why GCP Engineer Hiring Is Different From AWS or Azure

The Data-Native Architecture Difference: BigQuery, Dataflow, Pub/Sub

Google did not build GCP as an infrastructure platform with data services added on later. Data infrastructure is native to the platform’s design. BigQuery is a fully managed, serverless data warehouse capable of querying petabytes in seconds without infrastructure provisioning. Cloud Dataflow handles stream and batch data processing using the Apache Beam model. Pub/Sub provides real-time messaging at scale. Vertex AI brings model training and deployment into the same environment where the data lives, with Feature Store connecting data pipelines directly to the model layer.

This native integration is the architectural advantage that makes GCP compelling for data-heavy SaaS products. It also means that a GCP engineer without direct hands-on experience with these specific services is not the right hire for a data-intensive application. General familiarity with Compute Engine and Cloud Run does not translate to the data pipeline competency your SaaS product requires.

An engineer who built GKE clusters and managed Cloud Run deployments but has never touched a Dataflow pipeline or tuned a BigQuery partitioned table is a GCP generalist. That profile fills many infrastructure roles well. It does not fill the role your SaaS data layer needs.

Where GCP Skills Are Clustered vs. Where AWS and Azure Dominate

GCP skills concentrate in specific engineering environments: companies that built their data infrastructure natively on Google Cloud, teams running machine learning workloads that benefit from Vertex AI and TensorFlow integration, and organizations that migrated from on-premises Hadoop environments and landed on Dataproc. Outside those environments, GCP depth is rare.

AWS and Azure talent distributes far more widely because both platforms have longer enterprise sales histories, larger partner ecosystems, and broader job market demand over the past fifteen years. A CTO searching for a GCP engineer with BigQuery and Dataflow depth is operating in a smaller absolute talent pool than one searching for a comparable AWS or Azure specialist. That constraint means the evaluation process needs to be tighter and the sourcing strategy needs to go beyond standard job boards.

Why GCP Certification Alone Is a Weak Hiring Signal for Data Workloads

Google’s Professional Data Engineer certification covers BigQuery, Dataflow, Pub/Sub, and related services at a conceptual level. It tests knowledge of when to use which service and how those services interconnect in reference architectures. It does not test the ability to design a real-time event pipeline for ten million daily events, manage BigQuery costs under on-demand versus slot reservation models, or structure IAM for a multi-tenant SaaS environment with strict tenant isolation requirements.

Certification confirms a candidate studied for and passed an exam. It does not confirm they have operated these systems under production pressure. Many engineers hold the Professional Data Engineer certification after a few months of preparation without having run a single Dataflow job in a live environment. For a data-heavy SaaS product, certification is a useful baseline signal. It cannot substitute for the technical screen described later in this guide.

Key Takeaway: GCP hiring is structurally harder than AWS or Azure hiring because the talent pool is smaller and more concentrated. Certification is a floor, not a filter. The evaluation needs to go deeper.

The GCP Skill Set That Actually Matters for SaaS Data Workloads

Streaming vs. Batch Pipeline Architecture

A data-heavy SaaS product typically needs both streaming and batch pipeline capabilities, and the skill requirements differ meaningfully between them. Streaming pipelines process events in real time through Pub/Sub into Dataflow, enabling live dashboards, fraud detection triggers, and behavioral analytics. Batch pipelines process historical data through scheduled Dataflow jobs or BigQuery scheduled queries, enabling reporting, model retraining, and large-scale aggregations.

The right GCP engineer for a SaaS data product understands when to use each model, how to build pipelines that can operate in both modes as requirements change, and how to manage the operational complexity of running both reliably in production. Candidates who have only operated batch workloads will struggle when your product needs to process a user behavior event within 200 milliseconds. Candidates who have only built streaming pipelines may not understand how to structure cost-efficient batch aggregations at scale. Screen for both directions explicitly.

Vertex AI and ML Integration Requirements

If your SaaS product includes any predictive features, recommendation systems, anomaly detection, or natural language processing components, the GCP engineer you hire needs to understand Vertex AI’s model training and deployment workflow beyond the conceptual level.

Strong candidates can describe how they have moved a model from development into a Vertex AI endpoint, how they handle model versioning and rollback, and how they monitor model performance drift in production. They should also understand how Vertex AI integrates with BigQuery ML for in-database model training and how Feature Store manages feature pipelines shared across multiple models in production.

This integration layer is where many GCP engineers with infrastructure backgrounds stop short. If your product roadmap involves machine learning in production, build Vertex AI proficiency directly into your technical evaluation framework rather than treating it as a nice-to-have.

Cost Management at BigQuery Query Scale

BigQuery pricing operates on two models. On-demand pricing charges per terabyte queried. Slot reservations commit to a fixed compute capacity at a predictable cost regardless of query volume. At low query volumes, on-demand is economical. As query volume grows, especially with poorly written queries that scan entire tables instead of using partition pruning or clustering, costs escalate quickly.

A GCP engineer experienced with data-heavy SaaS products understands how to design table schemas that minimize bytes scanned, how to implement partition expiration policies that control storage costs, and when to recommend moving from on-demand to slot reservations based on actual usage patterns. They should be able to read the BigQuery information schema to surface the costliest queries and optimize them before the invoice reflects the problem.

Cost discipline at BigQuery scale is a technical skill with a direct business impact. Screen for it directly rather than assuming it comes with general GCP familiarity.

Comparison Table: GCP Generalist Profile vs. Data-Focused GCP Engineer Profile

Dimension GCP Generalist Data-Focused GCP Engineer
Primary experience Compute Engine, GKE, Cloud Run BigQuery, Dataflow, Pub/Sub, Vertex AI
Pipeline experience Basic Cloud Build / CI automation Streaming and batch pipeline design and operation
BigQuery depth Familiar with running queries Schema design, partition tuning, cost optimization
ML/AI integration Aware Vertex AI exists Has deployed and monitored Vertex AI endpoints in production
Cost management General cloud billing awareness BigQuery slot vs. on-demand modeling and optimization
IAM approach Standard project-level roles Multi-tenant, service account design for SaaS isolation
SaaS data fit Infrastructure and DevOps roles Direct fit for data layer ownership in SaaS products

Key Takeaway: A GCP generalist can manage compute infrastructure reliably. A data-focused GCP engineer can own your data pipeline architecture, query cost envelope, and ML production integration. These are different roles with different evaluation criteria.

The Technical Evaluation Framework for GCP Data Engineers

Architecture Scenario: Design a Real-Time Event Pipeline for 10M Daily Events

The most reliable signal in a GCP data engineering screen is not credential review. It is watching a candidate reason through an architecture problem under realistic constraints.

Present this scenario: your SaaS product ingests ten million behavioral events per day from web and mobile clients. Events need to be processed in near real time for a live analytics dashboard and stored in a format optimized for historical reporting. Walk through the architecture you would design on GCP, including how you would handle late-arriving events, schema evolution, and pipeline monitoring.

Strong candidates move through Pub/Sub as the ingestion layer, Dataflow with windowing logic to handle late arrivals, BigQuery as the storage and query layer with partitioned and clustered tables, and Cloud Monitoring with custom metrics for pipeline health. They ask about expected event payload size, acceptable latency for dashboard updates, and whether schema changes require backward compatibility with existing stored data.

Weak candidates describe the components at a high level without explaining the design decisions behind each choice. They do not ask clarifying questions about latency or schema requirements, and they do not address what happens when the pipeline falls behind under burst load.

This scenario surfaces experience depth more accurately than any resume line item. Run it before the offer conversation, not after. Teams that need this kind of pipeline architecture built and operated within a broader GCP engineering engagement will recognize how quickly this evaluation separates production-ready engineers from theoretical ones.

Cost Optimization: How They Approach BigQuery Slot Reservation vs. On-Demand

Follow the pipeline scenario with a direct cost question: how would you decide whether to use BigQuery on-demand pricing or slot reservations for this workload?

The correct answer involves analyzing actual query patterns before making a recommendation. A candidate who immediately defaults to reservations without modeling current query volume, scan rates, and cost trajectory is guessing. A candidate who walks through how to use the BigQuery information schema to surface query costs, how to project the break-even point between on-demand and reservation pricing at different usage levels, and how to configure slot auto-scaling for variable workloads is demonstrating genuine operational depth.

This question also reveals whether a candidate treats infrastructure cost as a product concern or as someone else’s problem. In a data-heavy SaaS context, BigQuery costs can become a significant line item within months. An engineer who treats cost management as outside their scope is not the right fit for a product at scale.

Security and IAM Design for Multi-Tenant SaaS

Multi-tenant SaaS applications require strict data isolation between customers. In GCP, this isolation happens through IAM design, VPC Service Controls, and how BigQuery datasets are organized and permissioned across tenants.

Ask candidates to describe how they would structure GCP IAM for a SaaS application where each customer’s data must be isolated and customer-specific service accounts must not have access to other tenants’ datasets. Strong candidates describe a project-per-tenant model or a dataset-per-tenant model within a shared project, explain how service account impersonation works at the query level, and reference VPC Service Controls as an additional boundary for sensitive or regulated workloads. They also understand how authorized views in BigQuery allow row-level data sharing without exposing underlying tables to tenant-level service accounts.

Candidates who cannot articulate the difference between project-level roles and dataset-level permissions in BigQuery, or who have never worked with VPC Service Controls, will create security gaps in a multi-tenant environment that are expensive and disruptive to remediate after the architecture is in production. For teams running containerized workloads alongside their data layer, the Kubernetes solutions page covers how GKE and data pipeline architecture interact in production SaaS environments.

Key Takeaway: Three questions cut through resume noise faster than any screening filter: the pipeline architecture scenario, the BigQuery cost model question, and the multi-tenant IAM design. Use all three before any offer conversation begins.

Where to Find GCP Engineers With Data Pipeline Depth

Why Job Boards Surface Generalists, Not Specialists

Standard job boards optimize for volume. A GCP engineer posting on LinkedIn or Indeed generates applications from every candidate who has used Google Cloud in any capacity, including engineers who completed a single GKE lab during a certification prep course. The filtering burden falls entirely on the hiring team, and without a tight technical screen in place, it is straightforward to advance candidates who look strong on paper but lack the BigQuery and Dataflow depth the role requires.

If you post a generic cloud engineer role noting GCP as preferred, you receive AWS engineers willing to learn GCP. If you post a GCP data engineer role with specific service requirements listed, you narrow the pool considerably but still need to verify depth through direct technical evaluation.

Referral networks inside GCP-native engineering communities produce better-qualified candidate pipelines than open job board postings. Engaging in Google Cloud community groups, data engineering Slack communities, and GCP-focused conference tracks surfaces engineers who self-identify as GCP practitioners rather than generalists who happen to be available. Internal DevOps teams that have run GCP engagements can also surface referrals that never appear on job boards.

Offshore GCP Engineering Partners vs. Freelance Marketplaces

For SaaS companies that need sustained GCP data engineering capacity without the timeline or overhead of a direct hire, two external options come up frequently: offshore engineering partners and freelance marketplaces. These options are not equivalent and the distinction matters for a data-heavy product.

Freelance marketplaces surface individual contractors with variable depth, limited accountability for long-term outcomes, and no team continuity when a project scope extends or a pipeline requires ongoing optimization. For a discrete, well-scoped task, a strong freelancer can deliver. For ongoing data pipeline architecture, cost optimization, and ML integration across a growing SaaS product, contractor continuity risk is real.

Offshore engineering partners with GCP specialization offer team continuity, defined SLAs, and accountability for outcomes across an engagement rather than a task. The evaluation criteria are similar to the direct hire evaluation: verify BigQuery and Dataflow depth specifically, not general cloud capability. Partners who position themselves as multi-cloud generalists frequently lack the GCP data pipeline depth a data-heavy product requires. Evaluate the team’s specific GCP experience the same way you would evaluate a direct hire candidate, using the technical scenarios above rather than taking a portfolio at face value.

Key Takeaway: Job boards surface volume. GCP data pipeline specialists come through community networks, referrals, and vetted engineering partners. The sourcing strategy determines the quality of the candidate pool before the evaluation process begins.

Onboarding a GCP Engineer Into an Existing SaaS Architecture

A strong GCP hire needs structured onboarding into your existing data architecture before they can make sound technical decisions. Without it, even a technically capable engineer optimizes for the wrong constraints in the first sixty days.

The onboarding sequence for a GCP data engineer joining a data-heavy SaaS product should cover four areas in order. First, the current data model: how data flows from ingestion through transformation and into the query layer, including any technical debt or known schema inconsistencies the team has been living with. Second, the cost environment: current BigQuery usage patterns, monthly cost trends, and any known query performance issues that are already affecting the bill. Third, the multi-tenant isolation model: exactly how tenant data is separated today and where that isolation breaks down or creates operational friction. Fourth, the CI/CD pipeline that governs data infrastructure changes: how Dataflow jobs are deployed, how BigQuery schema changes are managed, and how pipeline failures are detected and escalated.

An engineer who goes into production without this context makes decisions based on what they built at their previous company, not what your product actually needs. The cost of that misalignment compounds over the first quarter and is hard to reverse once architectural patterns are established.

For teams that also run complex CI/CD automation alongside their data pipelines, the CD pipeline services page covers how deployment automation integrates with cloud data infrastructure in production SaaS environments.

Key Takeaway: Structured onboarding into the data model, cost environment, multi-tenant isolation design, and deployment pipeline is not optional. The first sixty days set the architectural patterns the engineer will follow for the duration of their tenure.

When a Managed GCP Partner Outperforms a Single Hire

A single GCP engineer hire makes sense when your data pipeline architecture is well-defined, your query volume is predictable, your ML integration requirements are stable, and your internal team has the bandwidth to support the hire operationally and technically.

When any of those conditions are not true, a managed GCP partner frequently delivers better outcomes than a single hire for several structural reasons.

A single engineer carries concentration risk. If that engineer leaves, the BigQuery schema design knowledge, the Dataflow pipeline logic, the slot reservation configuration, and the Vertex AI integration context all leave with them. For a data-heavy SaaS product, that concentration risk is not hypothetical. The GCP data engineering talent market is competitive, and retention at the individual contributor level is a real operational variable.

A managed GCP partner brings team continuity. Knowledge is distributed across the engagement team rather than concentrated in a single person. When a team member rotates, the architectural context stays with the team. This matters more for data pipeline work than for most engineering domains because the pipeline design decisions compound over time and are difficult to reconstruct from code alone without the reasoning behind them.

A managed partner also provides breadth that a single hire cannot. A data-heavy SaaS product’s GCP footprint typically spans data engineering, infrastructure management, security and IAM design, and increasingly ML production operations. A single engineer with depth in BigQuery and Dataflow may lack the breadth to own infrastructure security posture, manage GKE clusters running adjacent services, and optimize Vertex AI deployment costs simultaneously. A partner team covers that breadth without requiring the product to hire four specialists sequentially.

For teams evaluating this model, the cloud engineering services page outlines how a managed GCP engagement structure differs from a staff augmentation model, including how architecture ownership is maintained across the engagement. Teams also considering multi-cloud architecture alongside their GCP data layer will find relevant context on the AWS Cloud Services page covering how cross-cloud engineering is managed within a single delivery team.

Key Takeaway: A managed GCP partner outperforms a single hire when pipeline architecture is evolving, when ML integration requirements are growing, or when concentration risk at the individual engineer level is a business concern. Evaluate the model against your actual operational conditions, not the abstract preference for headcount.

Frequently Asked Questions

1: What skills should a GCP engineer have for a data-heavy SaaS product?

A GCP engineer hired for a data-heavy SaaS product should demonstrate hands-on production experience with BigQuery, Cloud Dataflow, Pub/Sub, and Vertex AI. General Google Cloud infrastructure skills, including Compute Engine and GKE, are foundational but insufficient on their own. The most critical competencies are streaming and batch pipeline architecture using Dataflow and the Apache Beam model, BigQuery schema design with partition pruning and clustering for cost-efficient querying, multi-tenant IAM design with dataset-level isolation, and Vertex AI endpoint deployment and monitoring for production ML workloads. Cost management at BigQuery query scale, specifically the ability to model on-demand versus slot reservation trade-offs, is a practical skill that distinguishes experienced data pipeline engineers from those who have only worked with smaller data volumes.

2: Is Google Cloud certification enough to hire a GCP data engineer?

Google Cloud certification, including the Professional Data Engineer credential, is not sufficient on its own to evaluate a GCP engineer for a data-heavy SaaS product. The certification tests conceptual knowledge of when to use GCP services and how they interconnect in reference architectures. It does not test the ability to design a production streaming pipeline for millions of daily events, optimize BigQuery query costs at scale, or structure IAM for strict multi-tenant data isolation. Certification confirms study and exam preparation. Hands-on production experience with BigQuery, Dataflow, Pub/Sub, and Vertex AI under real operational conditions is the signal that matters for a data-heavy application. Technical evaluation through architecture scenario questions is the most reliable way to verify that depth.

3: What is the difference between Cloud Dataflow and BigQuery for SaaS data pipelines?

Cloud Dataflow and BigQuery serve different functions in a GCP data pipeline architecture. Dataflow is a managed stream and batch data processing service built on the Apache Beam model. It handles the transformation, filtering, aggregation, and routing of data as it moves from ingestion through to storage. BigQuery is a serverless data warehouse designed for running analytical SQL queries across large datasets. In a typical data-heavy SaaS pipeline, Pub/Sub ingests events in real time, Dataflow processes and transforms those events, and BigQuery stores the processed data for querying and reporting. The two services are complementary rather than interchangeable, and a GCP engineer for a data-heavy product needs production depth in both.

4: How much does it cost to run BigQuery at scale and how do engineers manage it?

BigQuery costs at scale depend on the pricing model selected and the quality of the query and schema design. On-demand pricing charges approximately five dollars per terabyte queried. Slot reservations provide a fixed compute capacity commitment at a predictable monthly cost, which becomes more economical as query volume grows. Engineers manage BigQuery costs by designing table schemas with partition pruning and clustering to minimize bytes scanned per query, using the BigQuery information schema to identify and optimize the costliest queries, implementing partition expiration policies to control storage costs, and modeling the break-even point between on-demand and slot reservation pricing based on actual usage patterns. Poor query design on a large dataset can generate substantial unexpected costs within a single billing cycle, which is why cost management is treated as a core technical skill for GCP data engineering roles in data-heavy SaaS environments.

5: When should a SaaS company use a managed GCP partner instead of hiring a GCP engineer directly?

A managed GCP partner is a better fit than a direct hire when the data pipeline architecture is actively evolving and requires ongoing architectural decisions rather than steady-state operation, when ML integration requirements are growing and require breadth across BigQuery, Dataflow, and Vertex AI simultaneously, when the GCP data engineering workload requires more capacity than a single engineer can absorb, or when concentration risk at the individual contributor level is a business concern. A direct hire is appropriate when the pipeline architecture is stable and well-documented, when the internal engineering team has sufficient context to support and manage the hire operationally, and when the scope of GCP work is narrow enough for a single engineer to own end to end. The concentration risk factor is frequently underweighted in the direct hire decision. GCP data engineering talent is competitive to retain, and losing a single engineer who owns undocumented pipeline architecture creates recovery costs that a managed team model avoids structurally.

Ready to Build a GCP Data Architecture Your Product Can Grow Into?

The wrong GCP hire costs more than the salary. It costs the months spent discovering the mismatch, the pipeline technical debt that accumulates without the right expertise in place, and the BigQuery costs that compound before anyone notices the query patterns are wrong.

Skyram’s GCP engineering engagements start with a data architecture assessment specific to your SaaS product’s actual workload before any pipeline design decisions are made, and every engagement is structured around long-term ownership rather than short-term delivery.

Talk to Skyram about GCP engineering for your SaaS product

How to Hire a Web Application Development Company for a SaaS MVP

How to Hire a Web Application Development Company for a SaaS

Hiring a web application development company for a SaaS MVP requires evaluating their product scoping process, technology stack decisions relative to your growth trajectory, and their ability to build for iteration speed without accumulating technical debt that blocks Series A engineering. Most development shops can build an MVP. Far fewer build one that a post-funding engineering team can take over without a full rewrite.

Here is a scenario that repeats itself constantly in early-stage SaaS. A founder hires a development shop, ships an MVP in 12 weeks, closes seed funding, and then spends the next six months listening to their new CTO explain why the codebase needs to be rebuilt before any new features can go in. The product is stalled. The runway is burning. The engineering team the investors just funded is doing archaeology instead of shipping.

This is not a horror story. It is a standard outcome when founders evaluate development partners on delivery speed and price rather than on architecture quality, handoff readiness, and the SaaS-specific decisions that determine whether a codebase has a future.

This guide covers what to look for, what to ask, and what to lock into the contract before you sign with any web application development company for an MVP engagement.

What SaaS MVP Development Actually Requires (vs. What Agencies Promise)

Every development shop says they build MVPs. What they usually mean is they build software in a compressed timeline. That is not the same thing as building a SaaS product designed for iteration, investor scrutiny, and team handoff.

Scope Discipline: What Belongs in an MVP and What Kills One

A SaaS MVP has one job: validate your riskiest product assumption with the minimum surface area that makes that validation meaningful. That means the development partner you hire needs to push back on your feature list, not just execute it.

The shops that build the most trouble-prone MVPs are the ones that say yes to everything in the brief. If your potential partner has never told a founder “that feature belongs in v2,” that is a warning sign. A development company with real SaaS MVP experience knows that scope creep at the MVP stage does not just delay delivery. It creates the kind of over-engineered, premature product complexity that buries a codebase before the first real user test.

Ask any agency you are evaluating to walk you through a previous MVP scope conversation. How did they handle a client who wanted to build too much? What did they cut and why? If they cannot give you a specific answer, they have probably never actually scoped a SaaS MVP with a founder in the room.

Stack Decisions That Serve Iteration Speed Without Creating Future Migration Debt

The framework and database choices made at the MVP stage follow a product for years. They determine what kinds of engineers you can hire, how fast you can iterate, and how painful your first scaling event will be.

The right web application development partner for a SaaS MVP picks a stack based on your growth trajectory, not their team’s comfort zone. The most common mistake is agencies choosing frameworks because that is what their developers know, which leaves the founder with a codebase built on niche or legacy technology that is hard to hire for once funding lands.

React on the frontend paired with Node.js or a modern Python framework on the backend gives you the widest hiring pool for your next engineering team. PostgreSQL or a comparable relational database gives you the query complexity you will eventually need without forcing a migration later. These are not the only right answers, but they are the kinds of decisions your development partner should be making deliberately, with an explanation tied to your product and funding roadmap.

Documentation and Handoff Standards That Matter When You Hire a CTO Post-Funding

The codebase your development company delivers is not just a product. It is an asset a future engineering team will inherit. If the backend web development is undocumented, if the architecture decisions are tribal knowledge inside the agency’s team, and if the deployment process exists only in a developer’s head, the handoff will fail.

Good development partners build documentation as a deliverable, not as an afterthought. Before you sign a contract, ask for a sample README, a sample architecture decision record (ADR), and a description of their CI/CD setup on a previous project. What you receive tells you everything about their handoff standards.

Key Takeaway: The agency that builds your MVP is also building the foundation your first hire will work on. Scope discipline, deliberate stack choices, and documentation standards are not nice-to-haves for a SaaS MVP. They are the deliverables that determine whether your codebase has a future after you close seed.

How to Evaluate a Development Company’s SaaS MVP Track Record

Portfolio pages show finished products. They do not show you what happened to those products six months after launch. That is the question that actually matters.

Portfolio Questions: What Happened to the Products They Built After Launch?

Ask every development company you evaluate two direct questions: Which of your past SaaS MVPs went on to raise funding or reach meaningful traction? And did those founding teams keep your codebase or rebuild it?

Most agencies will not have an immediate answer to the second question. That is telling. A development partner that builds SaaS products with future-readiness as an explicit goal tracks this. They know which of their clients’ codebases are still running. They know which ones got rewritten. And they can tell you why.

If a shop has built 20 MVPs and cannot name a single one that survived a post-funding engineering review intact, that is a pattern worth taking seriously.

Technical Architecture Review: How Do They Make Stack Decisions for Early-Stage Products?

Before you go too far in the evaluation process, request a brief technical architecture discussion with a senior engineer from the agency, not the salesperson. Ask them how they would approach your specific product: what they would pick for the frontend, what they would use for the backend, what kind of database structure they would start with and why.

A development partner with genuine SaaS MVP experience will give you a grounded, product-specific answer. They will ask you questions about your expected user volume at launch, whether you anticipate multi-tenancy, and whether your roadmap has features that require real-time functionality. A shop with commodity MVP experience will recite their default stack without asking any of those questions.

The right answer to a technology question in an MVP context always starts with “it depends on your use case.” If you hear a confident stack recommendation before they have asked a single question about your product, move on.

Their Scoping Process: Do They Push Back on Feature Requests or Just Take the Brief?

One of the clearest signals of an agency’s SaaS readiness is their scoping behavior. Early in an engagement, request a scoping call and come in with a feature list that is 30 percent too long. See what they do with it.

Agencies that are optimizing for billings will take the brief, estimate everything, and send a proposal. Agencies that understand SaaS product development will push back. They will ask what you are trying to learn with the MVP, which features directly test that hypothesis, and what belongs in a phase two backlog.

The ability to say “you do not need that yet” is a signal that a development company is thinking like a product partner, not a build shop.

Comparison Table: MVP-Capable Development Shop vs. SaaS-Fit Development Partner

Evaluation Criteria MVP-Capable Development Shop SaaS-Fit Development Partner
Scoping approach Executes brief as received Questions scope, cuts non-essential features
Stack decisions Based on agency’s default preferences Based on founder’s hiring roadmap and growth stage
Documentation Minimal or post-launch Built as a deliverable throughout the project
Post-launch codebase outcome Frequently requires significant rework Survives post-funding engineering review
Handoff process Informal knowledge transfer Structured handoff with README, ADRs, and runbooks
Architecture awareness Adequate for initial delivery Designed for the engineering team that comes next
Communication about risk Reactive Proactive, flags technical debt before it accumulates

Key Takeaway: The evaluation questions that matter most are not about portfolios or pricing. They are about what happens to codebases six months after launch and whether the development company’s process is designed to protect you from rebuilding from scratch after you raise.

The Contract Provisions That Protect a Founder in an MVP Engagement

A well-scoped MVP with the wrong contract structure can still expose a founder to serious downstream risk. These are the provisions that need to be explicit before any work begins.

IP Ownership: What You Must Own From Day One

Your contract needs to state unambiguously that all intellectual property created during the engagement transfers to you upon payment. This includes code, documentation, design files, database schemas, API specifications, and any other artifacts produced during the project.

Some development shops retain ownership of reusable component libraries or internal frameworks they bring to the project. This is a negotiable point, but it needs to be in writing. The last thing you want is a dispute with a former development partner over who owns the authentication module after you close a Series A.

Code Quality Standards and Test Coverage Requirements

Your contract should include a minimum test coverage threshold. For a SaaS MVP, a reasonable floor is 60 to 70 percent unit and integration test coverage on critical paths. Authentication, payment processing, and data integrity logic should be tested. A codebase handed off without tests is a maintenance liability your next engineer will have to absorb before they can ship anything safely.

Also specify code review requirements. At minimum, all production code should go through a peer review process within the agency before delivery. If this is not standard practice for the shop you are evaluating, that tells you something important about their quality culture.

Knowledge Transfer and Documentation Deliverables

Make documentation a contractual deliverable, not an informal expectation. The handoff package should include a system architecture overview, a README that allows a new developer to set up the local environment in under 30 minutes, API documentation for all endpoints, and a deployment runbook. If your cloud engineering setup has any complexity, that needs its own documented runbook as well.

These documents should be delivered before final payment, not after. Tying the last payment milestone to documentation delivery is a reliable way to ensure it actually happens.

Key Takeaway: The contract provisions that protect a founder are not boilerplate. They are specific clauses around IP ownership, test coverage minimums, and documentation deliverables that need to be drafted explicitly and tied to payment milestones.

Technology Stack Decisions That Affect Your Post-MVP Engineering Choices

The technology choices made during an MVP build are not temporary. They compound. The framework your development company picks today is the framework your next engineering hire needs to know on day one.

Why Framework Popularity Matters for Hiring Your Next Engineering Team

When you close funding and start hiring engineers, the technology your codebase is built on determines your available talent pool. A React and Node.js codebase gives you access to the largest pool of available JavaScript engineers in the US market. An obscure PHP framework or a niche backend language shrinks that pool dramatically and adds time to your hiring process at precisely the moment you need to move fast.

This is not an argument for always choosing the most popular technology. It is an argument for choosing technology intentionally, with a clear understanding of how your hiring roadmap interacts with your technical roadmap. Any web application development partner worth working with will raise this conversation on their own.

Database Decisions at MVP Stage That Compound at Scale

The database structure you start with affects every data model decision you make for the next two years. Starting with a relational database like PostgreSQL gives you the flexibility to add complex query patterns as your product matures without a migration event. Starting with a NoSQL database because it is faster to prototype with may create significant rework when you need reporting, referential integrity, or multi-tenant data isolation at scale.

Your development partner should be able to articulate exactly why they are recommending a particular database for your specific product, including what happens to that recommendation at 10,000 users, at 100,000 users, and when you introduce multi-tenancy for an enterprise tier.

Cloud Infrastructure Choices That Determine Your DevOps Complexity Post-Funding

The infrastructure decisions made during MVP development determine how much DevOps complexity your post-funding team inherits. An MVP built on a well-structured AWS or comparable cloud setup, with infrastructure-as-code and a basic CI/CD pipeline, gives a new engineering team a foundation they can work with immediately.

An MVP deployed as a collection of manually configured servers with no documented runbook is a different story. Before you hire a development company, understand their standard deployment approach. Ask them to show you the infrastructure they would set up for a product like yours and what it would take for a new DevOps engineer to understand that setup on day one.

The frontend design and development layer of your product also has infrastructure implications. Server-side rendering frameworks like Next.js have specific hosting requirements and caching behaviors that differ from a purely client-rendered application. These decisions need to be made deliberately, with an understanding of how they interact with your overall deployment architecture.

Key Takeaway: Stack decisions are hiring decisions. The right development partner frames every technology recommendation in terms of your growth stage, your hiring roadmap, and what happens when the next team inherits the codebase.

Offshore MVP Development Partners: Evaluating Quality, Communication, and Timeline Reliability

Many US-based founders work with offshore development partners for SaaS MVPs, and for good reason: the cost structure can extend runway significantly. The evaluation criteria for offshore partnerships are somewhat different than for domestic shops, and getting them right matters.

The most reliable proxy for offshore quality is not portfolio design. It is GitHub commit history. If a development company will share a sanitized or demo repository, look at commit quality: message clarity, frequency, branching strategy, and code review activity. A shop with disciplined commit practices is a shop with disciplined engineering culture.

Communication reliability is the second critical variable. For a US founder working with an overseas team, the question is not whether the time zone works. It is whether the agency has a documented communication protocol: daily async updates, weekly video check-ins, and a clear escalation path when blockers arise. Agencies that operate without these structures tend to surface problems late, which is exactly the wrong behavior in a compressed MVP timeline.

Timeline reliability is best evaluated by asking for references, not from the project that went well, but from a project that hit a significant technical challenge. How did the team communicate the issue? How quickly did they propose a solution? What was the final impact on the timeline? The answer to that question tells you far more than a reference from a smooth delivery.

For SaaS MVPs specifically, also evaluate whether the offshore team has experience building multi-tenant architectures, SaaS authentication flows (OAuth, SSO), and subscription billing integrations. These are not generic web development patterns. A team that has built them before will move faster and make fewer architectural mistakes than one learning them on your project.

Key Takeaway: For offshore MVP development, evaluate commit history quality, structured communication protocols, and references from projects that faced technical challenges, not just the ones that ran smoothly.

What the Handoff to an Internal Engineering Team Should Look Like

The handoff is where most MVP engagements fail. Not because the product was built poorly, but because the transition from agency to internal team was never planned as a formal deliverable.

A well-executed handoff has a specific structure. It starts before the final sprint, not after. The development company should schedule a minimum of two formal knowledge transfer sessions with whoever will inherit the codebase: a technical walkthrough of the architecture and a operational walkthrough of the deployment and monitoring setup.

Every environment should be documented. Local development setup, staging configuration, and production infrastructure should all have written runbooks that allow a new engineer to reach a functional environment without asking the agency for help. If the agency is using any credentials, API keys, or third-party service accounts under their own ownership, those need to be formally transferred and rotated before the engagement closes.

The final deliverable from any MVP engagement should include a technical debt inventory. Not every corner cut during an MVP is a problem, but every corner cut should be documented so your incoming engineering team knows what they are inheriting and can prioritize remediation against new feature work.

Skyram Technologies builds handoff documentation as a formal project phase, not an afterthought. Our SaaS product builds include architecture decision records, deployment runbooks, and structured knowledge transfer sessions designed specifically for the engineering team that comes next. If you are evaluating development partners for a SaaS MVP, this is the standard to hold them to.

Key Takeaway: A well-executed MVP handoff starts before the final sprint, includes formal knowledge transfer sessions, transfers all credentials and third-party accounts, and delivers a documented technical debt inventory alongside the codebase.

Frequently Asked Questions

1: What should I look for when hiring a web application development company for a SaaS MVP?

When hiring a web application development company for a SaaS MVP, founders should evaluate the agency’s scoping process, not just their portfolio. The most important signals are whether the agency pushes back on feature requests, how they make technology stack decisions, whether they have built SaaS-specific patterns like multi-tenancy and subscription billing before, and what their handoff process looks like. A development company that delivers a well-documented codebase with test coverage and a structured knowledge transfer process is worth significantly more to a post-funding engineering team than one that ships faster with no documentation.

2: How much does it cost to hire a web application development company to build a SaaS MVP?

SaaS MVP development costs vary widely depending on product complexity, team location, and timeline. A basic SaaS MVP with user authentication, a core feature set, and billing integration typically ranges from $25,000 to $75,000 with an experienced development partner. Offshore agencies may deliver comparable functionality at lower rates. The more important cost consideration is the long-term: an MVP built with poor architecture decisions can cost twice as much in post-funding rework as the original development spend.

3: How long does it take to build a SaaS MVP with a development company?

A focused SaaS MVP built by an experienced development company typically takes 10 to 16 weeks from signed contract to launch-ready product, depending on feature scope and the agency’s bandwidth. Timelines shorter than 10 weeks usually indicate a development company that is either cutting quality corners or has not accurately scoped the engagement. The discovery and scoping phase should take two to three weeks on its own before any code is written.

4: What technology stack should a web application development company use for a SaaS MVP?

The technology stack for a SaaS MVP should be chosen based on the founding team’s hiring roadmap and the product’s scalability requirements, not the agency’s preferred tools. A widely adopted combination for early-stage SaaS products is React or Next.js on the frontend paired with Node.js or a Python framework on the backend, with PostgreSQL as the primary database. These choices maximize the available engineering talent pool for post-funding hiring and avoid forced migration events as the product scales. Any development partner should be able to justify their stack recommendation with a specific rationale tied to the product and business stage.

5: What happens if a web application development company builds a bad MVP codebase?

When a SaaS MVP codebase is built with poor architecture decisions, insufficient test coverage, or no documentation, the post-funding outcome is typically one of three paths: a full rewrite before feature development can resume, a slow and expensive remediation process that delays the product roadmap, or a gradual accumulation of technical debt that constrains engineering velocity until it forces a crisis. The best way to avoid this is to evaluate development partners on architecture quality, handoff standards, and references from post-launch outcomes before signing, rather than on delivery speed and price alone.

Ready to Build a SaaS MVP That Survives Post-Funding Engineering Review?

The difference between an MVP that accelerates a company and one that stalls it is almost never the idea. It is the architecture, the documentation, and the quality of the engineering decisions made before the first line of code was written.

If you are evaluating development partners for a SaaS MVP, the questions in this guide are the ones that separate build shops from genuine product engineering partners.

Talk to the Skyram Technologies team about your SaaS MVP and walk through your product requirements, your funding timeline, and the technical decisions that will determine whether your codebase has a future.

Backend Developer Hiring Guide: API Architecture, Database Design, and What to Actually Test

Engineering manager reviewing backend developer evaluation framework covering API design, database architecture, and technical screening criteria

There is a pattern that shows up repeatedly in engineering orgs that have scaled past 20 engineers: a backend developer passes every interview, earns high marks on the LeetCode problems the team spent three weeks curating, and joins with strong references. Eighteen months later, the APIs they shipped have no versioning strategy. The ORM layer generates N+1 queries at every nested relationship. There is no rate limiting on any authentication endpoint. The error responses are inconsistent across services. And the database has no composite indexes to support the join patterns the application actually runs.

The hire was not a fraud. They genuinely solved the graph traversal problems. They just never had to think about what happens when 200,000 users hit the same endpoint on a Tuesday morning.

Hiring a backend developer requires evaluating API design philosophy, database architecture decisions under load, error handling patterns, and security implementation, not algorithmic puzzle performance. Most backend hiring failures trace back to evaluating candidates on data structure trivia while missing the architectural thinking that determines whether their systems scale, stay secure, and survive production incidents.

This guide is the technical evaluation reframe. It covers what production-scale backend development actually requires, how to build a screening process that surfaces real architectural thinking, and what red flags look like when you know where to look.

What Backend Development Actually Involves at Production Scale

Before you can evaluate a backend developer fairly, you need a clear picture of what the role demands in a production environment. The gap between toy code and production systems is where most interview processes fall apart.

API Design: RESTful Principles, GraphQL Trade-offs, Versioning Strategy

A senior backend developer does not just write endpoints. They make decisions about resource modeling, HTTP verb semantics, response envelope structure, pagination strategy, and deprecation paths. RESTful API design done well means resources are predictable, stateless operations are consistent, and error codes are semantically meaningful rather than generic 500s with opaque messages.

GraphQL adds a different layer of complexity. It solves the over-fetching and under-fetching problems that plague REST at scale, but it introduces n+1 query risks at the resolver level if the developer has not implemented data loader patterns. A backend developer who defaults to GraphQL without understanding DataLoader, query depth limits, and resolver caching costs more in infrastructure than they save in frontend flexibility.

Versioning strategy is where many developers have no opinion at all, which is itself a signal. URL versioning, header versioning, and content negotiation each carry trade-offs in discoverability, cacheability, and client migration burden. A backend developer who has shipped real APIs should have a reasoned position on which approach fits which context and be able to explain what breaking changes actually are versus additive ones.

Database Architecture: SQL vs. NoSQL Selection Rationale, Indexing Philosophy, Query Optimization

The SQL vs. NoSQL question has a correct answer in most contexts, but the correct answer is almost never “one or the other.” A backend developer operating at production scale understands that PostgreSQL is a strong default for transactional workloads with relational data and complex query patterns, while MongoDB or Cassandra earn their place in high-write, schema-flexible, or horizontally distributed scenarios. The selection rationale matters more than the selection itself.

Indexing philosophy separates developers who have operated at scale from those who have not. Creating an index on every queried column is a novice move that inflates write overhead and bloats storage. A developer who understands query planning looks at the access patterns first, then indexes for selectivity and cardinality, builds composite indexes that match the actual column order in WHERE and JOIN clauses, and knows when a partial index covers a use case at a fraction of the cost.

Query optimization is not a one-time tuning pass. It is a design habit. The developers who produce systems that survive production load think about query cost when they write the ORM query, not after the database starts timing out under traffic. This includes understanding when to use raw queries over ORM-generated SQL, how connection pooling affects concurrent request handling, and when denormalization is the right answer rather than a dirty workaround. Supporting all of this with robust backend web development practices from the start saves significant remediation cost later.

Server Infrastructure and Microservices Boundary Decisions

Backend developers who have operated in production environments have an opinion on where services should split and where they should stay together. Premature microservice decomposition is a real failure mode: teams that split services before they understand domain boundaries end up with distributed monoliths that have all the operational overhead of microservices and none of the scalability benefits.

The boundary decision requires understanding data ownership, API contract stability, deployment frequency mismatch between components, and team autonomy requirements. A backend developer should be able to articulate the specific trade-off they are making when they draw a service boundary, including the added complexity of distributed transactions, eventual consistency, and cross-service authentication. This is the kind of thinking that connects backend engineering decisions to broader DevOps delivery patterns.

Key Takeaway: Backend development at production scale means API design philosophy, database architecture judgment, and infrastructure boundary decisions. Candidates who operate at this level have opinions grounded in production experience, not framework documentation.

The Technical Screen That Surfaces Real Backend Thinking

The goal of a technical evaluation is not to verify that someone can write code. Any developer can write code in a structured interview setting. The goal is to surface how they think when they face architectural decisions, constraints, and trade-offs. The exercises below are designed to reveal that thinking.

API Design Exercise: Build a Rate-Limited Authentication Endpoint

Give the candidate a scenario: design a POST /auth/token endpoint that issues JWT tokens. The endpoint needs to handle 50,000 requests per minute at peak, prevent brute force attacks against user credentials, and return consistent error responses that do not expose internal state.

What you are watching for is not whether they get the JWT structure right. You are watching whether they ask about the rate-limiting strategy before they write any code. Do they ask whether rate limiting happens at the load balancer, the API gateway, or the application layer? Do they know the difference between a token bucket and a fixed window counter? Do they think about Redis as a distributed rate limit store before suggesting an in-memory approach that breaks under horizontal scaling? Do they understand that 401 and 429 responses need to be structurally consistent so clients can handle them without custom logic per endpoint?

A candidate who jumps straight into writing the token generation logic without addressing the rate limiting strategy has told you something important about how they sequence priorities in production contexts.

Database Scenario: How Would You Handle 10M Write Operations Per Day?

Present this as an open-ended architecture problem. Ten million write operations per day is approximately 115 writes per second at constant load, with real-world spikes that could push 3 to 5 times that. Ask them to design the database layer.

Strong candidates immediately ask what the read/write ratio looks like, whether writes are time-sensitive or can be batched, and whether reads need to be consistent with the most recent write or whether eventual consistency is acceptable. They surface the connection pooling question early. They think about write-ahead logging implications and checkpoint frequency. They discuss whether a message queue sits in front of the database to absorb spikes or whether the system writes directly.

A candidate who says “we would use PostgreSQL” and stops there has given you a technology choice, not an architecture. The architecture question is about how you configure PostgreSQL to handle that write volume, when you consider read replicas, when partitioning makes sense, and what the monitoring story looks like when write latency starts to degrade. Pairing that kind of thinking with sound CI/CD pipeline practices is what enables teams to deploy database schema changes safely at that scale.

Architecture Question: Where Would You Put the Boundary Between These Two Services?

Give them a domain: an e-commerce order management system where inventory updates and order placement are tightly coupled. Ask them where they would draw the service boundary if they had to decompose this.

What you are listening for is their reasoning process, not their conclusion. Do they ask about the transaction requirements between inventory and order state before making a decision? Do they know that a distributed saga pattern is different from a two-phase commit and understand when each applies? Do they recognize that if inventory updates and order creation always happen together and are owned by the same team, they might belong in the same service regardless of what the domain model suggests?

Strong candidates hold the tension between theoretical domain purity and operational practicality. They make the case for a boundary, acknowledge the distributed transaction complexity it introduces, and explain what they would build to manage that complexity. Candidates who recite microservices principles without acknowledging the operational cost are giving you theory, not engineering.

Comparison: Algorithmic Interview vs. Architecture-Focused Evaluation

Dimension Algorithmic Interview Architecture-Focused Evaluation
Primary skill measured Data structure manipulation under time pressure System design judgment under realistic constraints
Signal quality for production performance Low: correlates with interview preparation, not engineering output High: reveals how the candidate actually thinks about trade-offs
Failure mode Passes candidates who cannot design a scalable system May require more interviewer preparation and calibration
Time investment 45-90 minutes per candidate 90-120 minutes per candidate, but fewer surprise post-hire failures
Prediction accuracy for senior backend roles Poor for architectural decisions Strong for both architecture and collaboration behaviors
Candidate experience Often perceived as adversarial, particularly by senior engineers Perceived as professionally relevant and conversational

Key Takeaway: Architecture-focused evaluations take more preparation to run well, but they return higher-fidelity signal on the decisions that actually matter in production. The added investment in screening pays back in avoidable rework.

Security Implementation as a Hiring Filter, Not an Afterthought

Security in backend development is not a specialty skill. It is a baseline engineering habit. Candidates who treat it as a separate discipline rather than an integrated concern tend to produce systems where vulnerabilities appear at layer boundaries, not at the obvious entry points.

Authentication and Authorization Design

The most common authentication failure in backend systems is not a broken algorithm. It is poor scope design on tokens, missing token expiry enforcement, or authorization logic that lives in the wrong layer of the stack. A backend developer should be able to explain the difference between authentication and authorization without being prompted, articulate when a session token is more appropriate than a JWT, and describe what happens to tokens that need to be revoked before they expire.

Role-based access control at the application layer should be a design conversation, not an afterthought. Ask candidates how they would implement multi-tenant data isolation. Listen for whether they think about row-level security at the database layer, tenant ID enforcement at the API middleware layer, or both. Either answer can be valid depending on the architecture, but a candidate with no opinion on the question has not built multi-tenant systems at scale.

Input Validation and Injection Prevention Habits

SQL injection is a decades-old vulnerability class, and it still appears in production systems regularly because input validation gets treated as a task rather than a habit. Ask a candidate how they approach input validation in a framework they know well. A strong answer involves parameterized queries as a default rather than a conscious choice, structural validation before the data hits any persistence layer, and schema-level enforcement that does not rely on application code to catch every edge case.

OWASP injection categories beyond SQL matter just as much: NoSQL injection, command injection, and LDAP injection patterns all follow similar input validation failures. A backend developer who has only thought about SQL injection has a gap that will appear at the first non-relational data layer they touch.

How They Approach Secrets Management and Environment Configuration

Ask a candidate where they store API keys, database credentials, and service tokens in a production deployment. The correct answer involves environment variable injection from a secrets manager such as AWS Secrets Manager, HashiCorp Vault, or equivalent, not hardcoded values, not .env files committed to the repository, and not plaintext configuration files in the deployment bundle.

The follow-up that separates experienced engineers from junior ones is what happens when a secret rotates. Does the application handle secret rotation without a deployment? Can it pull an updated credential from the store at runtime? A developer who has thought about secret rotation has operated in environments where secrets get exposed and have needed to respond. That operational exposure matters at production scale.

Key Takeaway: Security implementation in backend development is observable in the habits and defaults a candidate describes. Treat it as a filter during evaluation, not a topic to cover in a security-specific role.

The Red Flags That Standard Interviews Do Not Catch

These signals rarely appear in algorithmic screens. They surface in architecture conversations and design exercises. Once you know what to listen for, they are consistent.

No Opinion on API Versioning Strategy

A backend developer who has shipped production APIs and then had to change them has necessarily confronted the versioning problem. If a candidate has no opinion on URL versioning versus header-based versioning, has never thought about what constitutes a breaking change, or cannot explain how they communicate API deprecation to consuming clients, they have not maintained a live API through a non-trivial lifecycle.

This is not about having the right answer. It is about having any answer grounded in real experience. The absence of opinion on this question consistently predicts that versioning decisions get deferred until they become migration emergencies.

“We’ll Optimize the Queries Later” as a Default Position

This phrase is not a legitimate deferral strategy. It is an indication that the candidate does not yet think about query cost as part of design. Optimization that happens after a performance incident requires refactoring under pressure, often with production data volumes that make schema changes expensive and risky.

Strong backend developers design queries with the execution plan in mind from the beginning. They know what EXPLAIN ANALYZE returns before the query hits production. They recognize the access patterns a feature requires and build the index strategy before the feature ships, not in response to a Datadog alert six months later. Connecting database performance thinking to the AWS Cloud Services or platform infrastructure in use is part of that design discipline.

Unable to Explain Their Database Index Design Decisions

Ask a candidate to walk you through the indexing strategy for a table they designed in a previous role. A specific question about a specific decision reveals more than any general discussion of indexing theory.

What you are listening for is whether they can explain why they chose a particular index, what query pattern it was designed to serve, and what trade-off they accepted in write performance to get the read optimization. A developer who says “we indexed the foreign keys and the commonly queried columns” without being able to explain the cardinality reasoning or the composite index ordering has followed a pattern without understanding the underlying principle. That gap reliably produces poorly indexed schemas when the pattern does not directly apply.

Key Takeaway: The red flags that matter most are not dramatic. They are quiet absences: no versioning opinion, no query cost awareness, no index rationale. These absences appear at scale as the systems a developer ships begin to degrade under real load.

Staff Augmentation vs. Full-Time Hire for Backend Development Capacity

Engineering managers facing backend capacity gaps have two realistic options, and the right choice depends on the nature of the work, not a blanket preference.

Full-time backend hires make the most sense when the backend systems are core to the product, will evolve continuously over multiple years, and require deep context about the domain model, data relationships, and business rules. A full-time hire builds that context over time. The investment in onboarding pays back in the accumulated institutional knowledge that shapes better architectural decisions in subsequent quarters.

Staff augmentation makes more sense when the capacity need is tied to a defined initiative, a backlog of technical debt work, or a specific build that has a foreseeable completion point. It also makes sense when the full-time hiring market for the specific backend specialization, say a Node.js developer with GraphQL and PostgreSQL at scale experience, is tight enough that a search would take four to six months and the need is active now.

The hidden cost of the full-time model is the search timeline. A senior backend developer search in a competitive market takes eight to fourteen weeks from open requisition to accepted offer, then another thirty to sixty days before the hire is productive in the codebase. Teams running lean backend capacity often cannot afford that timeline when a critical feature or infrastructure initiative is in flight.

A staff augmentation model through a partner with backend engineering depth, including established web application development and API architecture capabilities, compresses that timeline significantly. The trade-off is less domain context accumulation over time, which is why the engagement design matters: knowledge transfer, documentation standards, and code review processes need to be deliberate rather than assumed.

Key Takeaway: The full-time vs. augmentation question is not a values question about build vs. buy. It is a timeline and context question. Match the model to the nature of the work and the realistic hiring timeline, not to a general preference.

Onboarding a Backend Developer Into an Existing Codebase

The onboarding experience for a new backend developer determines how quickly they contribute quality work and how many avoidable mistakes they make in the first ninety days. Most onboarding gaps are documentation gaps.

The first thing a new backend developer needs is not access to the repository. It is a map of the system: the service boundaries, the data flow between components, the queue topology if one exists, and the critical paths that cannot be broken without a production incident. This documentation is almost never written by the time a new hire joins because the people who know it have it in their heads, not in a document.

The second thing they need is a clear picture of the database schema and its evolution history. An undocumented schema is a mystery that a new developer will solve by reading the ORM models and running queries, both of which take time and produce incomplete understanding. A schema diagram with relationship annotations and a migration history that explains why certain design decisions were made saves two to three weeks of archaeology.

The third thing they need is a production incident history or a post-mortem archive. The systems a new developer touches are shaped by decisions made in response to failures that happened before they joined. Without that context, they will make changes that recreate the conditions of incidents the team already worked through. Connecting the new developer to the Kubernetes or infrastructure monitoring that covers the systems they will own is part of this same orientation process.

Technical onboarding should include a code review period of two to three weeks where the new developer’s pull requests get thorough review with detailed rationale in comments, not just approval or rejection. This builds shared understanding of code standards, architectural preferences, and the specific trade-offs the team has previously made. It also surfaces gaps in the developer’s background before they have shipped anything to production.

Key Takeaway: Backend developer onboarding is a documentation investment. The teams that onboard backend engineers most effectively have system maps, schema documentation, and incident history ready before the first day, not assembled over the first ninety days.

Frequently Asked Questions

1: What is the most important thing to evaluate when hiring a backend developer?

The most important factor to evaluate is architectural thinking under realistic constraints. Backend developers who can explain why they made a database design decision, how they approach API versioning strategy, and what they consider when drawing service boundaries deliver substantially better production outcomes than those who excel at isolated algorithm problems. Technical screens that test system design judgment, error handling philosophy, and security implementation habits surface higher-quality signal than data structure puzzles for backend roles operating at production scale.

2: How do you assess a backend developer’s database skills in an interview?

Database skills are best assessed through scenario-based questions tied to realistic volume and access pattern constraints. A strong approach presents a write-heavy scenario, such as ten million operations per day, and asks the candidate to design the database layer, including indexing strategy, connection pooling configuration, and read/write separation decisions. Asking the candidate to walk through a specific indexing decision they made in a previous role reveals whether they understand cardinality, composite index ordering, and the write overhead trade-off, or whether they followed a pattern without understanding the underlying principle.

3: What is the difference between API versioning approaches, and which one should a backend developer be able to explain?

The three primary API versioning approaches are URL versioning (embedding the version in the path, such as /v1/resource), header-based versioning (passing a version header in the request), and content negotiation (using the Accept header to specify the desired version). URL versioning is the most discoverable and easiest to cache. Header versioning keeps the URL clean but is less visible to clients. Content negotiation follows HTTP specifications most closely but adds complexity for simple clients. A backend developer hiring for a production system should be able to explain the trade-offs between these approaches, define what constitutes a breaking change versus an additive change, and describe how they communicate API deprecation timelines to consuming teams.

4: How do you evaluate a backend developer’s security knowledge without running a dedicated security audit?

Security knowledge surfaces naturally in three question areas: authentication and authorization design, input validation habits, and secrets management practices. Asking a candidate how they approach multi-tenant data isolation reveals whether they think about authorization at the application layer, database layer, or both. Asking about their input validation approach reveals whether parameterized queries and schema validation are defaults or afterthoughts. Asking where credentials live in a production deployment reveals whether they have built systems with proper secrets management or have relied on .env files and hardcoded configuration. These questions require no security-specific test; they reveal security thinking embedded in general backend engineering practice.

5: When should a company use staff augmentation instead of hiring a full-time backend developer?

Staff augmentation is the stronger choice when the capacity need is tied to a defined initiative, when the full-time hiring timeline of eight to fourteen weeks or more would delay a critical delivery, or when the required backend specialization is difficult to source in the full-time market. Full-time hiring is the stronger choice when the backend systems are core to the product, will evolve continuously over multiple years, and benefit from accumulated domain context that a long-tenured engineer builds over time. The decision should match the nature and duration of the work, not a general organizational preference for one model over the other.

6: What are the most common red flags in a backend developer’s technical interview?

The most predictive red flags are the absence of opinions on API versioning strategy, a default position that query optimization is a post-launch concern rather than a design habit, and an inability to explain the reasoning behind specific database index decisions. A candidate who cannot articulate what a breaking API change is, who does not think about query execution cost during design, or who describes indexing as adding an index to every queried column without understanding cardinality or composite index ordering will produce systems that degrade predictably under real production load. These signals rarely appear in algorithmic interviews; they surface in architecture conversations and design exercises that test production-scale judgment.

Talk to Skyram About Backend Development Resources

Hiring a senior backend developer takes time the engineering roadmap often cannot absorb. The search, the evaluation, the offer, and the ramp period add up to five to seven months before a new hire contributes at full capacity. Skyram’s backend engineering team covers API architecture, database design, and production deployment for US businesses that need that capacity in weeks, not months.

Connect with Skyram about backend development resources

Hiring a DevOps Partner for Your SaaS Startup: What to Define Before the First Call

Hiring a DevOps Partner for Your SaaS Startup

You get on a discovery call with a DevOps partner. Thirty minutes in, they are still asking you which cloud provider you use. An hour later, they need to schedule a second call because you could not answer questions about your deployment frequency, your current monitoring setup, or who handles on-call when something breaks at 2 AM.

Three weeks and five back-and-forth emails later, the actual engagement has not started. The onboarding document they sent you is forty percent questions you should have been able to answer before you picked up the phone.

This is the most common failure mode in DevOps partner engagements, and it is entirely avoidable.

SaaS startups that hire a DevOps partner without defining their current infrastructure state, deployment frequency goals, cloud platform requirements, and on-call expectations before the first conversation waste the first two to four weeks of an engagement on discovery that should have been internal homework. The most successful DevOps partner engagements start with a CTO who can hand over a clear infrastructure brief, not a vague request to “set up DevOps.”

This post gives you that brief. Work through it before you contact anyone, and you will compress the path from first conversation to productive engagement by weeks.

The Internal Audit to Run Before You Talk to Any DevOps Partner

Before you evaluate a single partner, you need a current and honest picture of your own infrastructure. Skipping this step does not save time. It transfers that time to the partner’s discovery phase, where you pay for it twice over.

1. Current infrastructure state: what exists, what’s documented, what isn’t

Start with an honest inventory. List every environment you run (production, staging, development), the services deployed in each, and how those services communicate. Note which parts have infrastructure-as-code coverage and which have been stood up manually over time and never documented.

Most early-stage SaaS teams will find that the ratio of documented to undocumented infrastructure skews heavily toward the latter. That is not a disqualifier for engaging a partner. It is simply information a good partner needs to scope the work accurately. If you walk into the first call without knowing this ratio yourself, you will spend the first three weeks paying someone to figure it out alongside you.

Document whether you have a cloud configuration in version control, whether your secrets are managed centrally or scattered across .env files, and whether your infrastructure can be torn down and rebuilt from code or whether it is a collection of manually configured resources that only one engineer fully understands. Connecting this work to a broader cloud engineering conversation down the line will be far easier if you have this baseline ready.

2. Deployment frequency: how often do you ship, and what breaks the process today?

Deployment frequency is one of the most revealing metrics in any DevOps engagement. Before you talk to a partner, pull your actual numbers. How often does code reach production per week? Per sprint? Are you doing it manually or through some form of automation? What is your rollback process when something goes wrong?

More important than the number itself is the friction behind it. Ask your engineering team directly: what breaks the deployment process most often? The answers are typically a short and painful list: flaky test suites that cause false failures, manual steps that require a senior engineer to be available, no staging environment that accurately mirrors production, or a CI/CD pipeline that was cobbled together two years ago and never maintained.

Your partner cannot fix problems you have not named. Write these down before the call and bring them as a list, not as a vague complaint that deployments feel slow.

3. Cloud platform and toolchain: what are you on, and what’s non-negotiable?

Define your cloud footprint before the engagement starts. Are you on AWS, GCP, Azure, or a mix? Do you have any multi-cloud dependencies locked in through pricing agreements or compliance requirements? Are there services you are not willing to migrate away from because an engineering decision three years ago built a product dependency on them?

Every SaaS startup has some combination of hard constraints and preferences. A good DevOps partner needs to know which is which. If you are deep into AWS cloud services and have no intention of moving, that is a hard constraint. If you have a vague preference for Terraform over Ansible but no existing code in either, that is a preference they can push back on with good reason.

Write out your toolchain clearly: your source control platform, your current CI/CD tool if any, your observability stack, your container orchestration setup if you have one, and any security or compliance tooling already in place.

The Four Scope Decisions That Define Your DevOps Engagement

Once your internal audit is done, you need to make four scope decisions before you talk to anyone. These are not questions for the partner. These are answers you need to arrive with.

1. CI/CD pipeline ownership: build from scratch or optimize what exists?

Be honest about the state of your current pipeline. If you have one, does it actually work reliably, or does it exist on paper while your team deploys manually whenever the automation fails? There is a meaningful difference between a partner engagement scoped to build a CI/CD pipeline from zero and one scoped to optimize, extend, or repair something that already exists.

Partners price and staff these very differently. Arriving without clarity on this decision leads to a proposal that does not match your actual problem, which leads to renegotiation after the contract is signed.

2. Monitoring and alerting: what’s in place and what’s missing?

List what you currently observe about your system. Do you have application performance monitoring? Error tracking? Infrastructure-level alerting? Log aggregation in a queryable format? Or are you running on the assumption that if something breaks badly enough, a user will tell you?

Startups typically fall into two camps here. The first has a partial observability setup, something like Datadog or Sentry, but no alert routing, no runbooks, and no clear owner when an alert fires. The second has nothing and relies entirely on reactive incident response. Your partner needs to know which camp you are in before scoping the monitoring component of the engagement.

3. On-call and incident response: what do you need from a partner at 2 AM?

This is the question most SaaS founders underestimate in the scoping phase. On-call expectations are a contract decision, not a technical one, and they need to be in the room before any technical discussions happen.

Do you expect your DevOps partner to be reachable during a production outage? What SLA do you need on incident acknowledgment? Who owns the incident bridge? Who has access to roll back a deployment at 3 AM on a Sunday? If you are working with a managed DevOps setup, these terms need to be written into the contract from day one, not assumed.

Partners who are not asked these questions up front will not volunteer them. You will discover the gap at the worst possible time.

4. Security and compliance: SOC 2, HIPAA, or baseline cloud security hygiene?

If your SaaS product handles health data, financial data, or enterprise customer data, your compliance requirements directly shape the DevOps engagement scope. SOC 2 Type II readiness requires specific controls around access logging, secrets management, vulnerability scanning, and audit trails. HIPAA requires encryption standards and data segregation. Arriving at the first call without knowing where you are against these requirements means your partner cannot scope for them.

Even if you are pre-compliance, define your target state. Do you plan to pursue SOC 2 in the next 12 months? Are enterprise customers already asking for it? That roadmap belongs in the brief.

Comparison Table: Under-Scoped vs. Well-Defined DevOps Brief

Area Under-Scoped Brief Well-Defined Brief
Infrastructure state “We have some things on AWS” Current environment inventory, documented vs. undocumented split, IaC coverage
Deployment frequency “We deploy pretty often” Actual deploy frequency, manual vs. automated steps, known friction points
Pipeline status “We have a CI/CD thing” Tool name, reliability history, what works and what does not
Cloud platform “Mostly AWS” Specific services, hard constraints, pricing agreements, migration non-negotiables
Monitoring “We use some tools” Tool list, alert routing status, runbook existence, observability gaps
On-call expectations Never discussed SLA requirements, incident response ownership, contact protocol written into scope
Compliance “We’ll deal with it later” Current compliance posture, target certifications, timeline
First 30 days result 2 to 4 weeks of discovery, delayed start Week 1 starts with scoped work, first deliverable by end of Week 2

Key Takeaway: The quality of your DevOps brief determines how quickly productive work begins. A vague brief does not save you preparation time. It transfers that time into the partner’s paid discovery phase.

The Engagement Model Decision: Managed DevOps vs. Staff Augmentation vs. Project-Based

Before you write a single line of an RFP, decide which engagement model fits your current stage. This decision shapes everything from how you evaluate candidates to how you structure contracts and measure outcomes.

Managed DevOps means your partner takes ongoing ownership of infrastructure operations. They own the monitoring, respond to incidents within a defined SLA, and maintain your environments on an ongoing basis. This model works well for early-stage SaaS teams that have no dedicated infrastructure person internally and need someone accountable for uptime and reliability.

Staff augmentation means you embed a DevOps engineer or architect into your team temporarily. They work alongside your engineers, contribute to daily operations, and transfer knowledge as they go. This works when you have a clear technical backlog and need execution capacity, not strategic ownership.

Project-based engagement means you define a specific deliverable, a pipeline build, a Kubernetes migration, an observability implementation, and engage a partner to deliver that specific scope on a fixed timeline. This works when your internal team can own the output after delivery and you do not need ongoing managed support.

Most early-stage SaaS teams underestimate how much ongoing operational support they actually need. The impulse is to scope a project, take delivery, and move on. The reality is that Kubernetes cluster management, pipeline maintenance, and security patching require continuous attention. Know which model you actually need before you start evaluating partners, because each model attracts different providers and carries different pricing structures.

What to Include in Your DevOps Partner RFP or Brief

A strong RFP does two things simultaneously. It tells partners exactly what you need, and it filters out partners who cannot honestly deliver it. A weak RFP attracts proposals that sound similar, making evaluation nearly impossible.

Infrastructure documentation requirements

Specify what documentation you expect as a deliverable, not just as a byproduct of the work. Architecture diagrams for all environments, runbooks for common operational procedures, secrets management documentation, and a post-engagement handover package. Partners who balk at documentation requirements will create the same undocumented environment you are trying to fix.

Communication and escalation protocol expectations

Define response time expectations upfront. How quickly do you need acknowledgment on a production incident? Who is the named point of contact on the partner side? What is the escalation path if the named contact is unavailable? These specifics belong in the RFP, not in a side conversation after the contract is signed.

Deliverable timeline and milestone structure

Avoid open-ended engagement timelines. Structure the work around milestones with acceptance criteria, so both parties agree on what done looks like at each stage. A well-structured milestone plan protects you from engagement drift, where a three-month project becomes a six-month engagement because neither party defined completion clearly.

How to Evaluate a DevOps Partner’s SaaS Startup Track Record

A partner’s capability on paper is not the same as their capability for your specific context. SaaS startup infrastructure has distinct characteristics that not every DevOps partner has worked with: multi-tenant data isolation requirements, feature flag infrastructure, continuous deployment into a live customer environment, and the operational reality of an engineering team that is also building the product while managing infrastructure.

1. What stage of company have they worked with?

Ask directly whether they have worked with companies at your revenue stage, your team size, and your infrastructure complexity. A partner who has delivered for 500-person Series C companies with dedicated SRE teams is not automatically equipped to work effectively with a 12-person team where the founding CTO is also the on-call engineer. The operational assumptions are completely different.

2. How do they handle the “we have no documentation” situation?

Every SaaS startup has some version of this situation. The reliable test is to ask the partner how they approach it. A strong partner will describe a structured discovery process that they own, not one that depends on your team reconstructing the history of every infrastructure decision you ever made. They should be able to start from an environment access and produce a working baseline inventory. If their response is to tell you that you need to document things before they can start, you have found a partner who is not equipped for your context.

3. What’s their knowledge transfer process when the engagement ends?

Knowledge transfer is the most commonly neglected part of DevOps partner engagements. Ask specifically: what does your team know how to do independently when this engagement is over? What documentation will exist? What training sessions are included? What is the handover process?

Partners who cannot answer this specifically are partners who will make themselves hard to replace, intentionally or not.

The First 30 Days With a DevOps Partner: What Good Looks Like

The first 30 days of a DevOps engagement are a reliable signal for how the rest of the relationship will perform. A well-scoped engagement, started by a CTO who did their internal homework before the first call, should produce the following outcomes in the first month.

By the end of Week 1, your partner should have completed a full environment audit, documented what exists, identified the three to five most critical gaps, and agreed with your team on which gaps the engagement will address in priority order.

By the end of Week 2, the first deliverable should be in progress. Whether that is a pipeline build, a monitoring implementation, or an infrastructure documentation package, something tangible should be underway, not still in planning.

By the end of Week 3, you should have a working communication rhythm: a defined standup cadence, a shared tracking tool, and a clear escalation path you have already tested at least once with a low-stakes question.

By the end of Week 30, you should be able to answer clearly: what works now that did not before, what has been handed off to your team, and what the partner is still responsible for going forward.

If none of those milestones are visible at Day 30, something went wrong in the scoping phase. The most common cause is that the brief going into the engagement was not specific enough to allow either party to hold the other accountable. That is the problem this guide exists to solve.

Frequently Asked Questions

  1. What should a SaaS startup define before hiring a DevOps partner?

A SaaS startup should define its current infrastructure state, deployment frequency and known friction points, cloud platform requirements and non-negotiable constraints, monitoring and observability gaps, on-call and incident response expectations, and any compliance requirements such as SOC 2 or HIPAA before engaging a DevOps partner. Startups that complete this internal scoping exercise before the first call reduce the partner’s discovery phase from two to four weeks to a matter of days, allowing productive work to begin significantly faster.

What is the difference between managed DevOps and staff augmentation for a SaaS company?

Managed DevOps means the partner takes ongoing operational ownership of the startup’s infrastructure, including monitoring, incident response, and environment maintenance under a defined SLA. Staff augmentation means a DevOps engineer embeds into the startup’s team to execute a defined backlog alongside internal engineers, with the expectation that the startup’s team owns operations after the engagement. Early-stage SaaS companies with no dedicated infrastructure person typically benefit more from a managed DevOps model, while companies with existing DevOps capacity and a specific delivery gap tend to benefit more from staff augmentation.

  1. How do I evaluate a DevOps partner’s experience with SaaS startups specifically?

Ask the partner directly about the stage, team size, and infrastructure complexity of the SaaS companies they have worked with previously. Request case studies from companies at a similar revenue and headcount stage. Ask specifically how they handle engagements where infrastructure documentation is minimal or nonexistent, since this is a near-universal condition in early-stage SaaS environments. A credible partner will describe a structured discovery process they own rather than one that depends on the startup providing a clean infrastructure history.

  1. What should be included in a DevOps partner RFP for a SaaS startup?

A DevOps partner RFP for a SaaS startup should include a current infrastructure summary, the specific engagement model being requested (managed, staff augmentation, or project-based), a description of the problems being solved rather than a list of tools to be implemented, compliance requirements if applicable, documentation deliverables required at the end of the engagement, communication and escalation protocol expectations, and a milestone structure with acceptance criteria for each phase. RFPs that specify outcomes rather than only activities attract proposals that are easier to evaluate and hold accountable.

  1. How long does it take for a DevOps partner engagement to produce results for a SaaS startup?

A well-scoped DevOps partner engagement where the startup completed internal scoping homework before the first call should produce a tangible deliverable within the first two weeks. An under-scoped engagement where the first two to four weeks are consumed by partner-side discovery typically produces the first tangible output in Week 5 or Week 6. The most consistent predictor of fast time-to-value is the specificity of the brief the startup brings to the first conversation, not the size or reputation of the partner.

Talk to Skyram About DevOps Engagement for Your SaaS Startup

If you have done your internal homework and are ready to have a first conversation that skips the basics and goes straight to the work, Skyram Technologies is structured for exactly that. Our DevOps team works with SaaS startups across the US on managed infrastructure, CI/CD pipeline builds, and cloud architecture engagements. We start with your infrastructure brief, not with a 40-question discovery form.

Book a conversation with our DevOps team and come with the brief you built from this guide. The first call will be more productive than most SaaS teams have in three.

How to Find a Google Ads Manager Who Understands B2B Buying Cycles

How to Find a Google Ads Manager

Finding a Google Ads manager who understands B2B buying cycles means identifying someone who structures campaigns around awareness, consideration, and decision-stage intent separately, not someone who applies a single bidding strategy across all keyword types. B2B buying cycles average 6 to 12 months. A Google Ads manager who has only run B2C campaigns will optimize for immediate conversion signals that do not exist in enterprise buying behavior.

Here is how the failure typically plays out. A CMO brings in a Google Ads manager with genuinely impressive numbers. Their portfolio shows strong CTR improvements, efficient CPCs, and conversion rates that held up under scrutiny. What the portfolio does not show is that every result came from ecommerce and direct-response B2C accounts, where a buyer searches, clicks, and purchases within the same session. Within 90 days of taking over the B2B account, the campaigns are generating high form-fill volume from early-stage researchers who downloaded a whitepaper and will not be ready to buy for six to eight months. Meanwhile, high-intent decision-stage queries from buyers who are actively shortlisting vendors get ignored because the search terms look low-volume and the manager does not recognize them as the most valuable clicks in the account.

This post is the evaluation guide that CMOs and marketing directors need before putting their Google Ads budget behind a manager whose experience does not match the environment they will be working in. It covers what B2B paid search management actually requires, the questions that separate B2B-capable managers from B2C-trained ones, the red flags to watch for in portfolios and interviews, and how to structure the attribution infrastructure that makes any Google Ads engagement measurable against real pipeline.

How B2B Google Ads Management Differs From B2C

The surface-level mechanics of Google Ads are identical across B2B and B2C. Both environments use keyword targeting, bidding strategies, ad copy, and Quality Score. The structural differences sit underneath those mechanics, in how campaigns are organized, what they optimize toward, and how success gets measured over time.

Keyword Intent Stratification Across a 6 to 12 Month Buying Cycle

In B2C ecommerce, keyword intent is relatively flat. Most searches cluster around informational (“what is the best running shoe for flat feet”) and transactional (“buy Hoka Clifton 9 size 11”). The gap between those two intents is measured in days or hours. A buyer researches Monday and purchases Wednesday.

B2B keyword intent spans a much longer timeline and requires deliberate stratification. An enterprise software buyer might search “what is revenue operations software” in January, then “top revenue operations platforms for mid-market SaaS” in March, then “Clari vs Gong comparison” in May, then “Clari pricing and contract terms” in June. Each of those queries represents a different intent stage, a different readiness level, and should trigger a different ad, a different landing page, and a different offer.

A B2B Google Ads manager who understands this architecture builds separate campaigns for each intent layer and sets different conversion objectives and bid strategies across them. Bottom-funnel campaigns targeting decision-stage queries like “best B2B CRM for manufacturing companies” optimize toward demo requests. Middle-funnel campaigns targeting category-awareness terms optimize toward gated content downloads or webinar registrations, measured as micro-conversions, not primary goals. Top-funnel campaigns for problem-awareness queries are managed to engagement signals and brand lift, not direct conversions.

A manager who came up in B2C will compress all of this into one or two campaign types with a single conversion objective and wonder why the lead quality from the high-volume keywords is so poor.

Negative Keyword Strategy for Research-Stage vs. Decision-Stage Queries

Negative keyword management in B2B is substantially more nuanced than in B2C. The stakes are higher because each click costs more and the margin for irrelevance is narrower. In B2B paid search, showing your enterprise software ad to a college student writing a research paper is wasteful at $8 per click. Showing it to an IT Director actively shortlisting vendors is worth $80 per click.

The distinction between those two audiences often comes down to the search terms they use. Research-stage queries frequently include modifiers like “what is,” “how does,” “definition of,” “examples of,” “introduction to,” and “for beginners.” A B2B-experienced manager builds an extensive negative keyword list that filters out research-stage intent from bottom-funnel campaigns, directing those queries toward appropriate upper-funnel campaigns or blocking them entirely if the audience does not match.

Decision-stage negative keyword strategy is equally important. When running competitor conquest campaigns, you need negatives that prevent your ads from showing to people searching for competitor support, competitor login pages, or competitor job openings. Those clicks are expensive and convert at near-zero rates for acquisition purposes. Managers who do not audit search term reports weekly miss these patterns and let budget drain through irrelevant matches continuously.

Bidding Strategy Selection When Conversion Signals Are Sparse and Delayed

Smart bidding in Google Ads works by learning from conversion data. The algorithm needs enough conversion events to identify patterns and predict which future clicks are likely to convert. The standard threshold for stable smart bidding performance is approximately 30 conversions per campaign per month. In B2C ecommerce with transaction volume running in the hundreds, this is trivially achievable. In B2B with a 90-day sales cycle and monthly SQL volume in the single digits, it is a genuine technical constraint.

A B2B-experienced Google Ads manager knows how to navigate this problem. They know to set up micro-conversions, meaningful engagement events like content downloads, video completions, scrolling depth on high-value pages, and time-on-site thresholds, as early optimization signals while the primary conversion data develops. They know to use Maximize Clicks or Manual CPC in new campaigns rather than forcing Target CPA on a dataset too thin to support it. They know that switching to smart bidding before the data is ready produces erratic spend behavior and inflated CPAs that a less experienced manager will misattribute to a poor audience or wrong keyword.

This technical judgment about when automation helps and when it hurts is one of the clearest differentiators between a B2B-capable Google Ads manager and one who is applying a B2C playbook to an environment where it does not fit.

Key Takeaway: B2B Google Ads management requires campaign architecture that mirrors a 6 to 12 month buying cycle, negative keyword discipline that separates research intent from purchase intent, and bidding strategy judgment that accounts for sparse and delayed conversion signals. A manager who does not work this way in B2C accounts will not discover how to do it on the job inside your budget.

The Evaluation Framework for a B2B Google Ads Manager

The interview for a B2B Google Ads manager should function more like a working session than a credentials review. Certifications are table stakes. What you need to surface is how they think about campaign architecture, attribution, and audience design in environments where the feedback loop between ad click and revenue is months long.

1. Campaign Audit Exercise: What Is Wrong with This Search Campaign Structure?

Present the candidate with a simplified version of a flawed B2B search campaign structure and ask them to diagnose it. A well-designed audit exercise might show a single Search campaign with a single ad group, broad match keywords across all intent levels, Target CPA bidding set to a CPA derived from form fills rather than SQLs, and a single landing page for all traffic.

A B2B-capable manager will identify multiple structural problems without prompting. They will call out the intent mixing (decision-stage and research-stage queries in the same campaign bidding at the same CPA). They will question the conversion event choice: if the CPA is based on form fills but the form fills include unqualified research downloads, the algorithm is learning from the wrong signal. They will note the absence of negative keywords and the risks that come with running broad match without them in a B2B account. They will propose a restructure that separates intent layers into distinct campaigns with appropriate conversion objectives for each.

A manager who cannot diagnose a flawed structure in 15 minutes cannot build a sound one from scratch in 90 days.

2. Attribution Question: How Do You Measure Google Ads Contribution in a 90-Day Sales Cycle?

This question surfaces the candidate’s attribution infrastructure knowledge. A strong answer describes their approach to offline conversion import: CRM pipeline events pushed back into Google Ads so that MQL-to-SQL progressions and opportunity creation events become the optimization target rather than raw form fills. They will discuss multi-touch attribution and what model they prefer for assigning value across a long cycle. They will mention GA4 integration, conversion window settings appropriate for a 90-day sales process, and how they communicate attribution limitations to leadership.

A weak answer describes last-click attribution as if it solves the B2B measurement problem. Last-click attribution in a 90-day multi-touch cycle systematically undervalues upper-funnel campaigns that introduce buyers to your brand and systematically over-rewards the final touchpoint before form submission. A manager who does not recognize this will misallocate budget toward bottom-funnel campaigns and starve the awareness layer that feeds pipeline months later.

3. Audience Design: How Would You Structure Remarketing for a Buying Committee?

B2B purchases involve an average of six to ten stakeholders. Remarketing in this context is not about showing an ad to a single user who visited your pricing page. It is about maintaining brand presence across multiple people at the same company who are each conducting independent research and comparing notes internally.

A B2B-experienced manager designs remarketing audiences that account for this. They segment by page visited and stage implied: visitors who hit product or solution pages (higher intent) versus visitors who hit blog posts (earlier stage) should be served different messages and different offers. They use Customer Match to upload company domain lists and target signed-in Google users from those accounts. They adjust remarketing window lengths to match the actual evaluation cycle, setting 90-day or 180-day windows rather than defaulting to 30 days. They understand that the goal is coordinated presence across a committee, not repeated exposure to one individual.

4. B2C Google Ads Profile vs. B2B-Capable Google Ads Manager: Side-by-Side

B2C Google Ads Profile B2B-Capable Google Ads Manager
Campaign Structure Unified campaigns with single conversion objective Intent-layered: awareness, consideration, decision, retargeting
Keyword Strategy Match types optimized for volume and conversion rate Intent stratification with aggressive negative keyword development
Bidding Approach Target ROAS or Target CPA from day one Micro-conversions in early stages; smart bidding introduced once data supports it
Conversion Events Transactions or form fills Form fills plus offline CRM events (SQL, opportunity created, closed-won)
Measurement Framework Last-click, platform-reported ROAS Multi-touch attribution, CRM integration, 90-day conversion windows
Remarketing Design Individual user based on browse and purchase behavior Company-level and committee-aware audience segmentation
Reporting Focus CTR, CPC, ROAS by campaign Cost-per-SQL, cost-per-opportunity, pipeline velocity by campaign
Sales Team Relationship Minimal; marketing owns the handoff Required for lead scoring alignment and quality feedback loops

Key Takeaway: Evaluating a Google Ads manager for B2B requires working exercises, not credential checks. The campaign audit, the attribution question, and the audience design question will reveal faster than any portfolio review whether the candidate thinks in B2B terms or is translating B2C expertise into B2B vocabulary without the substance to back it.

Red Flags in Google Ads Manager Portfolios for B2B Buyers

Before the interview, the portfolio review narrows the field. These are the patterns that should raise immediate concern.

Only B2C or Ecommerce Case Studies in Their Portfolio

A portfolio composed entirely of ecommerce and direct-response B2C case studies is not automatically disqualifying, but it requires a pointed explanation from the candidate. Their results in those environments are real. The question is whether they understand that those environments produced their results through mechanisms that do not transfer to B2B.

If they cannot describe, unprompted, what they would need to change about their approach for B2B, they have not thought carefully about the difference. If they describe B2B paid search as fundamentally similar to ecommerce but “with longer cycles,” they have recognized the symptom without understanding the structural implications.

Reporting Built Entirely Around CPC and CTR with No Pipeline Attribution

A portfolio built on CPC improvements and CTR gains is a B2C reporting portfolio. These are legitimate performance indicators in environments where the click correlates tightly with downstream revenue. In B2B, a lower CPC often means you attracted cheaper but less qualified traffic. A higher CTR on a broad keyword can mean your ad copy is compelling to the wrong audience.

The absence of pipeline attribution in case study reporting tells you what the manager was asked to be accountable for in previous engagements. If no client ever required them to connect campaign performance to SQL volume or cost-per-opportunity, they have not built the muscle for that measurement. They will default to the reporting they know how to produce, which will not satisfy a CMO asking where pipeline is coming from.

No Mention of Negative Keyword Strategy or Search Term Auditing

Search term audits are the baseline quality control for any Google Ads account. Negative keyword lists are the output of that auditing, and in B2B they require ongoing weekly attention because match types in Google Ads continue to expand in ways that pull in unexpected query variants.

A manager who does not mention negative keyword development when describing their process has either never managed a B2B account where this distinction matters, or they are not operating at the level of detail that B2B paid search requires. Either conclusion is a reason to keep looking.

Key Takeaway: Portfolio red flags reveal the environment a Google Ads manager was built to serve. B2C-only case studies, reporting centered on CTR and CPC, and silence on negative keyword strategy are all signals that the candidate has not yet navigated the specific technical demands of B2B paid search. Spotting these patterns before the interview saves significant evaluation time.

In-House Google Ads Manager vs. Agency: Which Fits B2B Better

The decision between an in-house hire and a paid search agency for B2B is not primarily about cost. It is about feedback loop speed, context depth, and who owns the institutional knowledge about your buyers.

An in-house Google Ads manager builds deep product and buyer knowledge over time. They participate in sales calls. They hear which objections kill deals. They understand the nuance between a qualified lead and a form fill that looks qualified on paper. That context produces better keyword decisions, better ad copy, and better offer alignment. The disadvantage is that a single in-house manager carries the whole account, and their technical breadth is limited to what one person can master across platforms.

An agency brings a team with multi-platform depth and exposure to a broader range of B2B account structures. They have seen more failure modes and more optimization patterns than any single in-house hire. The risk is that account management gets distributed across multiple people with varying B2B experience levels, and strategic context about your buyers stays at the surface unless you invest heavily in onboarding and ongoing briefing.

For B2B companies spending under $30,000 per month in paid search, a specialized paid search agency typically delivers more technical depth than an in-house hire at equivalent cost. Above $100,000 per month, an in-house lead managing the strategy with agency support for execution often produces better results because the buyer context compounds internally over time.

What matters most is not the model but the B2B-specific expertise of whoever is making the campaign architecture decisions. A weak in-house hire and a B2C-trained agency both produce the same outcome: a well-reported account that does not feed pipeline. Whether you hire in-house or engage an agency, run the same evaluation framework and ask the same questions about attribution, intent stratification, and committee-level remarketing.

The complete PPC management guide covers the in-house versus agency decision in detail from a platform management perspective, including how to evaluate agency onboarding processes and what a properly structured audit looks like before any spend changes.

Key Takeaway: The in-house versus agency decision is secondary to the B2B expertise question. Both models can produce strong pipeline results and both can fail for the same structural reasons. Evaluate the individual or team doing the work against the same criteria regardless of engagement model.

How to Set Up Attribution Infrastructure Before Your Google Ads Manager Starts

Attribution infrastructure is not the Google Ads manager’s problem to solve after they take over the account. It is a prerequisite that the marketing operations function needs to build before paid search strategy can be evaluated against meaningful outcomes. Asking a Google Ads manager to improve pipeline performance inside a broken attribution environment is asking them to navigate without a map.

The minimum viable attribution stack for a B2B Google Ads program has four components.

The first is conversion tracking that goes beyond form fills. Every significant engagement event should be tracked: whitepaper downloads, demo requests, webinar registrations, pricing page visits above a time threshold, and any chatbot interactions that qualify as a sales conversation. Each event should be classified by its proximity to purchase intent and assigned different conversion values in Google Ads.

The second is CRM integration through offline conversion import. When a lead becomes an MQL and then an SQL in your CRM, those transitions should push back to Google Ads as conversion events tied to the original click through Google Click Identifier (GCLID) matching. This connects the bidding algorithms to the outcomes that actually matter, rather than letting them optimize toward form fills that may never reach the sales team.

The third is GA4 setup with proper B2B goal configuration. GA4 should track the same events as Google Ads and allow you to build audience segments based on behavioral signals: users who visited three or more solution pages, users who spent more than four minutes on the pricing page, users who visited from a target company domain. These audiences feed back into Google Ads for remarketing and Customer Match targeting.

The fourth is a conversion window setting that matches your actual sales cycle. Google Ads defaults to 30-day conversion windows. A B2B company with a 90-day average sales cycle is leaving months of attribution credit on the table. Setting a 90-day click-through window ensures that the algorithm receives credit for deals that take time to develop, and that your reporting reflects the full contribution of campaigns that introduced buyers early in their evaluation.

Teams at Skyram Technologies approach this infrastructure setup as the first milestone of any paid search engagement, before any campaign optimization work begins, because without clean attribution, every subsequent optimization decision is built on unreliable data.

Key Takeaway: Attribution infrastructure is a marketing operations responsibility, not a Google Ads manager deliverable. Set up offline conversion import, CRM integration, GA4 goal configuration, and appropriate conversion window settings before evaluating any paid search performance. Without this stack, you are measuring the wrong outcomes and making budget decisions based on data that does not connect to revenue.

What 90-Day Success Looks Like for a B2B Google Ads Engagement

The 90-day window for evaluating a new Google Ads manager or agency in a B2B context should not produce a clean pipeline verdict. It should produce a clean infrastructure verdict: is the technical foundation in place to generate meaningful data over the following six months?

In the first 30 days, a B2B-capable manager conducts a full account audit: conversion tracking integrity, negative keyword gaps, campaign structure mismatches between intent and bidding strategy, Quality Score distribution, audience configuration, and attribution window settings. They produce a prioritized fix list with estimated impact, not a generic scorecard. They implement the highest-priority technical fixes before making any significant bid or budget changes.

Between days 30 and 60, the manager executes structural changes: separating intent layers into distinct campaigns, building out negative keyword lists from search term report analysis, configuring micro-conversion events to give smart bidding early optimization signals, and setting up audience segments for remarketing that reflect the B2B evaluation cycle rather than standard 30-day retargeting windows.

Between days 60 and 90, the manager begins to see early data from the restructured campaigns and makes tactical adjustments. Micro-conversion rates by campaign and keyword cluster start to show which intent layers are generating real engagement versus wasted spend. The search term reports begin to confirm whether the negative keyword strategy is holding. Early offline conversion data from the CRM, if the integration is working, starts to show which campaigns are generating contacts that survive lead qualification.

At the 90-day mark, the right success metric is not SQL volume from paid, which is too early to judge in a long sales cycle. The right metric is whether the account is technically sound, whether the attribution infrastructure is producing data you can trust, and whether the manager can show you a clear hypothesis about which campaigns are building pipeline and why.

That conversation, grounded in data rather than platform metrics, is how you distinguish a B2B-capable Google Ads manager from one who is producing good-looking reports that do not connect to the outcomes you actually care about. If you also want to understand how paid search integrates with organic and AI-layer visibility, the SEO services overview and generative engine optimization resources clarify where each channel contributes across the B2B evaluation funnel.

Key Takeaway: Ninety days is enough time to evaluate the technical quality of a B2B Google Ads engagement, not enough time to evaluate pipeline contribution. Define 90-day success as a clean attribution infrastructure, a structurally sound account, and a data-backed hypothesis about campaign-to-pipeline connection. Hold pipeline evaluation to the 6-month mark, aligned with your actual sales cycle.

Frequently Asked Questions

  1. What should a Google Ads manager know about B2B marketing?

A Google Ads manager working in B2B should understand how buying cycles affect campaign architecture, attribution, and bid strategy in ways that do not apply to B2C accounts. Specifically, they should know how to structure campaigns around separate intent layers (awareness, consideration, and decision), how to use offline conversion import to connect CRM pipeline events back to Google Ads bidding algorithms, how to build negative keyword lists that protect high-intent campaigns from research-stage query bleed, and how to set conversion windows that reflect a 90-day or longer sales cycle rather than defaulting to 30 days. A B2B Google Ads manager should also understand that the primary success metric is cost-per-SQL or cost-per-opportunity, not cost-per-click or cost-per-form-fill, and that their reporting should speak the language of pipeline contribution rather than ad platform metrics.

  1. How is B2B Google Ads management different from B2C Google Ads management?

B2B Google Ads management differs from B2C management in three foundational ways. First, the buying timeline: B2C purchases often complete within hours of a click, while B2B purchases take 6 to 12 months and require campaigns that serve buyers at different readiness levels simultaneously. Second, the audience structure: B2C targets individuals based on demographics and interest signals, while B2B must account for buying committees of 6 to 10 people at the same company, each researching independently. Third, the measurement framework: B2C optimizes toward transactions tracked in real time, while B2B requires multi-touch attribution, offline conversion import from the CRM, and conversion windows that match the length of the actual sales cycle. A manager trained exclusively in B2C will apply fast-cycle optimization logic to a slow-cycle environment and optimize toward metrics that do not predict revenue.

  1. How do I evaluate a Google Ads agency for B2B lead generation?

When evaluating a Google Ads agency for B2B lead generation, look for four signals. First, case studies from B2B accounts with reporting that shows cost-per-SQL or cost-per-opportunity, not just CTR and CPC. Second, a clear description of how they set up offline conversion import to connect Google Ads performance to CRM pipeline data. Third, a process for intent stratification: how they structure different campaigns for different stages of a B2B buying cycle rather than running all traffic through one campaign type. Fourth, a remarketing strategy that accounts for buying committees rather than individual users. Agencies that cannot describe these four elements in concrete operational terms are applying B2C expertise to a B2B brief.

  1. What is offline conversion import in Google Ads and why does it matter for B2B?

Offline conversion import in Google Ads is a process that connects CRM pipeline events, such as a lead becoming an SQL or an opportunity being created, back to the original ad click that generated that contact. It works by capturing a Google Click Identifier (GCLID) from the initial ad click, storing it in the CRM, and then uploading that GCLID with the downstream conversion event when it occurs. For B2B, this matters because the most valuable conversion events happen weeks or months after the initial ad click, well outside the window that Google Ads can observe through standard pixel tracking. Without offline conversion import, Google Ads bidding algorithms optimize toward form fills, and lead quality suffers because the algorithm has no signal about which form fills actually become qualified pipeline.

  1. How long does it take to see results from a B2B Google Ads campaign?

B2B Google Ads campaigns typically require 60 to 90 days to establish a clean technical foundation and begin generating reliable early signals, and 4 to 6 months before meaningful pipeline attribution data is available for evaluation. The first 30 days should focus on account structure, tracking integrity, and negative keyword development. The next 60 days generate micro-conversion data that indicates which intent layers are producing qualified engagement. Pipeline data becomes statistically meaningful only after enough leads have had time to progress through the full qualification cycle. Organizations that evaluate B2B Google Ads performance at 30 or 60 days and make budget decisions based on that data are measuring before the feedback loop has closed, which leads to premature campaign cuts and missed pipeline contribution.

Work with Google Ads Managers Who Think in Pipeline, Not Platform Metrics

The difference between a Google Ads manager who understands B2B and one who does not is not visible in their certifications or their general performance numbers. It surfaces in how they structure campaigns, how they measure success, and whether they can connect ad spend to pipeline in an environment where the path from click to closed deal takes six months.

Skyram Technologies builds B2B Google Ads programs around proper attribution infrastructure, intent-stratified campaign architecture, and reporting that CMOs and VPs of Sales can both read without translation. If your current paid search program generates traffic without feeding pipeline, the problem is structural and addressable.

Schedule a strategy session to discuss what a pipeline-first Google Ads engagement looks like for your B2B demand generation program.

Hiring a PPC Agency for B2B Lead Generation: What Actually Drives Pipeline

Hiring a PPC Agency for B2B Lead Generation

Hiring a PPC agency for B2B lead generation requires evaluating their understanding of long buying cycles, multi-touch attribution, and the difference between form fills and qualified pipeline. B2B PPC performance measured on click-through rate and cost-per-click tells you almost nothing about revenue impact. Agencies that drive B2B pipeline optimize for SQLs and pipeline velocity, not impressions and traffic volume.

Here is the scenario that plays out across B2B marketing teams more often than anyone wants to admit. The demand gen lead brings in a PPC agency for B2B campaigns. Month one report lands: CTR is up 38 percent. Cost-per-click dropped by 22 percent. The agency is thrilled. The sales team, however, is not booking more discovery calls. SQLs are flat. The CRM is filling up with forms from companies that are nowhere near the ICP, from titles that have no budget authority, and from people who downloaded a whitepaper with no intent to ever buy.

The agency optimized the metrics they knew how to move. Not the ones that mattered.

This post is the evaluation guide that demand gen leaders and marketing directors need before they sign an agency contract. It covers what B2B PPC architecture actually looks like, the five questions that reveal whether an agency genuinely understands B2B buying behavior, how to structure accountability around revenue outcomes, and when to combine paid search with organic strategy for full-funnel coverage.

Why Most PPC Agencies Are Optimized for the Wrong B2B Metrics

The core problem with most PPC agencies evaluating themselves against B2B KPIs is that they were trained on B2C performance signals. Retail and ecommerce campaigns produce purchase events within hours of a click. The feedback loop is tight, the signal is clear, and optimization toward conversions works because “conversion” actually maps to revenue.

B2B is structurally different. A qualified B2B buyer might click a LinkedIn ad in January, visit the site twice more in February via organic search, attend a webinar in March, and finally request a demo in April after a colleague forwards a case study. That ad click in January contributed to a closed deal. A CTR-optimized campaign would never surface that relationship.

CTR and CPC as Vanity Metrics in Long-Cycle B2B Buying

Click-through rate measures how many people clicked your ad. It tells you nothing about whether those people had the budget, authority, or need to purchase. In B2B with average sales cycles of 3 to 12 months, a high CTR from poorly qualified audiences accelerates your cost-per-SQL, burns your sales team’s time, and produces pipeline reports that look fine until leadership asks why revenue is not following.

Cost-per-click is even less informative. A lower CPC often means you shifted bidding toward broader match terms or lower-competition placements that attract researchers and students rather than decision-makers. An agency celebrating CPC reduction while your sales team flags lead quality problems has misaligned priorities.

The agencies that understand B2B measure cost-per-SQL, cost-per-opportunity, and pipeline contribution by channel. Those are the metrics that connect paid campaigns to revenue. If an agency’s standard reporting deck does not include those columns, that tells you everything about how they will manage your account.

Form Fills vs. SQLs: Where the Conversion Gap Actually Lives

Every agency will optimize toward your conversion events. The question is whether your conversion events are the right ones. Most B2B teams set form submissions as their primary conversion, then wonder why their cost-per-lead looks manageable while qualified pipeline growth is stagnant.

The conversion gap lives between the form fill and the SQL. A prospect fills out a gated whitepaper download. That registers as a conversion. That person has no buying intent today. They are in research mode. Six months from now, maybe three percent of that cohort becomes an SQL. An agency optimizing toward form fills has just built a system that efficiently delivers people who are nowhere near a buying decision.

Solving this requires connecting your CRM data back to campaign performance through offline conversion imports. When a lead becomes an SQL, that event gets pushed back into Google Ads or LinkedIn as a conversion signal. Now your bidding algorithms are optimizing toward the behavior that actually precedes revenue, not the behavior that precedes inbox noise.

How Agency Reporting Obscures Pipeline Contribution

Standard agency reporting packs in the metrics that look like progress: impressions served, clicks generated, CTR improved, quality score increased. These are real signals that good things are happening in the account. They are not evidence that pipeline is growing.

Pipeline contribution requires a different data layer. You need to know which campaigns and keywords are generating contacts that eventually became opportunities, what the average time lag is between first paid touch and opportunity creation, and what your cost-per-opportunity looks like by campaign type, by offer, and by channel.

Most agencies cannot produce that reporting because they do not have CRM access and they have not set up the offline conversion tracking infrastructure that makes it possible. Insisting on this data architecture before signing is one of the most important steps a demand gen leader can take.

Key Takeaway: B2B PPC performance measured on CTR and CPC tells you almost nothing about revenue impact. Insist on reporting that connects campaign spend to SQL volume, cost-per-opportunity, and pipeline contribution before you evaluate whether an agency is actually performing.

What B2B PPC Campaign Architecture Actually Looks Like

A B2B demand gen PPC program is not a single campaign targeting people who search for your product. It is a layered system designed to reach buyers at different stages of awareness and move them through a buying process that happens over months, not days.

Intent-Layer Targeting: In-Market vs. Awareness vs. Retargeting

A properly architected B2B paid program runs three distinct intent layers simultaneously, each with its own offer, landing page, and measurement approach.

The bottom layer targets in-market buyers who know they have a problem and are actively evaluating solutions. These are high-intent keyword campaigns around terms like “B2B lead generation software” or “demand gen agency” with conversion objectives tied to demo requests or consultation bookings. Cost-per-click is highest here, conversion rates are highest, and sales cycle from this entry point is shortest.

The middle layer targets buyers who are aware of the category but not yet actively shopping. LinkedIn Sponsored Content with educational resources, thought leadership, or comparison content performs well here. The goal is not an immediate demo request. The goal is a documented touch that keeps your brand in the consideration set when the evaluation period begins.

The top layer runs retargeting against people who have already engaged with your content, visited key pages, or opened prior emails. These audiences convert at 3 to 5 times the rate of cold traffic because you are serving ads to people who already know who you are. A B2B agency that is not running structured retargeting is leaving the highest-efficiency segment of your funnel unmeasured.

Account-Based Targeting and How It Differs from B2C Audience Construction

B2C audience construction focuses on demographic and behavioral signals: age, interests, purchase history, lookalike models built from past customers. B2B account-based targeting starts from a different place entirely. You define the companies you want to reach first, then build targeting that serves ads to the people within those companies who participate in the buying decision.

LinkedIn’s company targeting combined with job title and seniority filters is the most precise tool available for this. You can serve ads exclusively to VPs of Marketing and Directors of Demand Generation at SaaS companies with 200 to 2,000 employees that are located in the US. That specificity means higher CPCs, but it also means every impression has a realistic chance of reaching someone in your actual ICP.

Google Ads Customer Match and account lists let you upload company domains and match them against signed-in users, then layer those company signals on top of keyword intent. It is less precise than LinkedIn but dramatically cheaper per impression, and effective for the bottom-of-funnel layer where someone from a target account is actively searching for your category.

Landing Page and Offer Design for B2B Buying Committees, Not Individual Buyers

B2B purchases involve an average of 6 to 10 stakeholders depending on deal size and industry. A landing page designed to convert a single motivated individual fails in this environment because no single person makes the decision. Your paid traffic lands on a page, and within 60 seconds that person is asking: can I forward this to my team? Does this pass the internal credibility test? Does this contain the proof that will hold up in a business case presentation?

Your offer architecture needs to account for that social proof requirement. Case studies with named companies and specific ROI figures convert better than generic outcome statements. ROI calculators that produce shareable outputs give individual champions something to put in front of a CFO. Audit offers and benchmark reports are easy to justify internally because they produce information, not an immediate sales engagement.

An agency that sends your LinkedIn traffic to a generic contact form is not thinking about the committee dynamics that govern B2B buying. That mismatch between ad targeting precision and landing page design is where a significant portion of your budget disappears.

B2C-Optimized vs. B2B Pipeline-Focused PPC Agency: Side-by-Side

B2C-Optimized PPC Agency B2B Pipeline-Focused PPC Agency
Campaign Structure Single-funnel, conversion-focused Intent-layered: awareness, retargeting, in-market
Audience Construction Demographic and interest-based Company, title, seniority, buying committee
Primary KPIs CTR, CPC, cost-per-lead Cost-per-SQL, cost-per-opportunity, pipeline velocity
Measurement Framework Last-click attribution Multi-touch, offline conversion import, CRM integration
Reporting Cadence Monthly PDF with platform metrics Weekly tactical, monthly pipeline review, quarterly strategy
Offer Strategy Single CTA (buy, sign up, trial) Staged offers by intent level (resource, audit, demo, call)
Sales Alignment None required Required for lead scoring, qualification handoff, feedback loop
Landing Page Approach Individual conversion optimization Committee-ready: social proof, shareable assets, credibility signals

Key Takeaway: B2B PPC architecture is fundamentally different from B2C. A pipeline-focused agency builds layered campaigns that match offer to intent, targets buying committees rather than individuals, and measures outputs that actually connect to revenue, not just activity.

The Five Questions That Reveal Whether a PPC Agency Understands B2B

These are not gotcha questions. They are the baseline competency checks that separate agencies that have genuinely managed B2B pipeline programs from agencies that have read about them.

1. How Do You Attribute Pipeline to Paid Campaigns Across a 90-Day Sales Cycle?

This question forces the agency to explain their attribution infrastructure. A strong answer describes their offline conversion import process: how CRM data is connected to ad platforms so that MQL-to-SQL progressions feed back into bidding optimization. It describes their position on multi-touch attribution and which model they use for evaluating channel contribution over a long cycle.

A weak answer talks about last-click attribution or mentions “closed loop reporting” without explaining how the loop actually closes. If an agency cannot describe the technical process by which a deal closed in your CRM connects back to the keyword and campaign that first brought that buyer into your funnel, they are reporting on ad activity, not pipeline contribution.

2. How Do You Approach Targeting a Buying Committee vs. a Single Decision-Maker?

This question surfaces whether the agency thinks about B2B audience construction at all. A strong answer discusses persona segmentation within the same target accounts, separate creative tracks for technical evaluators versus financial approvers, and offer architecture designed for different stakeholder concerns within the same deal.

A weak answer describes job title targeting as if serving one ad to one person completes the committee engagement problem. B2B agencies who have worked real enterprise deals understand that the VP of Marketing who sees your ad is not the person who signs the check or configures the tool. Each of those people needs to encounter your brand and your proof points at some point in the evaluation window.

3. What Is Your Strategy When a Campaign Drives Traffic but Sales Says the Leads Are Not Qualified?

This question tests the agency’s ability to diagnose a structural problem rather than defend their metrics. A strong answer proposes a multi-step investigation: reviewing the search terms triggering ads, auditing the audience signals on LinkedIn, analyzing the company profile of form fills versus actual SQLs, adjusting the offer to attract higher-intent prospects, and installing a lead scoring layer that gates MQL-to-SQL handoff.

A weak answer suggests running more volume to improve conversion rate. If an agency responds to lead quality problems by recommending more spend, they are not aligned with your pipeline outcomes. They are aligned with their management fee tied to budget.

4. What Offer Architecture Do You Recommend for Our Funnel Stage?

A B2B-experienced agency thinks about this in terms of where the buyer is in their awareness journey. They will ask about average deal size, sales cycle length, and how your sales team prefers to initiate discovery. Then they will recommend offers that match: awareness-stage content for cold audiences, audit and benchmark offers for middle-funnel intent, demo requests and consultation bookings for in-market buyers.

An agency that immediately recommends a demo request CTA for all traffic regardless of audience temperature has not thought seriously about B2B buyer behavior.

5. How Do You Handle Campaign Optimization When Conversion Data Is Sparse?

B2B campaigns often struggle with low conversion volume in early months because the pipeline cycle is long and SQLs accumulate slowly. A skilled agency knows how to use micro-conversion events (whitepaper downloads, video completions, time-on-page thresholds) as early optimization signals while the higher-quality conversion data develops. They know how to structure campaign types and bidding strategies to perform in low-volume environments rather than requiring 50 conversions per campaign per month before smart bidding is stable.

Key Takeaway: These five questions identify whether a prospective PPC agency has genuinely managed B2B pipeline programs or has managed B2C campaigns and applied surface-level B2B vocabulary to the same playbook. The answers reveal attribution infrastructure, committee thinking, diagnostic discipline, and technical competency simultaneously.

Campaign Types That Drive B2B Pipeline vs. Those That Just Drive Traffic

Not all paid campaign types are equal contributors to pipeline in a B2B context. Here is how the major campaign types break down by their actual pipeline value:

Google Search: In-Market Demand Capture. When B2B buyers are actively evaluating vendors in your category, Google Search captures that intent precisely. Terms with commercial intent (“B2B demand gen agency,” “LinkedIn ads for SaaS,” “PPC agency for software companies”) produce direct pipeline at the bottom of the funnel. This is the highest-efficiency campaign type for pipeline-per-dollar in mature accounts.

LinkedIn Sponsored Content: Upper-Funnel Awareness. LinkedIn reaches buying committees by company, title, and seniority with content-first formats. Thought leadership content, benchmark reports, and educational assets perform here. Conversion rates are low but audience precision is high, and the people who engage are inside your actual ICP.

LinkedIn Lead Gen Forms: Middle-Funnel Offer. Pre-filled forms that capture contact data from LinkedIn profiles reduce friction for resource downloads and webinar registrations. These produce MQLs at reasonable volume, but require strong lead scoring to prevent the pipeline-fill problem described earlier.

Google Display and YouTube: Brand Reinforcement. These formats keep your brand in the consideration set for buyers who have already shown some intent. They function best as retargeting vehicles rather than cold prospecting tools for B2B. Measuring them on direct conversion metrics misunderstands their role in a multi-touch cycle.

Competitor and Alternative Conquesting. Search campaigns targeting competitor brand terms and “alternative to X” keyword clusters capture buyers who are actively evaluating your direct competition. These campaigns deliver some of the most qualified traffic available because the person has already made the decision to invest. They are often underutilized in B2B paid programs.

Branded Keyword Defense. Running branded keyword campaigns protects your organic SERP real estate from competitors who bid on your name and ensures that high-intent buyers searching for you directly land on your page, not a competitor comparison site. This is table stakes, not optional.

Key Takeaway: In B2B, campaign type selection is as strategic as keyword selection. Google Search captures in-market demand. LinkedIn reaches the committee. Retargeting closes the loop on in-funnel engagement. Agencies that treat all campaign types with the same conversion objective are misapplying the tools they have.

How to Structure Agency Accountability Around Revenue Outcomes

Hiring a PPC agency without structuring accountability correctly is how you end up in the scenario described at the start of this post: great metrics, no pipeline. Accountability structures need to be built into the engagement from day one, not bolted on after frustration accumulates.

OKRs and Reporting Frameworks Tied to SQL Volume, Not Vanity Metrics

The engagement objectives need to be written in the language of pipeline. That means the primary success metric is SQL volume from paid channels, secondary metrics are cost-per-SQL and cost-per-opportunity, and tactical metrics like CTR and CPC are treated as diagnostic indicators rather than proof of performance.

A monthly reporting cadence should include: pipeline generated from paid by campaign type, lead quality score from sales team feedback (on a defined scale), MQL-to-SQL conversion rate from paid channels versus organic versus direct, and cost-per-opportunity by campaign. If those four data points are not in the report, the report is not connected to your business outcomes.

You also need a defined lead scoring framework agreed upon with sales before the first campaign launches. Without shared definitions of MQL and SQL, every conversation about lead quality becomes subjective and adversarial. A lead scoring matrix that uses firmographic, behavioral, and engagement signals to automate the handoff removes that friction.

Milestone-Based Retainer Structure That Aligns Incentives

Standard monthly retainers pay the same fee regardless of whether the account improved or declined. A milestone-based structure ties a portion of the retainer to specific pipeline metrics achieved within defined windows.

A practical structure: a base retainer covers account management and reporting. A performance component activates when SQL volume from paid channels hits defined monthly thresholds. Milestones reset quarterly so the agency is not penalized for market seasonality, but they are rewarded for sustained pipeline contribution.

This structure does not work if attribution is not clean. The agency needs to have visibility into CRM data and the technical infrastructure to connect campaign performance to downstream revenue events. Setting up that infrastructure is a prerequisite to making performance incentives meaningful.

Agencies willing to engage with a milestone-based structure are making an implicit statement about their confidence in their process. Agencies that resist it entirely and insist on flat retainers regardless of outcomes are telling you something about their relationship with accountability.

Key Takeaway: Accountability structures need to be built into the agency contract before work begins. Define success in the language of pipeline, agree on lead scoring with sales, and structure retainers to create shared incentives around SQL volume and cost-per-opportunity.

When to Combine SEO and PPC for Full-Funnel B2B Coverage

Paid search and organic search solve different problems in a B2B marketing program. Running them in isolation produces two underperforming channels. Running them as integrated strategy produces a compounding system where each channel makes the other more effective.

The most immediate integration value comes from keyword intelligence sharing. PPC campaigns generate conversion data on specific search terms within weeks. You learn which queries convert at the highest rate with the lowest cost before committing to the months-long content investment that organic ranking requires. That PPC keyword data becomes the prioritization input for your B2B SEO strategy, compressing the research phase significantly.

The second integration value is coordinated SERP coverage. For high-commercial-intent queries where your target buyers are actively searching, owning both the paid position and an organic position on the same page significantly increases click probability. Research consistently shows that brands appearing in both positions increase total SERP traffic share by 15 to 25 percent compared to organic or paid alone. The cannibalization concern that leads some teams to suppress paid when they rank organically is mostly unsupported when you measure actual contribution.

The third integration dynamic is content performance feedback. Paid campaigns can test messaging, offers, and angles against real traffic in 30 days. High-performing paid ad copy is validated proof that the same angle will resonate in organic content. You are not guessing which blog post headline will get clicked. You have conversion data from split-tested ad copy that already told you the answer.

For B2B programs that want visibility across Google, AI platforms, and voice search in addition to traditional paid channels, answer engine optimization and generative engine optimization round out the full-funnel picture. When a senior buyer asks Perplexity or ChatGPT which demand gen agency to evaluate, organic and AI-layer visibility determines whether your brand is in that initial consideration set before any paid search even enters the picture.

Teams at Skyram Technologies approach this integration as a data-sharing architecture problem, not just a channel coordination question. When paid keyword data, organic ranking data, AI citation tracking, and CRM pipeline data feed into a shared reporting environment, the marketing team and the sales team can see the same pipeline picture with the same attribution logic applied across all channels. That alignment is what separates demand gen programs that compound over time from programs that require constant justification.

Reviewing the complete PPC management guide gives additional context on how platform-level management strategy connects to the B2B pipeline objectives described throughout this post.

Key Takeaway: Integrating SEO and PPC in a B2B program produces more than the sum of the parts. PPC keyword data accelerates organic content prioritization. Coordinated SERP coverage increases total click share. Content performance data from paid ad testing removes guesswork from organic content strategy. A full-funnel program also layers in AEO and GEO to cover the AI platform channels where B2B evaluation increasingly begins.

Frequently Asked Questions

  1. What should I look for when hiring a PPC agency for B2B lead generation?

When hiring a PPC agency for B2B lead generation, the most important factors to evaluate are: their ability to set up offline conversion tracking that connects CRM pipeline data back to campaign performance, their experience with account-based targeting on LinkedIn and Google, their approach to offer architecture for multi-stakeholder buying committees, and whether their standard reporting includes cost-per-SQL and cost-per-opportunity rather than only CTR and CPC. Agencies that understand B2B structure campaigns around intent layers, not a single conversion objective, and they align optimization with sales-qualified pipeline outcomes rather than form fill volume.

  1. How is B2B PPC different from B2C PPC?

B2B PPC differs from B2C PPC in three fundamental ways: the buying timeline, the buying committee, and the measurement framework. B2C purchases often complete within hours of a click. B2B purchases involve 3 to 12 month cycles with 6 to 10 stakeholders. B2C PPC optimizes toward immediate transactions. B2B PPC must optimize toward early-funnel signals, multi-touch attribution, and downstream SQL events that may occur months after the first paid impression. B2C audience construction uses demographics and interests. B2B audience construction uses company, job title, seniority, and intent signals to reach specific members of a buying committee at named accounts.

  1. How long does B2B PPC take to show pipeline results?

B2B PPC typically takes 60 to 90 days before meaningful pipeline data is available for evaluation. The first 30 days establish tracking infrastructure, build out negative keyword lists, and accumulate enough conversion data for smart bidding algorithms to begin optimizing. SQL volume from paid campaigns usually becomes measurable in month 2 or 3, depending on the length of the sales cycle and how quickly MQLs progress through the qualification process. Teams that evaluate B2B PPC performance at 30 days and draw conclusions about channel viability are measuring before the feedback loop has had time to close.

  1. What PPC channels work best for B2B lead generation?

The most effective PPC channels for B2B lead generation are Google Search for in-market demand capture, LinkedIn Sponsored Content for buying committee awareness, and LinkedIn Lead Gen Forms for mid-funnel offer delivery. Google Search targets active buyers searching for solutions in your category. LinkedIn reaches specific job titles at specific companies with content-first formats that build trust before requesting a sales engagement. Retargeting across both platforms captures buyers who have already engaged with your content and converts at 3 to 5 times the rate of cold traffic. The right channel mix depends on deal size, sales cycle length, and the maturity of your brand within the target market.

  1. How do I measure ROI from a B2B PPC agency?

ROI from a B2B PPC agency is measured by tracking four connected metrics: SQL volume from paid channels month over month, cost-per-SQL by campaign type and offer, cost-per-opportunity for deals that entered the pipeline from a paid touchpoint, and pipeline-to-close rate from paid-sourced opportunities compared to other channels. These metrics require CRM integration and offline conversion import infrastructure to be accurate. Agencies that can only report on ad platform data (CTR, CPC, form fills) cannot provide ROI measurement in the B2B sense because they are missing the CRM layer where the actual revenue events are recorded.

Work with a Team That Optimizes for Pipeline, Not Impressions

If your current PPC program is generating clicks but your sales team cannot trace those clicks to closed deals, the problem is usually architectural. The campaign structure, the offer, the attribution layer, or the agency incentives are misaligned with the pipeline outcomes that your business actually needs.

Skyram Technologies builds B2B paid programs that connect ad spend to sales-qualified pipeline through proper attribution infrastructure, intent-layered campaign architecture, and reporting frameworks that your sales team and your CFO can both read.

Schedule a strategy conversation to discuss what a pipeline-first PPC engagement looks like for your demand gen program.