You are managing a SaaS platform that launched with three microservices. Now you have thirty. Deployments take longer, on-call rotations are getting painful, and the person who configured your cluster has moved on to another company. You need Kubernetes to actually work, and you need a decision on how to own it.
Two real options sit in front of you: bring in a dedicated Kubernetes engineer, or hand the operational layer to a managed Kubernetes provider. Both solve different versions of the same problem. Neither is wrong by default. But one of them is wrong for your current stage, your cluster complexity, and the bandwidth your team actually has.
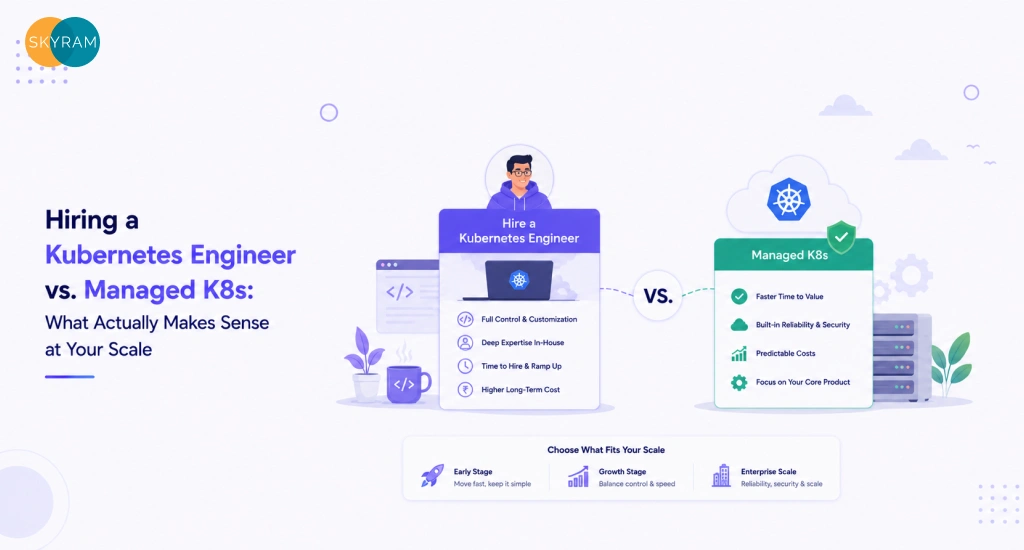
At mid-market SaaS scale, the decision between hiring a Kubernetes engineer and adopting a managed Kubernetes service depends on cluster complexity, internal platform maturity, and whether your team has the bandwidth to own operational overhead. Managed K8s removes node lifecycle management and control plane responsibility. A dedicated hire adds customization depth but concentrates risk in a single role.
This guide walks through what each path actually looks like in practice, what the scale thresholds are, where the hidden costs live, and what a third option looks like for teams that need operational coverage without full-time headcount.
What a Kubernetes Engineer Actually Owns Day-to-Day
Before you write a job description, understand what you are actually hiring for. The title “Kubernetes engineer” covers a wide spectrum of work, and most job postings conflate at least three distinct functions.
Cluster Provisioning, Node Management, and Upgrade Cycles
A Kubernetes engineer owns the infrastructure layer underneath your workloads. That means provisioning cluster nodes, managing node pools, handling resource requests and limits across namespaces, and planning upgrade cycles across minor and major K8s versions.
Upgrades alone are a significant time investment. Each Kubernetes minor version has roughly a 14-month support window. Moving a production cluster through version upgrades without service disruption requires careful sequencing: node draining, pod disruption budgets, compatibility checks against your ingress controllers, CNI plugins, and admission webhooks. A qualified engineer owns that entire process, including rollback planning.
Node management also includes autoscaling decisions. Cluster Autoscaler behavior, node pool configurations, spot and preemptible instance strategies for cost efficiency, and taint and toleration setups for workload isolation all sit in this person’s purview. This is detailed, environment-specific work. It does not delegate well to a generalist DevOps engineer who also owns your CI/CD pipeline automation and monitoring stack simultaneously.
Key Takeaway: Cluster provisioning and upgrade management alone are a recurring time sink that requires dedicated focus. Treating this work as a side task for a generalist engineer compounds operational debt quickly.
Networking, RBAC, and Namespace Governance
Kubernetes networking is where mid-market SaaS teams most often hit invisible walls. Service mesh decisions, Ingress controller configuration, network policy enforcement between namespaces, and DNS resolution behavior within the cluster are all non-trivial. A misconfigured NetworkPolicy can silently block inter-service traffic. An Ingress controller version mismatch can break TLS termination.
RBAC governance scales with your team. As you add engineers, you need service account scoping, role bindings per environment, and a strategy for keeping least-privilege access intact as your namespace count grows. Without someone owning this layer, access sprawl accumulates. You end up with overly permissive service accounts running production workloads, which creates both security risk and compliance exposure.
Namespace governance also matters for cost attribution. Which team owns which namespace? How are resource quotas enforced? How do you prevent one team’s batch jobs from crowding out another team’s real-time services? These are governance problems that a Kubernetes engineer should own structurally, not reactively.
Key Takeaway: RBAC and namespace governance are not one-time setup tasks. They require ongoing ownership as your team and service count grows. Without dedicated oversight, both security posture and cost visibility erode.
Incident Response and Capacity Planning
When a pod is stuck in CrashLoopBackOff at 2 AM and your on-call engineer does not know whether the cause is an OOM kill, a failed liveness probe, or a broken ConfigMap reference, you have a skills gap that managed K8s cannot fully paper over either. A dedicated Kubernetes engineer brings pattern recognition that reduces your mean time to resolution significantly.
Capacity planning is a longer game. Sizing node pools for peak traffic, setting Horizontal Pod Autoscaler thresholds that respond to actual demand signals rather than CPU defaults, and planning for cluster-level resource headroom during product launches all require someone who understands your traffic patterns and workload characteristics deeply. This is not a task you can outsource to a cloud provider’s default autoscaling configuration.
Key Takeaway: Incident response depth and capacity planning accuracy both improve meaningfully with a dedicated Kubernetes engineer. The question is whether your current scale justifies that investment.
What Managed Kubernetes Actually Includes (and What It Doesn’t)
Managed Kubernetes platforms are frequently misunderstood. Teams either over-rely on them or underestimate the residual work they still carry internally. Getting this right matters for your budget planning and your staffing model.
What EKS, GKE, and AKS Manage for You
All three major managed K8s platforms, Amazon EKS, Google GKE, and Microsoft AKS, handle the control plane for you. That means etcd management, API server availability, control plane upgrades, and the underlying infrastructure that K8s uses to schedule and coordinate workloads. You do not provision or patch the control plane. You do not worry about control plane failover. That operational layer disappears.
Node group management is also partially abstracted. EKS Managed Node Groups, GKE Autopilot, and AKS Node Pools give you tools to define node configurations and let the platform handle provisioning and replacement. GKE Autopilot goes furthest, abstracting node-level management almost entirely. You declare workloads and the platform figures out where to run them.
Automated upgrade paths exist on all three platforms, though they require configuration and testing before adoption. You still need someone who understands the upgrade implications for your specific workload stack. The platform does not know your custom admission webhooks or the KEDA version you pinned last quarter.
Where You Still Need Internal Expertise Regardless of the Model
Here is what managed K8s does not eliminate. You still own application-level configuration: Helm charts, resource requests and limits, liveness and readiness probes, pod disruption budgets. You still own networking decisions at the application layer: which services get an internal LoadBalancer versus a ClusterIP, how your Ingress controller handles routing, whether you need a service mesh and at what fidelity.
Security hardening is not handled for you. Pod security admission, image scanning, secrets management integration, and workload identity configuration are all your responsibility. RBAC still needs ownership. Namespace governance still needs ownership.
Observability is also not included. You need to wire up your logging stack, configure Prometheus and Grafana or a managed alternative, and define alerting rules that reflect your SLOs. None of that comes preconfigured. Pairing your managed platform with a structured cloud engineering foundation, covering networking architecture, security layers, and cost governance, is what turns a provisioned K8s cluster into a production-reliable environment.
Managed K8s is not a staffing substitute. It is a scope reducer. You trade operational depth for operational breadth. The right question is not whether to use managed K8s. It is whether the scope it removes justifies the cost, and whether your team has enough internal K8s literacy to handle what remains.
Comparison Table: Kubernetes Engineer Hire vs. Managed K8s
| Dimension | Dedicated K8s Engineer | Managed Kubernetes (EKS/GKE/AKS) |
| Control plane ownership | Full internal ownership | Offloaded to cloud provider |
| Node lifecycle management | Engineer-owned, fully customizable | Platform-managed with some configuration |
| Upgrade responsibility | Manual, engineer-planned | Platform-assisted, requires validation |
| RBAC and namespace governance | Deep, engineer-driven | Requires internal ownership regardless |
| Observability setup | Fully custom | Requires internal configuration |
| Cost structure | Salary plus benefits plus tooling | Platform fees plus reduced headcount |
| Scale ceiling | Very high, limited by single-person risk | High, but custom configurations have limits |
| Risk profile | Key-person dependency | Vendor dependency plus residual skill gap |
| Speed to operational coverage | 90-plus day hire cycle | Days to weeks for initial configuration |
| Customization depth | Maximum | Limited by what the provider supports |
The Scale Thresholds That Make Each Option the Right Call
The honest answer to the “K8s engineer or managed K8s” question is almost always “it depends on how many services you are running and how much operational risk you can absorb.” But that abstraction is not useful on its own. Here are the thresholds that actually matter.
Under 10 Services: Managed K8s Almost Always Wins
At fewer than ten microservices, your cluster is not complex enough to justify a full-time Kubernetes hire. You have limited namespace complexity, predictable traffic patterns, and workloads that managed platforms handle without custom intervention. The overhead of recruiting, onboarding, and retaining a senior K8s engineer at market rate does not pencil out against the operational scope you actually have.
EKS Fargate, GKE Autopilot, or AKS with managed node pools give you a solid operational foundation without headcount investment. Your existing DevOps generalists can handle the application-layer configuration with reasonable ramp-up. The AWS Cloud services layer, for teams running on Amazon infrastructure, already provides the managed EKS control plane plus native integrations for logging, IAM, and node group scaling that remove the majority of operational overhead at this stage.
At this scale, your engineering energy belongs in product velocity, not platform operations.
10 to 50 Services: The Hybrid Model
Between ten and fifty microservices, you hit the zone where managed K8s alone starts showing friction. Your namespace count is growing. Multiple teams own different services. RBAC complexity increases. Your traffic patterns diverge enough that generic autoscaling defaults leave money on the table or leave headroom too tight.
This is where a hybrid model earns its keep. You stay on a managed K8s platform, because you do not yet need the deep customization that self-managed clusters unlock, but you invest in either a platform engineer or an external Kubernetes solutions partner who owns the operational layer on top of what the platform provides. That means owning your Helm chart standards, your RBAC model, your observability stack, and your upgrade validation process.
The hybrid model gives you the cost reduction of managed infrastructure plus the operational depth that your service count now demands. It is the right default for most mid-market SaaS companies in the 50 to 250 engineer headcount range.
50 Plus Services: Where a Dedicated K8s Hire or Specialist Team Earns Its Keep
Above fifty services, cluster complexity compounds. You likely have multiple namespaces with different security profiles, teams deploying independently, custom admission controllers to enforce policies, and performance-sensitive workloads that require fine-grained resource tuning. Generic managed K8s configurations start creating friction.
At this scale, a dedicated Kubernetes engineer or a small platform engineering team makes economic sense. The customization depth they unlock, tighter resource efficiency, custom networking configurations, multi-cluster management strategies, reduces infrastructure cost in ways that outpace their compensation over time. You also gain institutional knowledge about your specific cluster topology that an external provider cannot accumulate as fast.
The risk at this scale is still key-person dependency if you hire one person. A team of two or three is meaningfully more resilient than a single engineer who owns everything.
Key Takeaway: Scale thresholds are not arbitrary. The complexity your K8s environment carries determines which staffing model actually pays for itself. Most mid-market SaaS teams land in the hybrid zone, where neither a full hire nor pure managed K8s is the right single answer.
The Hidden Costs of Getting This Decision Wrong
Both paths carry costs that do not show up in the original budget comparison.
If you hire a Kubernetes engineer before your cluster is complex enough to need one, you pay full-time market rate for an underutilized skill set. Senior K8s engineers in the US command competitive salaries with full benefits packages, and a bored specialist in a low-complexity environment is a flight risk within twelve months.
If you skip the hire and stay on managed K8s past the point where your complexity demands more, you pay in operational incidents, developer productivity loss, and accumulated technical debt in your cluster configuration. Your application engineers start working around platform limitations. Your on-call rotations get harder. Incidents that a competent K8s engineer would resolve in thirty minutes stretch into hours because no one on your team has the depth.
There is also a timing cost on the hiring path that most VPs underestimate. Senior Kubernetes engineers are in short supply. A realistic hiring timeline from job posting to productive first month runs four to six months on average, and that assumes your recruitment process is tight. Your cluster complexity does not pause while you search.
Restructuring your K8s setup after getting this wrong is expensive. Migrating from a self-managed cluster back to a managed platform or vice versa is not a weekend project. It requires careful workload migration, network reconfiguration, and significant validation effort. Getting the decision right earlier costs less than correcting it later.
Key Takeaway: The hidden costs of a wrong K8s staffing decision accumulate on both sides. Over-hiring creates waste and attrition. Under-investing creates operational fragility and technical debt that compounds as your service count grows.
A Third Option: Managed K8s Operations With an External Engineering Partner
The binary framing of “hire versus managed K8s” misses the option that fits the most mid-market SaaS teams in practice: managed Kubernetes infrastructure with an external partner who owns the operational layer on top.
This model works as follows. You run your workloads on EKS, GKE, or AKS. The cloud provider handles the control plane. An external engineering team handles everything above that layer: Helm chart standards, RBAC governance, upgrade validation, observability configuration, incident response depth, and capacity planning. Your internal team focuses on application deployment and product velocity.
The operational coverage is comparable to a dedicated hire. The risk profile is better, because you are not dependent on one person who knows your entire cluster topology and whose departure would be a significant operational event. The ramp-up time is shorter, because a partner team with deep K8s experience already carries the pattern recognition that would take a new hire months to develop for your specific environment.
This model also scales without recruiting cycles. If your service count grows past the point where the external team’s scope needs to expand, that adjustment does not require posting a job description. You adjust the engagement. If your needs shrink during a product consolidation phase, you adjust accordingly without carrying fixed headcount costs.
For mid-market SaaS teams running between ten and one hundred services, this is often the highest-leverage option available. It delivers operational depth without key-person risk, at a cost structure that does not require justifying a full senior engineering salary before your cluster complexity demands it. Skyram’s managed DevOps engagement model works precisely this way, scoped Kubernetes operations ownership layered on top of your existing cloud infrastructure, with defined SLAs and clear transition documentation built in from the start.
How to Evaluate a Managed Kubernetes Partner vs. a Freelance K8s Hire
Whether you are evaluating an external engineering partner or a direct Kubernetes hire, the evaluation criteria overlap more than most hiring managers expect. The difference is in risk distribution and depth of institutional knowledge.
For a freelance K8s hire or direct employee, look for concrete evidence of production cluster management at similar service counts. Ask for specific examples of upgrade cycle management, incident response playbooks they have written, and RBAC models they have designed. Candidates who can articulate their approach to cost optimization through resource request right-sizing and autoscaling configuration will give you signal on operational depth versus surface-level familiarity.
Red flags on the hire side: candidates who lean heavily on managed platform defaults without explaining why, engineers who cannot describe a specific incident they diagnosed and resolved, and candidates who list Kubernetes as a skill but whose depth ends at deployment manifests and Helm installs.
For an external partner, the evaluation criteria shift toward team-level depth and process maturity. You want visibility into their current managed K8s client base and service count range. You want to understand their incident response SLAs and how those map to your production reliability requirements. Ask for a structured walkthrough of how they approach new cluster onboarding, RBAC governance, and upgrade cycle management. A credible partner describes this process in specific, tooling-grounded terms rather than generic DevOps language.
Also evaluate knowledge retention. With a hire, institutional knowledge lives with the person. With a partner, it should live in documentation, runbooks, and tooling configurations that persist if the engagement model changes. Ask explicitly how they handle knowledge transfer and what artifacts they maintain throughout the engagement. This is the question that separates partners with genuine operational discipline from vendors who deliver output without transferring understanding.
For SaaS companies that have both DevOps infrastructure requirements and growing cloud complexity, evaluating the SaaS solutions support model alongside Kubernetes-specific criteria gives you a clearer picture of how a partner handles the full infrastructure stack your product depends on, not just the orchestration layer in isolation.
Key Takeaway: The evaluation criteria for a K8s hire and a managed K8s partner overlap significantly. The differentiator is risk distribution, knowledge retention, and ramp-up speed. A partner carries team-level depth and institutional documentation that individual hires rarely match in the first six months.
Frequently Asked Questions
- What is the main difference between hiring a Kubernetes engineer and using a managed Kubernetes service?
A dedicated Kubernetes engineer owns the full operational layer of your cluster, including node management, upgrade cycles, RBAC governance, networking, and incident response. A managed Kubernetes service such as EKS, GKE, or AKS offloads the control plane and node lifecycle to the cloud provider but leaves application-level configuration, observability, security hardening, and namespace governance as internal responsibilities. The distinction is not hire versus no-hire. It is where ownership sits and how much internal K8s competency your team carries regardless of which model you choose.
- At what point does a mid-market SaaS company need a dedicated Kubernetes engineer?
Most mid-market SaaS teams running between ten and fifty microservices do not yet need a full-time Kubernetes hire. The operational complexity at that scale is better served by a managed platform paired with either a platform engineer or an external Kubernetes partner who owns the governance and operational layers. Above fifty services, with multiple teams deploying independently and custom resource configurations in play, a dedicated K8s engineer or specialist team starts to deliver ROI through tighter resource efficiency and faster incident resolution.
- What does managed Kubernetes not cover that most teams assume it does?
Managed Kubernetes platforms handle the control plane and, depending on configuration, node lifecycle management. They do not handle RBAC governance, namespace policy enforcement, observability stack setup, secrets management integration, image scanning, Helm chart standards, or application-level resource configuration. Teams frequently underestimate how much operational work sits above the control plane layer and remains their responsibility even on a fully managed platform.
- How do you avoid key-person dependency risk when hiring a Kubernetes engineer?
Key-person risk is the most significant structural vulnerability in the single-hire model. Mitigating it requires three practices: maintaining comprehensive runbooks and cluster documentation that a new engineer could inherit without institutional knowledge gaps, building RBAC and GitOps workflows that enforce configuration standards regardless of who executes them, and ensuring at least one other engineer on the team has meaningful K8s literacy to handle basic incident triage. Teams that rely entirely on one engineer’s memory of the cluster topology face significant operational risk at every performance review, flight risk assessment, or parental leave cycle.
- What should a VP of Engineering ask when evaluating an external managed Kubernetes partner?
Ask for specifics, not generalities. Request a walkthrough of their upgrade cycle management process and how they handle version compatibility validation for admission controllers and CNI plugins. Ask for their incident response SLA structure and examples of how they have managed production incidents for similar service counts. Evaluate their RBAC governance approach and how they document cluster configurations for knowledge transfer. Ask what artifacts they maintain throughout the engagement and how a transition would be handled if the relationship changed. A credible partner gives detailed, tooling-grounded answers to all of these questions without defaulting to generic DevOps language.
Ready to Stop Guessing on Your Kubernetes Strategy?
Your K8s infrastructure decisions compound. The right staffing model at ten services is not the right model at fifty, and the wrong model at either stage creates costs that are expensive to unwind.
If your SaaS platform is scaling past the point where your current K8s setup feels manageable but a full-time hire feels premature, a structured conversation about your cluster environment, service count, and operational requirements is the right next step.
The Kubernetes solutions team can walk through your current architecture and help you identify whether a managed operations model, a hybrid approach, or a scoped engagement fits your stage.

